Web Scraping with Parsel in Python: A Practical Guide
Learn to fetch HTML and extract clean, structured data with Parsel using CSS, XPath, and JMESPath, with runnable examples and fixes for common pitfalls.
Parsel is a Python library for selecting and extracting data from HTML, XML, and JSON that you already have. Use a separate HTTP client to fetch a webpage, then pass its response body to Parsel. CSS is convenient for common element and class queries; XPath handles document traversal and text cases; JMESPath selects from JSON. Parsel does not fetch pages, run a browser, or render JavaScript.
This guide shows the full workflow: install Parsel, fetch a page, extract structured fields, handle missing or repeated content, and diagnose common failures. It also explains when standalone Parsel is enough and when a crawler or browser-based capture tool fits better.
1. Install Parsel and prepare a project
Install the parsel package into the Python environment that will run your script:
python -m pip install parsel requestsThe package metadata currently lists Parsel 1.12.1 and Python 3.10 or newer; verify the current release and compatibility before pinning dependencies because these details can change. The project is distributed under the BSD-3-Clause license. See Parsel on PyPI and its usage documentation.
For repeatable deployments, pin the version you have reviewed in a requirements file, for example parsel==1.12.1, then update it deliberately. If your project already uses Scrapy, you may not need to install or construct selectors separately: Scrapy exposes Parsel selectors through each response.
2. Fetch a page, then parse its body
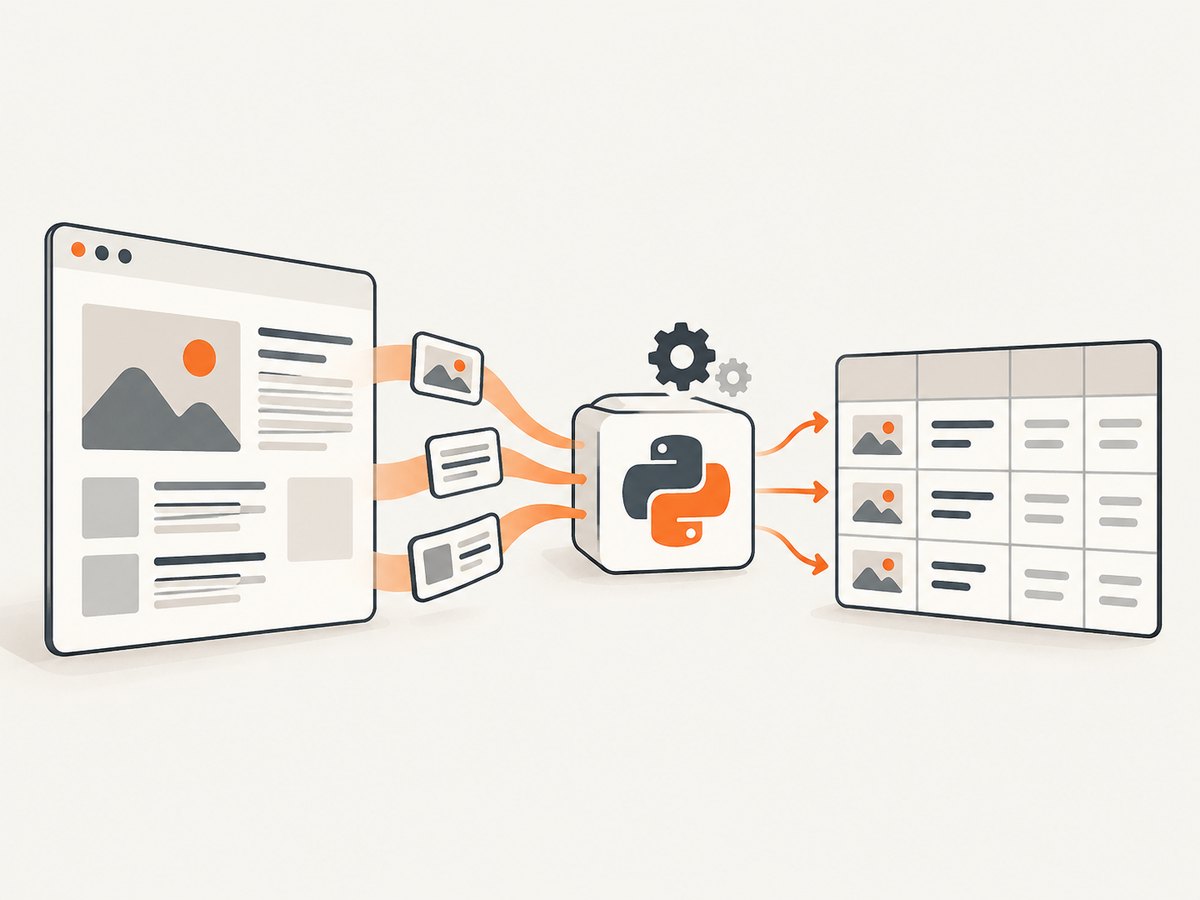
Parsel’s responsibility begins when markup or JSON is available. For a simple HTML page, Requests can perform the HTTP request and Parsel can parse the response body. This runnable example checks the HTTP status, follows normal redirects, sets a descriptive user agent, and extracts a title and links:
import requests
from parsel import Selector

url = "https://example.com/"
response = requests.get(
    url,
    headers={"User-Agent": "ExampleResearchBot/1.0 (contact: dev@example.com)"},
    timeout=(5, 20),
)
response.raise_for_status()

selector = Selector(text=response.text)
title = selector.css("title::text").get(default="").strip()
links = selector.css("a").xpath(
    "./@href"
).getall()

print({"title": title, "links": links})
Use a real contact address and identify your client appropriately when making requests. Follow the target site’s access rules, rate limits, and applicable terms. A request can succeed while returning a login page, bot check, or error page; inspect status, final URL, and a small part of the body when extraction unexpectedly returns nothing.
response.text uses Requests’ detected character encoding. If you have bytes and know the encoding, pass an explicit encoding or decode the bytes intentionally. Parsel also accepts response text directly with Selector(text=...). For XML, set the selector type to XML when appropriate:
from parsel import Selector

xml = "<catalog><item id='7'><name>Widget</name></item></catalog>"
selector = Selector(text=xml, type="xml")
print(selector.xpath("//item/@id").get())
print(selector.xpath("//item/name/text()").get())
3. Select elements with CSS or XPath
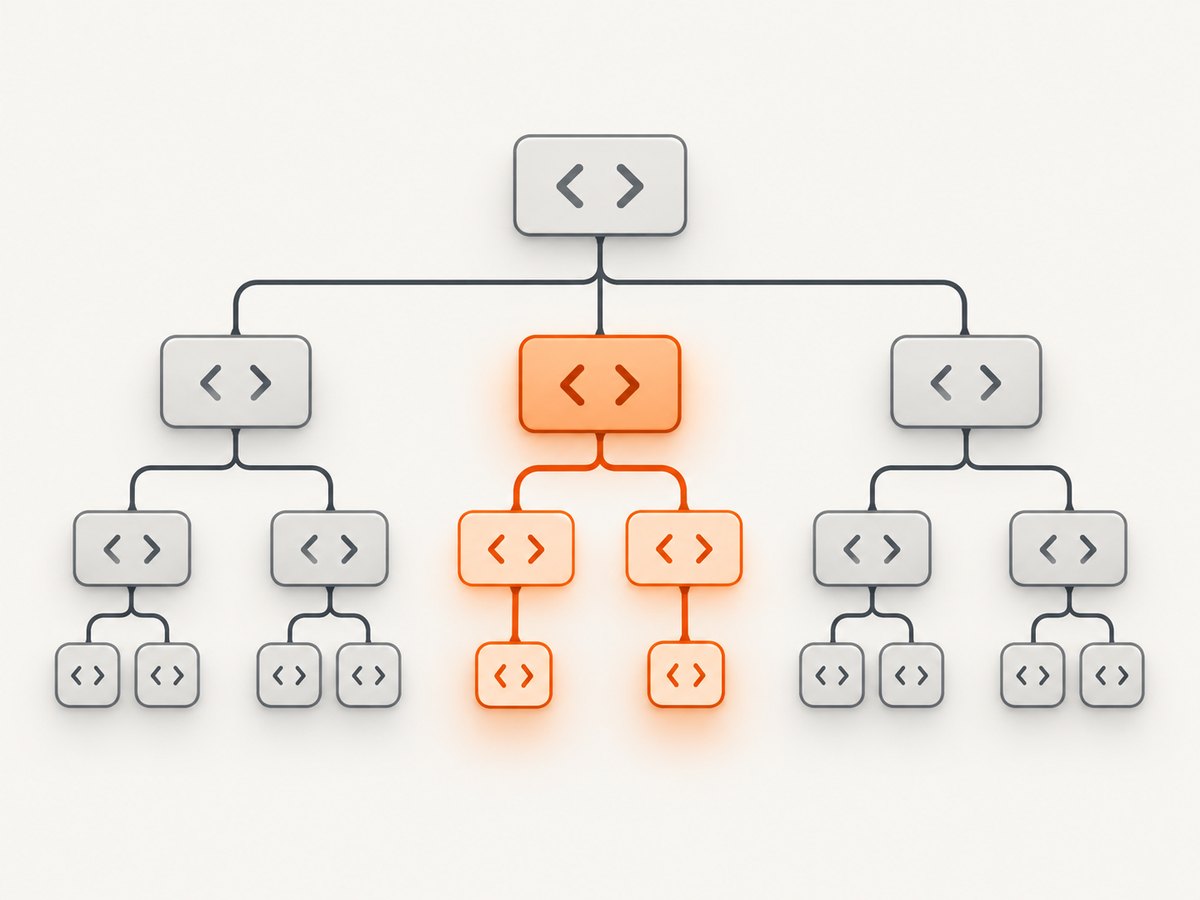
CSS works well for common element, class, and attribute relationships. Parsel adds scraping-oriented pseudo-elements to retrieve text and attributes directly:
from parsel import Selector

html = """<main>
  <article class="story featured">
    <h2>A useful guide</h2>
    <a href="/guides/parsel">Read more</a>
  </article>
</main>"""
sel = Selector(text=html)

heading = sel.css("article.story h2::text").get()
href = sel.css("article.story a::attr(href)").get()
print(heading, href)
::text and ::attr(name) are Parsel/Scrapy extensions, not portable standard CSS syntax. They may not work in unrelated selector libraries. CSS class selection such as .story correctly finds an element with multiple classes; exact matching against @class='story' can miss class="story featured", while substring matching can accidentally match another class name.
XPath is useful for document-relative navigation, XML, and extracting text from a node together with its descendants. A chained selection keeps the context of the current element when the XPath begins with .:
articles = sel.css("article.story")
for article in articles:
    heading = article.xpath(".//h2").xpath("string(.)").get(default="")
    href = article.xpath(".//a/@href").get()
    print({"heading": " ".join(heading.split()), "href": href})
The leading dot matters: .//a/@href searches within the current article. An expression such as //a/@href starts from the document root, which can return links outside that article. XPath’s string(.) includes descendant text; normalize-space(.) additionally trims and collapses whitespace.
4. Extract text, links, and attributes
A selector can return a first result or all results. .get() returns the first match, or None when there is no match; .getall() always returns a list. Supply a default to .get() when a missing value should become a known fallback.
title = sel.css("h1::text").get(default="Untitled")
all_titles = sel.css("h2::text").getall()
all_hrefs = sel.css("a::attr(href)").getall()
first_href = sel.css("a::attr(href)").get()

print(title)
print(all_titles)
print(all_hrefs)
This distinction is important when a page can contain zero, one, or many items. If your output schema expects a list, use .getall() even when you think there is usually one match. If you expect one value, decide how to handle None before transforming it.
Direct text selection can omit words inside nested elements. For example, <p>Read <strong>this</strong> now</p> has several text nodes. To get the complete visible text, select the paragraph and use XPath:
paragraph_text = sel.css("p").xpath("normalize-space(.)").get(default="")Text and attribute values are strings, not cleaned domain data. Trim whitespace, normalize dates, validate URLs, and convert numeric fields explicitly. A link’s href may be relative; resolve it against the response URL before storing or requesting it:
from urllib.parse import urljoin

absolute_links = [urljoin(response.url, href) for href in all_hrefs]
5. Parse JSON with JMESPath
When the input is JSON rather than HTML, create a JSON selector and use JMESPath expressions. You can also select a JSON payload embedded inside a script element, then apply JMESPath to that selected content:
from parsel import Selector

payload = {
    "products": [
        {"name": "Notebook", "price": 8.5},
        {"name": "Pen", "price": 1.25},
    ]
}
json_selector = Selector(text='{"products":[{"name":"Notebook","price":8.5},{"name":"Pen","price":1.25}]}', type="json")
print(json_selector.jmespath("products[*].name").getall())

html = """<script type="application/json">
{"products":[{"name":"Notebook"}]}
</script>"""
embedded = Selector(text=html)
script_text = embedded.css('script[type="application/json"]::text').get()
if script_text:
    data_selector = Selector(text=script_text, type="json")
    print(data_selector.jmespath("products[*].name").getall())
Use a JSON parser or Parsel’s JSON support for structure rather than a regular expression that tries to match nested braces. Regular expressions are available for selected text when you need a focused pattern, but they are a poor replacement for parsing a document’s structure.
6. Can I use Parsel without Scrapy?
Yes. Standalone Parsel is suitable when another component already supplies the document body, as in the Requests example above, or when you’re parsing saved fixtures. Scrapy is useful when the task also needs a crawler’s request and response workflow. Scrapy’s selectors are a thin integration around Parsel: in a callback, response.css(...) and response.xpath(...) are convenient shortcuts over the parsed response.
Choose based on the job. Use Parsel alone for extraction from supplied HTML, XML, or JSON. Use Scrapy when you need a crawler framework to coordinate requests and responses. Neither choice makes a normal HTTP request execute page JavaScript. If the values only appear after client-side rendering, determine whether the page exposes a permitted data endpoint or whether a browser-rendering approach is required.
7. Troubleshooting common extraction problems
| Symptom | Likely cause | Fix |
|---|---|---|
.get() returns None |
The selector found no matching node, or the response is not the expected page. | Inspect status, final URL, and a short body sample. Check the selector against the actual markup and provide a default where absence is valid. |
| Only one item is returned | .get() intentionally returns the first match. |
Use .getall() for all matching values or iterate over selected item nodes. |
| Some words are missing from extracted text | ::text or XPath text() selects direct text nodes, excluding nested tags. |
Select the containing element and use string(.) or normalize-space(.). |
| Nested XPath returns unrelated values | A leading slash or // can make the expression document-relative. |
Use a relative expression such as .//a/@href from the nested selector. |
| Class selector misses an element | The markup has multiple class names and the query assumes an exact class attribute. | Use CSS .class-name rather than exact attribute equality. |
| Expected content is absent from the body | The page renders it with JavaScript after the initial response. | Check the response itself and permitted data sources. Parsel parses supplied markup; use a browser renderer or a rendered capture if browser execution is necessary. |
| Tag-like text inside a script appears confusing | Script and style contents are parsed as text rather than normal descendant elements. | Select the script text, then parse its JSON or apply a narrow text extraction step. |
| Only one root is searched in malformed HTML | For a multi-root document, CSS selection applies from the first root. | When all roots matter, use XPath to select the roots explicitly before applying CSS. |
8. Performance, reliability, and cost
Parsel only handles selection and extraction, so the main reliability boundaries are upstream fetching and downstream validation. Set connect and read timeouts in the HTTP client, check status codes, and distinguish a successful HTTP response from a page that actually contains the expected data. For repeated requests, add deliberate pacing and retries that respect the site’s rules; avoid retry loops that amplify load during an outage.
For stable extraction, keep representative HTML fixtures and validate required fields and types before saving results. Select only the nodes and fields you need, avoid repeated broad queries in inner loops, and record enough context to diagnose changes: source URL, fetch time, response status, and which required field was absent. These are workflow recommendations, not Parsel performance benchmarks.
Parsel itself is an open-source dependency, so there is no Parsel API request charge. Your costs and resource use come from infrastructure and any services you use to fetch or render pages. Plain HTTP retrieval is usually simpler than launching a browser, but it cannot provide content that exists only after browser JavaScript runs. Browser capture services can be useful for a rendered visual artifact or browser-dependent page; a screenshot is not a substitute for structured extraction of arbitrary data.
9. Or skip the browser setup
If the page’s useful content depends on browser behavior and you need a rendered screenshot or PDF rather than parsed fields, ScreenshotNeo offers a one-request website screenshot API and MCP server. It does not replace Parsel for extracting structured records; it handles browser capture. Its clean-shot flow accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets, with each step configurable. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers say which page verdict and billing outcome applied. AI agents can use its MCP server tools: take_screenshot, get_page_info, and capture_pdf.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
See the ScreenshotNeo API documentation for request options and setup. The API supports PNG, JPEG, WebP, or PDF output, full-page and element capture, device presets and custom viewports, CSS and JavaScript, waiting rules, custom headers and cookies, request blocking, caching, signed links, async jobs, bulk requests, and more. There is a usage API and OpenAPI spec. Plans include 1,000 screenshots per month free with no card; paid plans start at $5 for 3,000, and every feature is on every plan. Yearly billing gives two months free.
Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed; an MCP server lets AI agents take screenshots; 1,000 screenshots a month are free with no card and paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
10. Frequently asked questions
How do I use Parsel in Python to scrape a webpage?
Fetch the page with an HTTP client such as Requests, check the response, create Selector(text=response.text), then use CSS or XPath to select data. Parsel does the extraction, not the network request.
How do I select elements with CSS or XPath in Parsel?
Use sel.css(".product h2::text") for a straightforward CSS query and sel.xpath("//article//h2/text()") for XPath traversal. Parsel’s ::text and ::attr(name) are library extensions.
How do I extract text, links, and attributes with Parsel?
Use ::text for selected text nodes and ::attr(href) for an attribute. Use XPath normalize-space(.) when you need all descendant text normalized into one string.
Does Parsel run JavaScript or crawl links automatically?
No. It parses a supplied document. Fetching pages, scheduling requests, and rendering JavaScript require other components.
Can I use Parsel without Scrapy?
Yes. Import Selector directly and pass it markup or JSON. Scrapy adds a broader crawling workflow and integrates Parsel selectors with response objects.
When should I use a screenshot API instead?
Use one when the deliverable is a rendered screenshot or PDF, or when you need browser execution for visual capture. For structured field extraction from an available document body, Parsel remains the relevant tool.
Sources
- Parsel on PyPI — package metadata, version, Python requirement, and supported query types.
- Parsel Usage documentation — selector construction, extraction, CSS extensions, XPath, and pitfalls.
- Scrapy Selectors documentation — integration with Parsel and response shortcuts.
- Parsel release history — compatibility changes over time.


