Common Questions About Web Scraping with Cheerio
Learn what Cheerio can scrape, how to load HTML, fix empty selectors, handle JavaScript pages, choose parsers, and crawl responsibly.
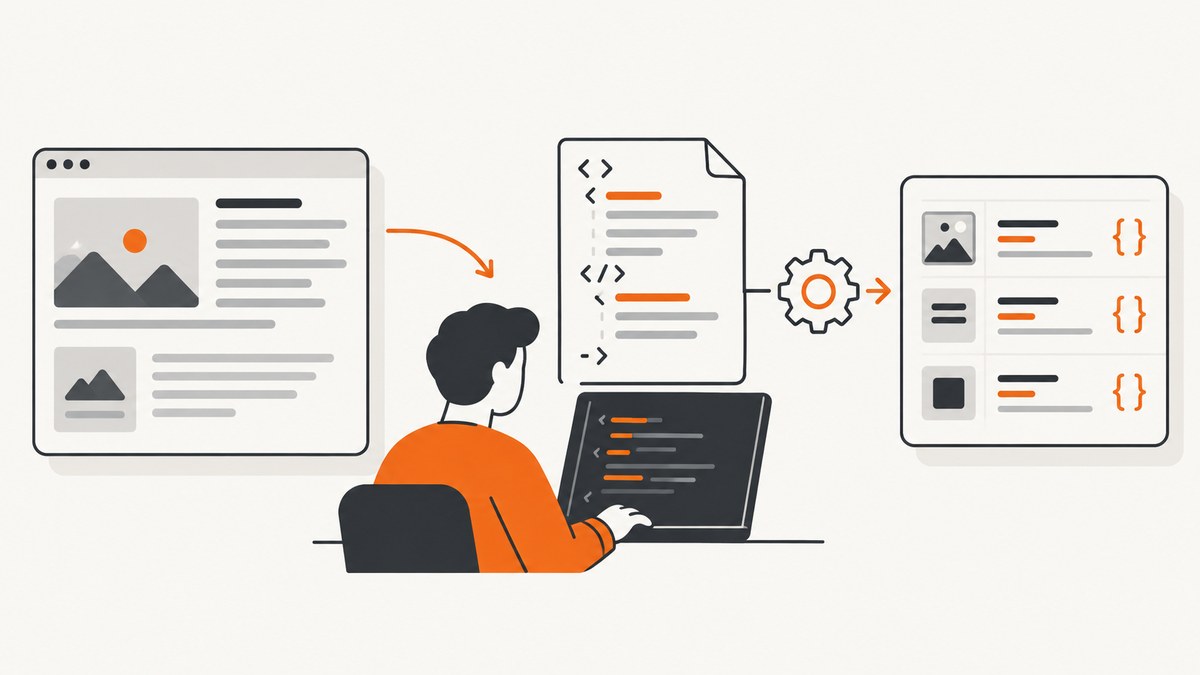
Direct answer: Cheerio is a Node.js library for parsing HTML and XML and querying the resulting document with a jQuery-like API. It is fast and useful when the HTML you need is already available. It is not a browser: it does not visually render pages, load external resources, apply CSS, or execute JavaScript. The official documentation summarizes this plainly: “Cheerio is not a web browser.”
That distinction explains most Cheerio questions. If a server returns the product list, article text, links, or metadata in its HTML, Cheerio can extract it. If a page creates that content only after JavaScript runs, Cheerio will not see it unless you first obtain the rendered data or use browser automation.
What is Cheerio?
Cheerio parses supplied markup into a traversable document. Its API resembles jQuery, so you can select nodes with CSS selectors, read text and attributes, walk descendants, and serialize modified markup. It runs in Node.js and is commonly used for one-off extraction scripts, crawlers, feed processing, testing, and HTML transformations.

Cheerio does not provide a browser session. It has no layout engine, viewport, cookies from a normal browsing session, visual rendering, network waterfall, or JavaScript runtime for the page being parsed. You must separately fetch the HTML or provide it from a file, buffer, stream, or authorized endpoint.
How do I install Cheerio?
Install it in a Node.js project with npm:
mkdir cheerio-scraper
cd cheerio-scraper
npm init -y
npm install cheerio
The current official introduction lists Node.js 22.19 or later. Check the Cheerio introduction and your deployment runtime before choosing a Node version. Cheerio supports ESM and CommonJS.
ESM example
import * as cheerio from 'cheerio';

const html = '<ul><li class="item">One</li><li class="item">Two</li></ul>';
const $ = cheerio.load(html);

const items = $('.item').map((_, element) => $(element).text().trim()).get();
console.log(items);
CommonJS example
const cheerio = require('cheerio');

const $ = cheerio.load('<h1>Hello</h1>');
console.log($('h1').text());
How do I load HTML into Cheerio?
Choose the loading method based on the data you have. The loading guide documents these Node.js APIs:
| Method | Use it when | Input |
|---|---|---|
cheerio.load(markup) |
You already have decoded HTML text | String |
cheerio.loadBuffer(buffer) |
Encoding is uncertain or you have raw bytes | Buffer |
cheerio.stringStream() |
Decoded text arrives incrementally | Text stream |
cheerio.decodeStream() |
Raw byte chunks arrive incrementally | Byte stream |
cheerio.fromURL(url) |
Cheerio should fetch a URL in Node.js | URL |
Only load is available in the browser build; the other methods depend on Node.js APIs.
Load a local file
import { readFile } from 'node:fs/promises';
import * as cheerio from 'cheerio';

const markup = await readFile('./page.html', 'utf8');
const $ = cheerio.load(markup);

for (const link of $('a[href]').toArray()) {
  console.log({ text: $(link).text().trim(), href: $(link).attr('href') });
}
Fetch a URL yourself
Fetching separately gives you explicit control over headers, timeouts, status checks, retries, and response limits:
import * as cheerio from 'cheerio';

const controller = new AbortController();
const timer = setTimeout(() => controller.abort(), 15000);

try {
  const response = await fetch('https://example.com', {
    headers: { 'user-agent': 'ExampleResearchBot/1.0' },
    signal: controller.signal
  });
  if (!response.ok) throw new Error(`HTTP ${response.status}`);
  const html = await response.text();
  const $ = cheerio.load(html);
  console.log($('title').text().trim());
} finally {
  clearTimeout(timer);
}
Use fromURL
import * as cheerio from 'cheerio';

const $ = await cheerio.fromURL('https://example.com');
console.log($('title').text().trim());
For production crawlers, the explicit fetch pattern is often easier to instrument because you can record status codes, response sizes, redirects, and retry decisions before parsing.
How do I select and extract data?
The returned $ function accepts CSS selectors. Use familiar selectors such as h2.title, article a[href], attribute selectors, and descendant selectors.
import * as cheerio from 'cheerio';

const html = `
  <article class="post" data-id="42">
    <h2 class="title">Cheerio basics</h2>
    <p class="summary">Parse HTML with Node.js.</p>
    <a class="read" href="/cheerio">Read</a>
  </article>`;

const $ = cheerio.load(html);
const post = $('.post');

const result = {
  id: post.attr('data-id'),
  title: post.find('.title').text().trim(),
  summary: post.find('.summary').text().trim(),
  href: post.find('a.read').attr('href')
};

console.log(result);
Useful operations include text() for text content, html() for inner markup, attr(name) for attributes, find(selector) for scoped traversal, each() for iteration, and map(...).get() for arrays. Cheerio also supports writing methods, so you can remove nodes, change attributes, or normalize markup before serializing with $.html().
Scope selectors deliberately
A selector passed to find() is relative to the current selection. This is useful for repeated records:
const rows = $('.product').map((_, element) => {
  const row = $(element);
  return {
    name: row.find('.name').text().trim(),
    price: row.find('[data-price]').attr('data-price') ?? null
  };
}).get();
Be careful with text(): if your selection contains script or style nodes, their text can be included. Select the narrowest content node or remove unwanted elements first:
const content = $('.article').clone();
content.find('script, style, .advertisement').remove();
const cleanText = content.text().replace(/\s+/g, ' ').trim();
Why is Cheerio returning empty results?
Empty selections usually mean the selector does not match the HTML Cheerio received. Debug the input before changing the selector:
- Save or print a bounded portion of the response.
- Check the HTTP status and final URL after redirects.
- Search the received HTML for a distinctive word or attribute.
- Test the selector against that exact HTML, not a browser’s later DOM.
- Check whether your selector is scoped under the correct parent.
console.log('bytes:', Buffer.byteLength(html));
console.log('has target text:', html.includes('Expected product'));
console.log($('body').html()?.slice(0, 1000));
console.log('matches:', $('.product').length);
A browser developer-tools Elements panel shows the post-JavaScript DOM. The HTTP response may contain only a shell such as a root element and script tags. Cheerio parses the response, so client-generated content is absent. Cheerio’s troubleshooting guidance specifically calls out React- and Vue-generated content.
Can Cheerio scrape JavaScript-rendered pages?
No. Cheerio does not execute the page’s JavaScript or render its interface. You have three practical choices:
- Find an authorized server-rendered page or documented data endpoint and parse that response.
- Use browser automation when the data genuinely requires JavaScript, interaction, authentication, or a rendered DOM.
- Use a screenshot service when your goal is a visual capture rather than structured data.
Do not assume that copying a browser URL into fromURL makes Cheerio a browser. It only fetches and parses the returned bytes.
Which parser should I use: parse5 or htmlparser2?
Cheerio uses parse5 by default for HTML. The documentation describes it as browser-oriented and standards-conforming. It is the sensible default when you want behavior close to normal HTML parsing.
htmlparser2 is available for XML and for workloads that benefit from faster, lower-memory, more forgiving parsing. Its error correction can differ from browser parsing, so validate the output if malformed markup matters.
import * as cheerio from 'cheerio';

const $ = cheerio.load(xmlOrHtml, {
  xml: true
});
console.log($.root().children().length);
Choose parse5 for ordinary web HTML and compatibility. Choose htmlparser2 when XML support, permissive parsing, or resource usage is the stronger requirement. Keep the parser choice consistent across a pipeline so selector behavior does not change unexpectedly.
How do I build a reliable Cheerio scraper?
Validate responses
Check status codes, content type, redirects, and a reasonable maximum response size. A login page or rate-limit page can be valid HTML while containing none of the data you expected.
Use explicit timeouts and bounded concurrency
Set an abort timeout for every request and process a limited number of URLs at once. Unbounded concurrency increases failures and can violate a site’s operating expectations.
Cache and deduplicate
Cache responses when your use permits it, avoid requesting the same URL repeatedly, and normalize URLs before queueing them. Caching also makes debugging reproducible.
Record extraction health
Track requested URLs, status codes, response bytes, parse errors, match counts, and missing required fields. A scraper that returns an empty array successfully can be more dangerous than one that fails loudly.
Keep selectors resilient
Prefer stable attributes, semantic elements, and scoped selectors. Long chains of generated class names are fragile. Add a fixture containing representative markup to your project and run extraction against it after selector changes.
Performance and cost considerations
Cheerio is generally lightweight because it parses markup without launching a browser. Your total cost and latency still depend on downloading the page, redirects, server response time, parser choice, response size, and concurrency. Streaming APIs can reduce peak memory when data arrives incrementally, while buffers are useful when encoding detection is important.
For large crawls, measure end-to-end time rather than assuming parsing is the bottleneck. Reduce duplicate requests, cache responsibly, cap concurrency, and avoid retaining complete documents after extraction. If a page must be rendered in a browser, account for browser startup and resource loading separately from Cheerio parsing.
Or skip the browser setup
If your goal is a clean visual capture, ScreenshotNeo provides a website screenshot API and MCP server. One GET request returns PNG, JPEG, WebP, or PDF. It accepts 63 options, including full-page capture with lazy images loaded, CSS-selector element capture, dark mode, device presets, custom viewports, retina scale, PDF paper and margin settings, custom CSS and JavaScript, clicks, waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, bulk capture, and a usage API. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
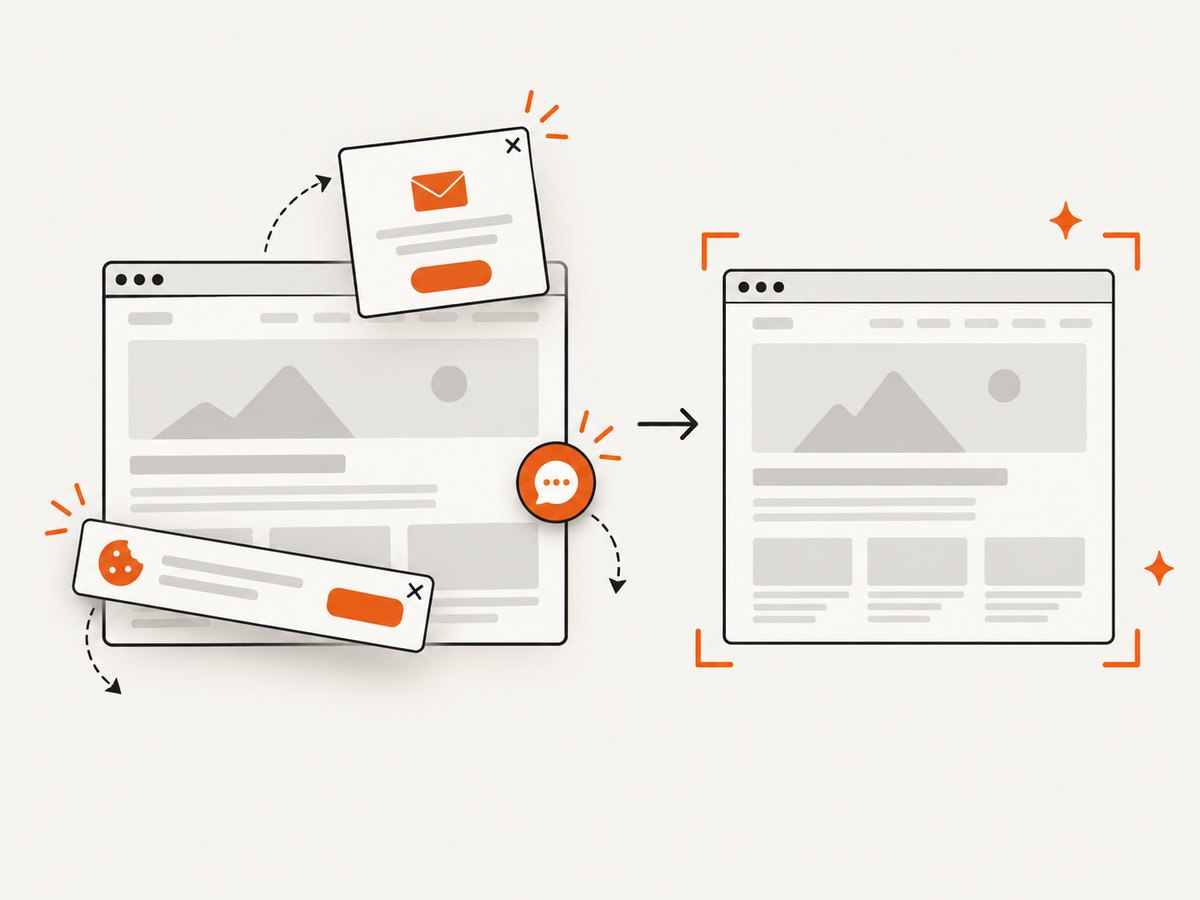
const bytes = await res.arrayBuffer();Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and billing result. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
Is web scraping with Cheerio legal?
There is no universal yes-or-no answer. The outcome depends on jurisdiction, contract terms, authentication, copyright, privacy, the data collected, and how you use it. Review a site’s terms, identify your client, limit request rates, cache where appropriate, and collect only what your authorization and purpose require.
RFC 9309 defines the Robots Exclusion Protocol. A site’s /robots.txt communicates crawler rules, but the RFC states that “These rules are not a form of access authorization.” Treat robots.txt and terms as operational constraints that require review, not as a substitute for permission or a legal determination.
Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
Cannot find package 'cheerio' |
Dependency is missing or command ran in another directory | Run npm install cheerio in the project and verify the working directory. |
| Every selector has length zero | Wrong selector, wrong scope, or content is JavaScript-generated | Inspect the exact response HTML and compare it with the selector. |
| Unexpected text includes code | text() includes script or style descendants |
Select a narrower node or remove script and style. |
| Malformed output differs from a browser | Parser behavior differs, especially with malformed HTML | Use parse5 for browser-like HTML parsing or evaluate htmlparser2 deliberately. |
| Request succeeds but data is a login page | Authentication, cookies, or redirects are missing | Confirm authorization and inspect status, final URL, and response body before parsing. |
| Intermittent timeouts | Slow origin, rate limiting, or unbounded concurrency | Add an abort timeout, bounded retries with backoff, caching, and lower concurrency. |
FAQ
Does Cheerio support CSS selectors?
Yes. The returned $ function accepts CSS selectors and supports scoped traversal with methods such as find().
Can Cheerio click buttons or submit forms?
No. It parses markup and transforms a document; it does not provide browser interaction or JavaScript execution.
Should I use Cheerio in a browser bundle?
The browser build provides load. Node.js-only loading methods such as URL and stream helpers depend on Node APIs.
How can I tell whether a page is server-rendered?
Fetch the HTML and search it for the content you need. If the browser shows the content but the response does not contain it, client-side rendering is involved.
What is the safest first parser choice?
Use parse5 for ordinary web HTML. Consider htmlparser2 when XML, permissive parsing, or lower memory use is the explicit requirement.