Web Scraping With PHP: A Beginner’s Guide
Learn a reliable PHP scraping pipeline: fetch HTML, parse it with DOMXPath or DomCrawler, handle failures, and know when JavaScript needs a browser.
PHP can scrape HTML with its built-in HTTP tools and several well-supported Composer packages. The basic pipeline is straightforward:
- Request a permitted URL.
- Check the response and decode the document.
- Parse the HTML.
- Select fields with XPath or CSS selectors.
- Normalize values and URLs.
- Store or emit structured data.
This guide starts with a complete, runnable example and then covers Guzzle, DOMDocument, DOMXPath, Symfony DomCrawler, BrowserKit, JavaScript-rendered pages, reliability, performance, and troubleshooting. Use conservative request rates and only collect data you are allowed to access. Terms, privacy, copyright, contracts, and jurisdiction can affect whether a particular project is permitted; robots.txt alone does not settle that question.
1. Fetch one page with PHP
For a first static page, PHP’s HTTP stream wrapper is enough. Set an explicit user agent, apply a timeout, inspect the status line, and verify that you received HTML rather than assuming a successful connection means a valid document.
<?php
$url = 'https://example.com/';

$context = stream_context_create([
    'http' => [
        'method' => 'GET',
        'timeout' => 15,
        'ignore_errors' => true,
        'header' => "User-Agent: BeginnerPhpScraper/1.0 (+https://example.com/contact)\r\nAccept: text/html,application/xhtml+xml\r\n",
    ],
]);

$html = @file_get_contents($url, false, $context);
if ($html === false) {
    throw new RuntimeException('Request failed');
}

$status = $http_response_header[0] ?? '';
if (!preg_match('/HTTP\/\S+\s+(\d{3})/', $status, $match)) {
    throw new RuntimeException('Could not read HTTP status');
}
$code = (int) $match[1];
if ($code < 200 || $code >= 400) {
    throw new RuntimeException("Unexpected HTTP status: $code");
}

$contentType = '';
foreach ($http_response_header as $header) {
    if (stripos($header, 'Content-Type:') === 0) {
        $contentType = trim(substr($header, strlen('Content-Type:')));
    }
}
if ($contentType !== '' && stripos($contentType, 'html') === false) {
    throw new RuntimeException("Expected HTML, received $contentType");
}

echo 'Downloaded ' . strlen($html) . " bytes\n";
PHP can also be configured with a default user agent in php.ini, but setting it on the request makes the scraper’s behavior explicit. The stream wrapper is convenient for one-off requests; cURL or Guzzle is usually easier when you need redirects, retries, cookies, concurrency, or richer error details.
2. Parse HTML with DOMDocument and DOMXPath
DOMDocument and DOMXPath expose the fundamentals directly and tolerate many imperfect documents. Suppress parser warnings while loading untrusted HTML, then restore the previous error handler.
<?php
libxml_use_internal_errors(true);
$dom = new DOMDocument();
$dom->loadHTML($html, LIBXML_NOERROR | LIBXML_NOWARNING);
libxml_clear_errors();

$xpath = new DOMXPath($dom);
$records = [];
foreach ($xpath->query('//article') as $article) {
    $titleNode = $xpath->query('.//h2|.//h3', $article)->item(0);
    $linkNode  = $xpath->query('.//a[@href]', $article)->item(0);
    $title = $titleNode ? trim(preg_replace('/\s+/', ' ', $titleNode->textContent)) : '';
    $href  = $linkNode ? trim($linkNode->getAttribute('href')) : '';
    if ($title !== '') {
        $records[] = ['title' => $title, 'url' => $href];
    }
}

foreach ($records as $record) {
    printf("%s\t%s\n", $record['title'], $record['url']);
}
XPath patterns you will use often
| Goal | XPath |
|---|---|
| All links | //a[@href] |
| Element by ID | //*[@id="main"] |
| Class token | //*[contains(concat(" ", normalize-space(@class), " "), " card ")] |
| Text under a heading | //h2 |
| Relative query inside a node | .//a |
Always use a relative expression beginning with . when querying inside an individual node. Normalize whitespace, treat missing nodes as normal, and avoid selectors tied to generated class names.
3. Use Symfony DomCrawler for readable selectors
The Symfony DomCrawler component eases navigation for HTML and XML documents and provides CSS selectors, XPath filtering, text and attribute extraction, and iteration helpers. Install it with Composer:
composer require symfony/dom-crawler symfony/css-selectorEquivalent extraction code is shorter and easier to maintain:
<?php
require __DIR__ . '/vendor/autoload.php';

use Symfony\Component\DomCrawler\Crawler;

$crawler = new Crawler($html, $url);
$rows = $crawler->filter('article')->each(
    fn (Crawler $node) => [
        'title' => trim($node->filter('h2, h3')->text('')),
        'url'   => $node->filter('a[href]')->attr('href'),
    ]
);

foreach ($rows as $row) {
    if ($row['title'] !== '') {
        print_r($row);
    }
}
Useful methods include filter(), filterXPath(), attr(), text(), extract(), and each(). DomCrawler is designed for navigation and extraction, rather than re-dumping a complete, modified DOM.
4. Fetch with Guzzle
Install Guzzle with Composer:
composer require guzzlehttp/guzzleGuzzle can use cURL or PHP’s stream handler when cURL is unavailable. Its response object makes status codes, headers, redirects, and timeouts explicit.
<?php
require __DIR__ . '/vendor/autoload.php';

use GuzzleHttp\Client;
use GuzzleHttp\Exception\GuzzleException;

$client = new Client([
    'timeout' => 20,
    'connect_timeout' => 8,
    'allow_redirects' => ['max' => 5, 'strict' => true],
    'headers' => [
        'User-Agent' => 'BeginnerPhpScraper/1.0 (+https://example.com/contact)',
        'Accept' => 'text/html,application/xhtml+xml',
    ],
]);

try {
    $response = $client->get('https://example.com/');
    $status = $response->getStatusCode();
    $type = $response->getHeaderLine('Content-Type');
    $html = (string) $response->getBody();
    if ($status < 200 || $status >= 400 || stripos($type, 'html') === false) {
        throw new RuntimeException("Unexpected response: $status $type");
    }
} catch (GuzzleException $e) {
    throw new RuntimeException('HTTP request failed: ' . $e->getMessage(), 0, $e);
}
5. Normalize URLs, encoding, and values
Scraped values are rarely ready for storage. Resolve relative links against the page URL, decode entities, collapse whitespace, and preserve the original value when normalization could lose information.
<?php
function absoluteUrl(string $base, string $href): string {
    if ($href === '' || str_starts_with($href, '#')) return $base;
    if (preg_match('~^https?://~i', $href)) return $href;
    $parts = parse_url($base);
    $origin = ($parts['scheme'] ?? 'https') . '://' . ($parts['host'] ?? '');
    if (str_starts_with($href, '/')) return $origin . $href;
    $path = $parts['path'] ?? '/';
    $dir = rtrim(str_replace('\\', '/', dirname($path)), '/');
    return $origin . ($dir ? $dir . '/' : '/') . ltrim($href, '/');
}

function cleanText(?string $value): string {
    return trim(preg_replace('/\s+/u', ' ', html_entity_decode($value ?? '', ENT_QUOTES | ENT_HTML5, 'UTF-8')));
}
For difficult encodings, inspect the response’s charset and convert deliberately with mb_convert_encoding. Do not blindly convert already valid UTF-8. Keep dates and prices as raw strings until you know the source format and locale.
6. Forms, links, and multi-page workflows
Symfony BrowserKit simulates browser behavior: it can make requests, click links, submit forms, issue JSON requests, and make XMLHttpRequest-style requests. It is useful when the data requires a sequence of ordinary HTTP requests. It does not execute arbitrary JavaScript or render a client-side application by itself.
composer require symfony/browser-kit symfony/dom-crawler symfony/css-selector<?php
use Symfony\Component\BrowserKit\HttpBrowser;
use Symfony\Component\HttpClient\HttpClient;
$browser = new HttpBrowser(HttpClient::create([
'headers' => ['User-Agent' => 'BeginnerPhpScraper/1.0']
]));
$crawler = $browser->request('GET', 'https://example.com/login');
$form = $crawler->selectButton('Search')->form([
'q' => 'php',
]);
$results = $browser->submit($form);
$links = $results->filter('a.result')->each(fn ($node) => $node->attr('href'));
Store cookies only when the target permits this workflow, and avoid submitting forms that change state unless you have explicit authorization.
7. When JavaScript renders the data
A plain HTTP response can differ from what a browser displays. A page may return an empty shell and fill it through JavaScript, or a bot-protection system may serve a challenge instead of content. First inspect the downloaded HTML and the browser’s network requests. Prefer an official API or an authorized rendering method. Do not attempt to bypass access controls.
If you control the site, expose a stable JSON endpoint or server-rendered HTML. If you do not, check the provider’s terms and use an allowed API. BrowserKit is not a general JavaScript engine, so adding more XPath will not create content that was never in the response.
8. Pagination, duplicates, and polite crawling
- Find the next-page link or documented page parameter.
- Track canonical URLs in a set before requesting them.
- Set a maximum page count and a total item limit.
- Pause between requests and back off after 429 or 503 responses.
- Persist progress so a crash does not restart the crawl.
<?php
$seen = [];
$url = 'https://example.com/articles';
for ($page = 1; $page <= 20 && $url; $page++) {
    if (isset($seen[$url])) break;
    $seen[$url] = true;
    // fetch, parse, and persist records here
    usleep(500_000);
    $url = null; // replace with a validated, permitted next URL
}
9. Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| 403 or 429 | Access policy, rate limit, or missing authorization | Slow down, identify your client, use an official API, and confirm permission. |
| 200 but no records | Wrong selector or JavaScript-generated content | Save the raw response, inspect it, then choose a selector or authorized rendering/API. |
| Malformed-document warnings | Real-world HTML is not strict XML | Use LIBXML_NOERROR | LIBXML_NOWARNING, clear errors, and test selectors against fixtures. |
| Broken accented characters | Unknown or mismatched charset | Read the charset header/meta tag and convert once to UTF-8. |
| Relative links are unusable | Stored /path or ../path without a base |
Resolve against the response URL before storing. |
| Timeouts | Slow origin, blocked resource, or overloaded worker | Use connect and total timeouts, retry only transient failures with backoff, and cap work per URL. |
| Duplicate rows | Pagination overlap or repeated cards | Deduplicate by canonical URL or a stable source ID. |
| Selector suddenly fails | Markup changed or generated class names changed | Prefer semantic elements and data attributes; add fixture tests and monitor empty-result rates. |
10. Performance, reliability, and cost
Parsing is usually cheap compared with network time. Reuse a Guzzle client, limit concurrency to what the target permits, stream large responses when appropriate, and cache unchanged pages with a clear expiration policy. Record URL, timestamp, status, content type, duration, byte count, parser version, and item count. These fields make failures diagnosable.
Retries should be narrow: retry connection failures and selected 5xx responses, not authentication errors or most 4xx responses. Use exponential backoff with jitter. Validate extracted fields before writing them, and write checkpoints transactionally so partial pages do not corrupt a dataset.
11. Or skip the browser setup
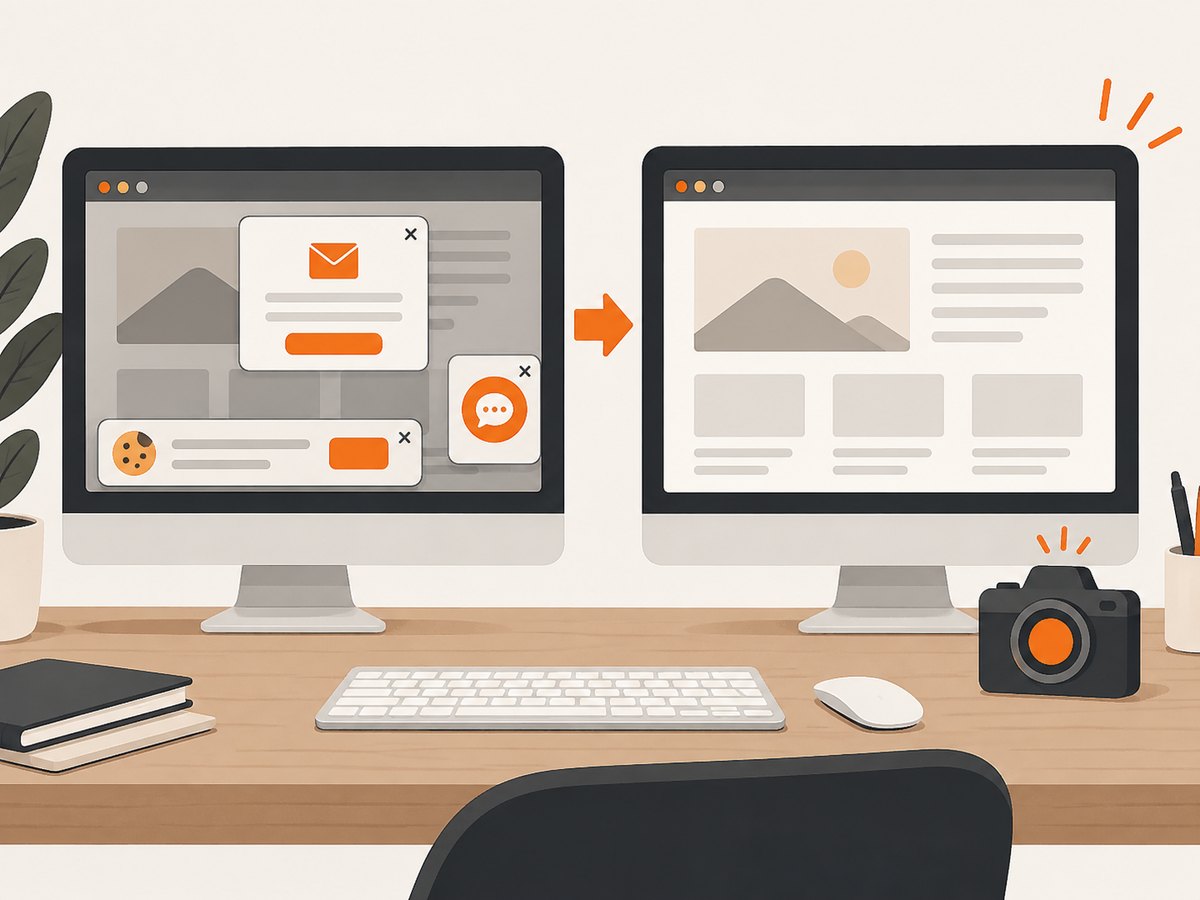
When you need a clean screenshot or PDF rather than extracted fields, ScreenshotNeo provides a single GET request. Its API accepts the URL and returns PNG, JPEG, WebP, or PDF. Cookie and consent banners, newsletter popups, and chat widgets are removed before capture; each step can be disabled. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing result.
See the ScreenshotNeo API documentation for all options, including full-page capture, CSS selectors, device presets, dark mode, custom CSS and JavaScript, waits, blocking rules, headers, cookies, geolocation, caching, signed links, asynchronous jobs, bulk capture, and PDF settings.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo also provides an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
12. FAQ
Can PHP scrape HTML?
Yes. The stream wrapper, cURL, or Guzzle can fetch HTML, and DOMDocument, DOMXPath, or DomCrawler can parse it.
Should I choose cURL or Guzzle?
cURL is a low-level, widely available transport with strong concurrency support. Guzzle adds a consistent PHP API, middleware, and a stream fallback when cURL is unavailable.
Is CSS or XPath better?
CSS selectors are often easier to read; XPath is more expressive for relationships and text conditions. DomCrawler supports both.
Why does my script see less than Chrome?
The browser may execute JavaScript, make additional API calls, retain cookies, or receive different content. Inspect the initial response and use an official API or authorized rendering solution when necessary.
How do I keep a scraper from breaking?
Use semantic selectors, fixtures, validation, request limits, structured logs, and alerts when result counts or required fields change.


