How to Use wget to Download Web Pages from Python
Use Python’s subprocess API to run wget safely, save page assets, handle errors, and know when urllib, Requests, or ScreenshotNeo is a better fit.

Short answer: call GNU Wget with Python’s subprocess.run(), passing arguments as a list. For a page that should work offline, start with --page-requisites, --convert-links, and --adjust-extension. Keep shell=False (the default), set a timeout, and handle nonzero exit codes.
Wget is an external command-line program. Python does not download a page through Wget directly; it starts the Wget process and checks its result. The safest general pattern is documented by Python’s subprocess module and GNU Wget’s manual.
1. Decide what “download a web page” means
There are three different jobs that are often described with the same words:
| Goal | Recommended approach | What you get |
|---|---|---|
| Fetch HTML for parsing | urllib.request or Requests |
One HTTP response body |
| Save one page for offline viewing | Wget page-requisite mode | HTML plus referenced CSS, images, and similar assets |
| Copy a site or follow links | Wget recursion with strict limits | Many pages and their resources |
Wget’s --page-requisites option is intended for a single page and its required resources. Recursive retrieval follows links found in HTML, XHTML, and CSS. It is broader, consumes more disk and bandwidth, and must be scoped with depth and domain rules.
2. Install and verify Wget
Wget must be installed on the machine where Python runs and its executable must be available through PATH. GNU describes Wget as a non-interactive web downloader that runs on Unix-like systems and Windows; the installation command and executable location depend on your operating system.
Verify the executable before writing application code:
wget --version
python --version
If Python cannot find Wget, either install it using your platform’s trusted package manager or pass a verified absolute executable path such as /usr/bin/wget or C:\\Tools\\wget.exe. Do not assume a developer laptop’s PATH is also present in a service, container, scheduled job, or serverless runtime.
3. Download one page and its assets
This complete example creates a destination directory, downloads one URL, rewrites links for local viewing, and reports the common failure modes:
from pathlib import Path
import subprocess

url = "https://example.com/"
destination = Path("offline-example")
destination.mkdir(parents=True, exist_ok=True)

command = [
    "wget",
    "--page-requisites",   # download CSS, images, and other page resources
    "--convert-links",     # rewrite links so the copy works locally
    "--adjust-extension",  # add suitable extensions to saved files
    "--directory-prefix", str(destination),
    "--",                  # end options; the next value is the URL
    url,
]

try:
    completed = subprocess.run(
        command,
        check=True,
        timeout=120,
    )
except FileNotFoundError as exc:
    raise RuntimeError("Wget is not installed or is missing from PATH") from exc
except subprocess.TimeoutExpired as exc:
    raise RuntimeError("Wget exceeded the 120-second timeout") from exc
except subprocess.CalledProcessError as exc:
    raise RuntimeError(f"Wget failed with exit code {exc.returncode}") from exc
else:
    print(f"Downloaded {url} into {destination}")
Python recommends an argument sequence for ordinary process execution. With a list, each item is passed as one argument, so URL characters are not interpreted by a shell. The -- separator prevents a URL beginning with a hyphen from being treated as another Wget option.
What each option does
--page-requisitesretrieves resources needed to display the page, such as stylesheets and images.--convert-linkschanges downloaded links to point at local files.--adjust-extensionadds an extension that matches the saved content where appropriate.--directory-prefixplaces output below the directory you choose.check=Trueraisessubprocess.CalledProcessErrorfor a nonzero exit status.timeout=120bounds how long Python waits for the child process.
Wget’s exact behavior can vary by version and platform. Confirm that your installed build supports every option you use.
4. Make the URL and output handling robust
Accept a URL from a function
from pathlib import Path
import subprocess


def download_page(url: str, output_dir: str = "downloaded-page") -> Path:
    target = Path(output_dir)
    target.mkdir(parents=True, exist_ok=True)

    subprocess.run(
        [
            "wget",
            "--page-requisites",
            "--convert-links",
            "--adjust-extension",
            "--directory-prefix", str(target),
            "--",
            url,
        ],
        check=True,
        timeout=120,
    )
    return target

if __name__ == "__main__":
    download_page("https://example.com/", "example-copy")
Validate or allow-list input URLs when they come from users. A list of arguments with the default shell=False avoids shell parsing, but it does not make arbitrary network access safe. Your application still needs its own policy for allowed hosts, schemes, redirects, and private network addresses.
Capture Wget’s output
completed = subprocess.run(
    ["wget", "--page-requisites", "--convert-links", "--", url],
    check=False,
    capture_output=True,
    text=True,
    timeout=120,
)

if completed.returncode != 0:
    print(completed.stderr)
else:
    print(completed.stdout)
Use capture_output=True when logs must be inspected programmatically. For a long-running job, stream output instead of retaining an unbounded amount of text.
5. One page versus recursive retrieval
Do not add recursion just because a page contains links. For one offline page, page-requisite mode is the narrower operation. Recursive mode can traverse links and quickly consume disk, memory, CPU, bandwidth, and remote-server capacity. GNU’s manual explicitly warns that recursive retrieval should be used with care.
If you truly need a bounded crawl, set a depth and scope it:
import subprocess

subprocess.run(
    [
        "wget",
        "--recursive",
        "--level=2",
        "--no-parent",
        "--domains", "example.com",
        "--page-requisites",
        "--convert-links",
        "--adjust-extension",
        "--directory-prefix", "site-copy",
        "--", "https://example.com/docs/",
    ],
    check=True,
    timeout=600,
)
--level=2 limits link depth, --no-parent prevents moving above the starting path, and --domains prevents traversal to other hosts. Review Wget’s current manual for additional include/exclude, rate, and robots rules. Wget’s recursive retrieval respects robots.txt; your legal and operational requirements may impose stricter rules.
6. When urllib or Requests is a better tool
If Python only needs the response body, launching an external process adds an installation dependency and process overhead. The standard library is enough for a small fetch:
from urllib.request import urlopen

with urlopen("https://example.com/", timeout=30) as response:
    html = response.read()

print(len(html))
For large responses, avoid loading everything into memory. Copy the response stream to a file in chunks:
from shutil import copyfileobj
from urllib.request import urlopen

with urlopen("https://example.com/large-file", timeout=60) as response:
    with open("large-file", "wb") as output:
        copyfileobj(response, output, length=1024 * 1024)
Requests is a separate HTTP library with documentation covering streaming downloads; its 2.34.2 documentation states support for Python 3.10 and newer.
import requests

with requests.get("https://example.com/", timeout=30, stream=True) as response:
    response.raise_for_status()
    with open("page.html", "wb") as output:
        for chunk in response.iter_content(chunk_size=1024 * 1024):
            if chunk:
                output.write(chunk)
Choose Wget when you need its command-line retrieval behavior, retries, page-resource handling, link conversion, or mirroring features. Choose urllib or Requests when your program needs direct control over headers, status codes, streaming, parsing, and application-level retries.
7. Common errors and fixes
| Error or symptom | Likely cause | Fix |
|---|---|---|
FileNotFoundError: wget |
Wget is not installed or not on PATH | Install it or use a verified absolute executable path. |
Nonzero exit and CalledProcessError |
DNS, TLS, HTTP, permissions, or Wget option failure | Inspect stderr, verify the URL manually, and check the installed Wget version. |
TimeoutExpired |
Slow server, large assets, or a stalled connection | Set a realistic timeout, reduce scope, and investigate the server or network. |
| HTML saved but styling is missing | Assets were not requested or are blocked/constructed by JavaScript | Use page-requisite mode; remember Wget is not a browser and does not execute page JavaScript like one. |
| Links still point to the internet | Link conversion was omitted or a resource could not be downloaded | Use --convert-links and inspect Wget’s log. |
| Huge unexpected download | Recursive retrieval followed more links than intended | Remove recursion for one page; otherwise add depth, domain, path, and rate limits. |
| Works locally but fails in production | Different PATH, certificates, permissions, or network policy | Log the executable path and version, provision Wget explicitly, and test from the deployment environment. |
8. Performance, reliability, and cost considerations
- Process cost: every Wget call starts an external process. Reuse an HTTP client for many small requests when Wget’s features are unnecessary.
- Network cost: page requisites and recursion multiply transferred bytes. Set boundaries before running jobs in production.
- Disk cost: use a dedicated output directory and monitor free space, especially for crawls.
- Timeouts: set both a Python process timeout and, where appropriate, Wget’s own connection/read timeout options.
- Retries: distinguish transient network failures from permanent HTTP or configuration errors. Retrying a non-existent URL only increases load.
- Reproducibility: record the Wget version, URL, arguments, timestamp, and exit status with each artifact.
- Security: do not use
shell=Truewith URLs assembled from input. Restrict destinations and outbound hosts when untrusted users can submit URLs.
9. Or skip the browser setup
If your real goal is a clean screenshot or PDF rather than an offline HTML directory, ScreenshotNeo provides a single HTTP request. Its API accepts a URL and returns PNG, JPEG, WebP, or PDF. See the ScreenshotNeo API documentation for all options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
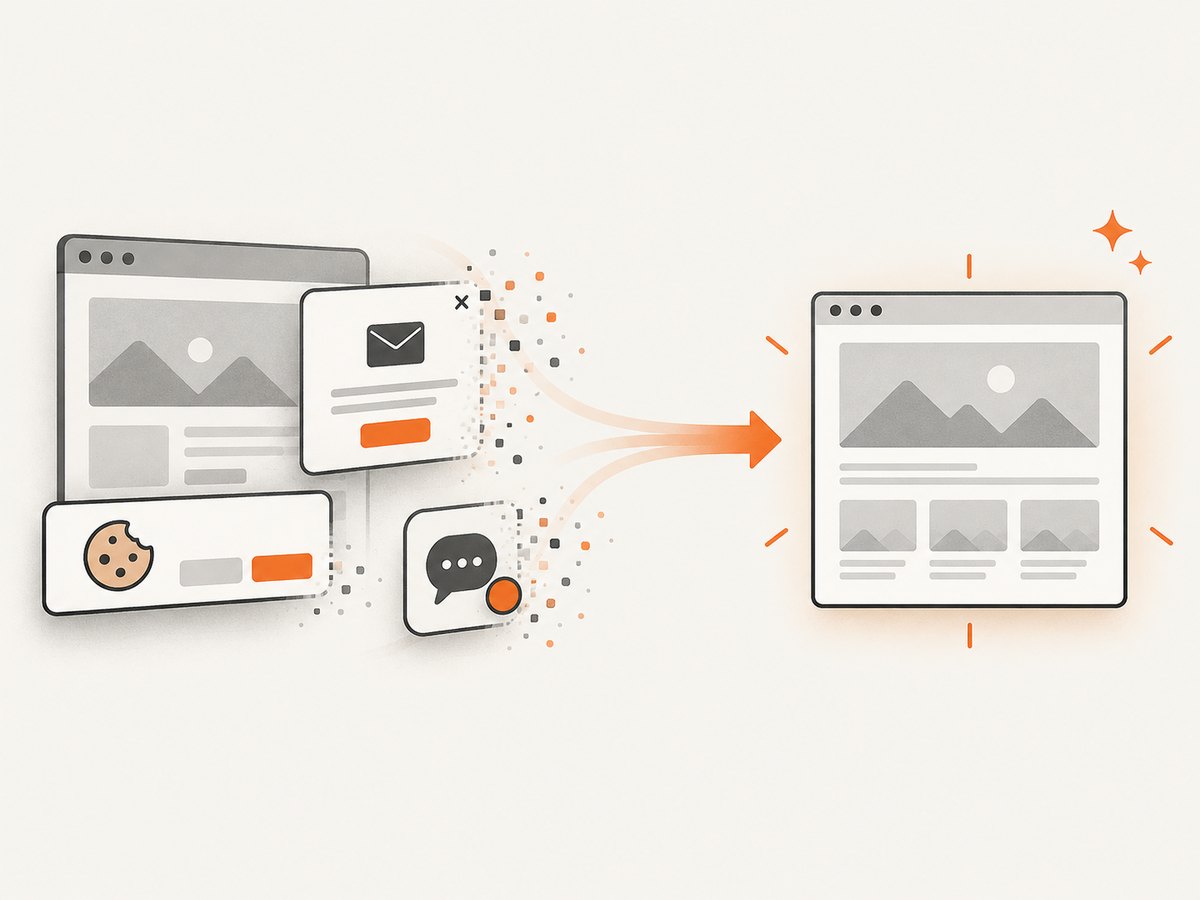
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed; response headers identify the page verdict and billing status. It also offers an MCP server for AI agents, including Claude and Cursor, with take_screenshot, get_page_info, and capture_pdf tools. One thousand screenshots per month are free with no card, and paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
10. Practical checklist
- Confirm Wget is installed in the same environment as Python.
- Use a list of arguments and leave
shell=False. - Put
--before a user-provided URL. - Use page-requisite mode for one offline page.
- Add recursion only with explicit depth and domain limits.
- Set a timeout and handle
FileNotFoundError,TimeoutExpired, andCalledProcessError. - Capture logs when diagnosing missing assets or HTTP failures.
- Use urllib or Requests when you need response data rather than Wget’s file retrieval behavior.
FAQ
Does Wget execute JavaScript?
Wget retrieves HTTP resources; it is not a full browser runtime. Pages that build their content or assets in JavaScript may not produce a complete rendered copy.
Should I use shell=True?
No for this use case. Passing an argument list to subprocess.run() avoids shell parsing and reduces injection risk.
Can page-requisite mode copy every asset?
It requests resources Wget can discover from the page. Cross-origin restrictions, dynamically generated URLs, authentication, and JavaScript-generated requests can leave gaps.
Is recursive Wget a website backup?
It can retrieve many linked resources, but it is not automatically a complete backup. Scope it carefully and verify the resulting files, redirects, forms, and dynamic behavior.
When should I use ScreenshotNeo?
Use it when the deliverable is a rendered screenshot or PDF and you want browser capture, cleanup of common overlays, billing signals, and an API or MCP workflow instead of managing a local browser stack.


