What Is a 403 Status Code and How Can You Avoid It?
A 403 Forbidden response means the server understood your request but refuses access. Learn what causes it, how it differs from 401, and what developers can do.
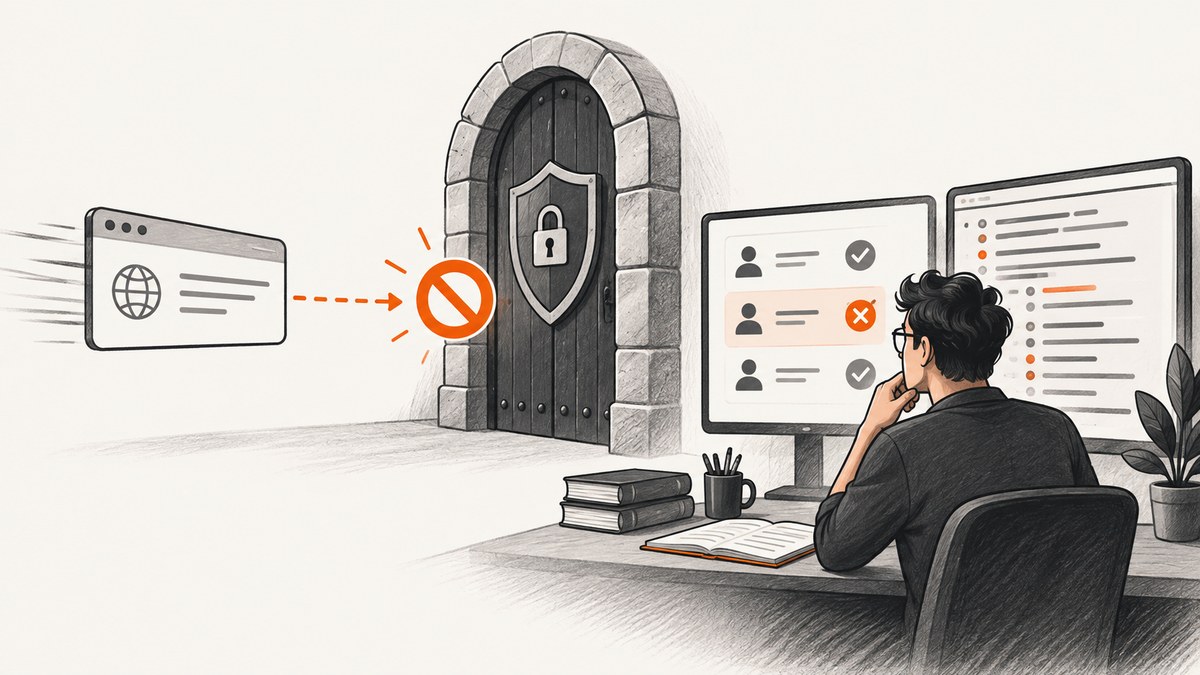
HTTP 403 Forbidden means the server understood your request but refuses to fulfill it. The refusal usually means the authenticated identity does not have permission for the resource or action, although a 403 can also come from an access policy unrelated to credentials. RFC 9110 defines the status as a refusal after the request was understood; the server may include an explanation in the response body.
A 403 is an access decision, not a parsing failure. Sending the identical request again, clearing a browser cache, or signing in with the same account normally will not change that decision. The useful fix is to identify the policy that denied access and then use an account, token, role, scope, URL, or support process that the site owner accepts.
What a 403 response means
The complete definition is in RFC 9110, section 15.5.4: “The 403 (Forbidden) status code indicates that the server understood the request but refuses to fulfill it.” Credentials supplied with the request are considered insufficient to grant access, but the refusal can be unrelated to credentials.

Application code decides what “forbidden” means. Examples include:
- A signed-in user tries to open an organization resource outside their role.
- An API token is valid but lacks the scope required for an operation.
- An endpoint permits administrators to delete records but rejects ordinary users.
- An origin, firewall, WAF, bot policy, or geographic rule blocks the request.
- A server denies directory listing or a file-system path even though the host is reachable.
Read the response body and headers before guessing. A service may return a request ID, policy name, or link to an access request. The standard allows an explanation but does not require one.
403 vs. 401, 404, and 407
| Status | What it says | Typical next action |
|---|---|---|
401 Unauthorized |
Authentication is missing or not accepted. Despite the name, this is the status used for an authentication challenge. | Send valid credentials and follow the WWW-Authenticate challenge. See MDN’s 401 reference. |
403 Forbidden |
The request was understood, but access to the resource or action is refused. | Check role, scope, ownership, policy, and the exact URL. Ask the site administrator when access should be granted. |
404 Not Found |
The origin has no current representation, or chooses not to disclose that a restricted resource exists. | Verify the URL. Do not assume a 404 proves the resource never existed. |
407 Proxy Authentication Required |
A proxy, rather than the origin server, requires authentication. | Authenticate to the proxy using its proxy-specific mechanism. |
MDN’s 403 guidance also emphasizes that an unchanged request should be expected to fail again. A 403 is not proof that you forgot to log in, and a 401 is not the same as “you are forbidden.”
How to investigate a 403 as a visitor
- Confirm the address. Check the hostname, path, spelling, URL encoding, and HTTP method. A link to an administrative or private path may be intentional.
- Identify the account. If the page requires an account, sign in to the organization, tenant, or workspace that owns the resource. Re-entering the same credentials is unlikely to help if the server already knows that identity.
- Inspect the response. Use browser developer tools or
curl -ito view the status, headers, and body. Preserve any request ID for support. - Check the required permission. For APIs, compare the token’s scopes and the operation’s documented role. A token can authenticate successfully and still be rejected for an administrator-only action.
- Follow the site’s access process. Request an invitation, role change, allow-list entry, or resource owner approval. Only the site operator can change its authorization policy.
curl -i https://example.com/private/reportDo not try to bypass an access control with credential guessing, header spoofing, or repeated automated requests. Those actions cannot grant permission and may violate the site’s rules.
How developers can prevent unexpected 403 responses
For API clients
- Send the credential type the API documents, such as a bearer token or signed request.
- Verify the token is for the intended environment, tenant, and user.
- Request the minimum scope that includes the operation; confirm the scope spelling and case.
- Check ownership and object-level authorization. A user may read one project but not another.
- Use the documented HTTP method and content type. Some applications return 403 for a policy failure that is actually triggered by an unsupported action.
- Log status, request ID, method, URL (without secrets), identity, scopes, and a redacted response body.
curl -i \\
  -H "Authorization: Bearer $TOKEN" \\
  -H "Accept: application/json" \\
  https://api.example.com/v1/projects/123
For servers you operate
- Evaluate authentication and authorization separately. Missing or invalid credentials generally lead to 401; valid credentials without the needed privilege lead to 403.
- Apply the authorization rule to the exact resource and action, including tenant and ownership checks.
- Return a safe, actionable explanation and a correlation ID. Do not disclose secrets or information about resources the caller is not allowed to know exist.
- Keep policy decisions observable in server logs: subject, resource, action, decision, policy version, and reason.
- Use 404 deliberately when your security model requires hiding the existence of a restricted resource; document that behavior for client developers.
- Make caches vary on every input that changes authorization, such as cookies, authorization headers, or tenant identifiers. A public cache must never serve a private denial or response to the wrong user.
Common 403 causes and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| API returns 403 after a successful login | Role or scope is insufficient. | Inspect the token claims and endpoint requirements; ask an administrator for the least privilege that permits the operation. |
| Only one object returns 403 | Object ownership, project membership, or tenant mismatch. | Confirm the object belongs to the current account and use the correct tenant or project ID. |
| Browser works, script gets 403 | Missing session cookie, CSRF token, required header, or a bot policy. | Use the documented API; if authorized, reproduce the required session flow and include only the headers the service requires. |
| Every request from a server is denied | IP, region, ASN, WAF, or network allow-list policy. | Ask the operator to review logs and allow-list the legitimate source. A VPN or network change is not a guaranteed fix. |
| Static files return 403 | File or directory permissions, missing index policy, or server configuration. | Check the origin’s process permissions and route configuration; avoid making private directories public. |
| Screenshot or crawler receives 403 | The target site blocks automated traffic or requires a session. | Obtain permission, supply documented authentication, or use the site’s export/API. Do not attempt to defeat a bot check. |
Capturing a page without turning a 403 into a mystery
When you build a screenshot or monitoring workflow, record the HTTP result separately from the image bytes. A successful TCP connection does not mean the target page is authorized. Keep the target URL, final URL after redirects, response status, timing, and any provider verdict in your job record. Treat a 403 as a meaningful result that needs policy review, not as an instruction to retry forever.
Use bounded retries only for transient transport failures. A repeated 403 with the same identity and URL is normally deterministic; retrying increases load without changing authorization. If a policy can change, retry after an explicit role, allow-list, or session update and attach a new correlation ID.
Or skip the browser setup
ScreenshotNeo provides a website screenshot API when you need a clean capture rather than a browser project to maintain. It accepts one GET request and returns PNG, JPEG, WebP, or PDF. The request below captures a page; see the ScreenshotNeo API documentation for all parameters.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://example.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));ScreenshotNeo accepts custom headers, cookies, user agents, and Authorization when the site permits an authenticated capture. It can wait for a selector, delay, or network idle; click an element; hide selectors; block ads, trackers, requests, or resource types; set timezone and geolocation; and capture a full page, one CSS-selected element, a device preset, or any viewport. Other options include dark mode, retina scale, custom CSS and JavaScript, transparent backgrounds, image resizing, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, usage reporting, and PDF paper size, margins, landscape, and page ranges.
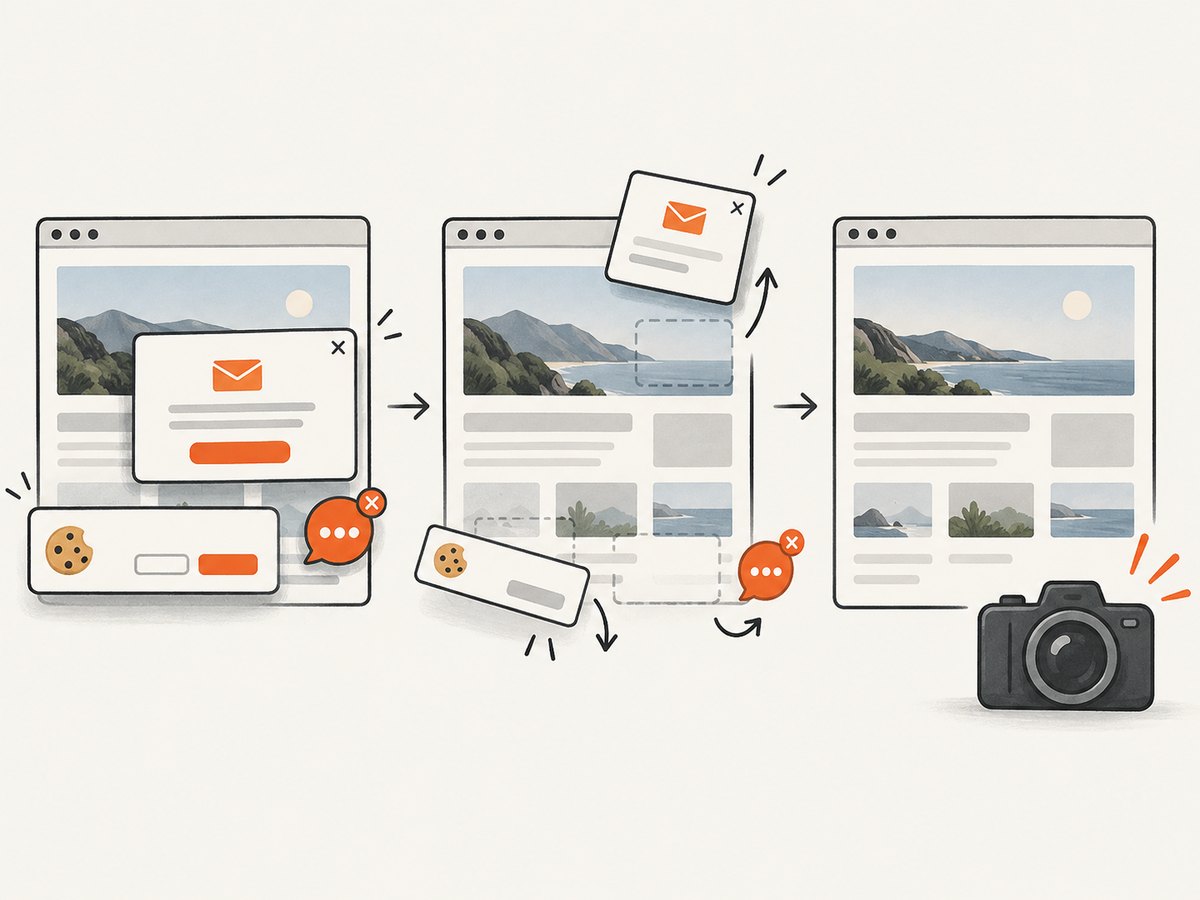
Before capture, it accepts cookie or consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets. Each cleanup step can be disabled. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing; response headers identify the page verdict and whether the shot was billed (X-Page-Verdict and X-Billed). An MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients.
The Free plan includes 1,000 shots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing provides two months free, and every feature is available on every plan. If a target returns 403, ScreenshotNeo cannot grant access: provide credentials and permissions you are authorized to use, or resolve the policy with the site owner.
Create a free ScreenshotNeo account to get 1,000 screenshots a month with no card.
Performance, reliability, and cost considerations
- Measure the decision. Record status and verdict before processing image bytes so a denied page is not mistaken for a valid capture.
- Limit work per URL. Set a timeout, cap redirects, and avoid retrying deterministic 403 responses. Use network-idle waits only when the page truly needs them.
- Use caching intentionally. A TTL reduces repeated captures, but authorization-sensitive pages need cache keys that include the identity or should avoid shared caching.
- Separate public and private jobs. Keep access keys, cookies, and Authorization headers out of URLs, logs, screenshots, and client-side code. Signed links are useful for public
<img>tags without exposing the API key. - Control concurrency. Bulk capture can reduce request overhead, while bounded workers protect your own queue and the target site’s rate limits.
- Budget from billed results. With ScreenshotNeo, only clean shots are billed; cache hits and failed, blank, timed-out, or bot-blocked captures are not billed, and the response says which case occurred.
Troubleshooting checklist
- Save the complete status line, response headers, body, request ID, final URL, and timestamp.
- Confirm the method, path, host, and tenant are correct after redirects.
- Compare the caller’s role and token scopes with the required permission.
- Check resource ownership and whether the policy intentionally hides restricted resources as 404.
- Ask the site administrator to inspect authorization, WAF, IP, and region logs.
- Change one authorized input at a time, then record the new result. Do not run an unbounded retry loop.
FAQ
Does 403 mean I am not logged in?
No. A 403 often means the server recognized the identity but it lacks permission. Missing or unacceptable authentication is generally represented by 401.
Will refreshing or clearing cookies fix a 403?
Only if the site documents a stale-session problem. An unchanged request should normally fail again; check the account, role, token scope, and policy first.
Can I fix a 403 by changing my IP or using a VPN?
There is no universal fix. If an operator intentionally blocks a network or region, only its access policy or an approved allow-list change resolves the problem.
Why did the same URL return 404 instead?
An origin may return 404 to avoid revealing that a restricted resource exists. Treat the status as part of that site’s security design.
Should my client retry 403 responses?
Not automatically with the same credentials and request. Retry only after an authorized change, such as a new scope or approved access rule, and use a bounded policy.