Can You Use XPath Selectors in BeautifulSoup?
Beautiful Soup has no native XPath method. Use CSS selectors with select(), or parse with lxml when you need XPath expressions.
Direct answer: Beautiful Soup does not natively evaluate XPath selectors. Its documented selector interface is the find()/find_all() family and CSS selectors through select() and select_one(). If your scraper needs XPath predicates, axes, functions, or namespace-aware queries, parse the document with lxml and call element.xpath().
Using BeautifulSoup(html, 'lxml') often causes confusion. The lxml argument chooses Beautiful Soup’s parser backend; the returned object is still a BeautifulSoup object. It does not add a documented soup.xpath() method. XPath belongs to lxml’s own Element and ElementTree APIs.
What Beautiful Soup supports
Beautiful Soup is designed around a Python-friendly tree API. You can locate tags by name, attributes, text, and relationships, or use CSS selectors powered by Soup Sieve.
from bs4 import BeautifulSoup

html = '''
<article>
  <h2><a href="/one">First post</a></h2>
  <h2><a href="/two">Second post</a></h2>
</article>
'''

soup = BeautifulSoup(html, 'html.parser')

# Find every matching link.
links = soup.select('article h2 a')
for link in links:
    print(link.get_text(strip=True), link.get('href'))

# Find only the first match, or None if there is no match.
first_link = soup.select_one('article h2 a')
if first_link:
    print(first_link.get_text(strip=True))

# The traditional Beautiful Soup API remains available.
headings = soup.find_all('h2')
CSS selectors cover most everyday extraction tasks: classes (.product), IDs (#main), attributes ([data-id]), descendants, child combinators, sibling combinators, and grouping. For example:
cards = soup.select('main .card[data-state="published"]')
external = soup.select('a[href^="https://"]')
second = soup.select('ul.items > li:nth-of-type(2)')
The Beautiful Soup documentation explicitly says that if CSS selectors are all you need, you should skip Beautiful Soup and parse with lxml directly because lxml is faster for that use case. See the official Beautiful Soup documentation for the supported APIs and selector syntax.
Why parser='lxml' does not enable XPath
This code uses lxml to build the parse tree, but Beautiful Soup wraps that tree in its own object model:
from bs4 import BeautifulSoup

soup = BeautifulSoup(html, 'lxml')
print(type(soup))
# <class 'bs4.BeautifulSoup'>

# This is not a documented Beautiful Soup API:
# soup.xpath('//article//a')
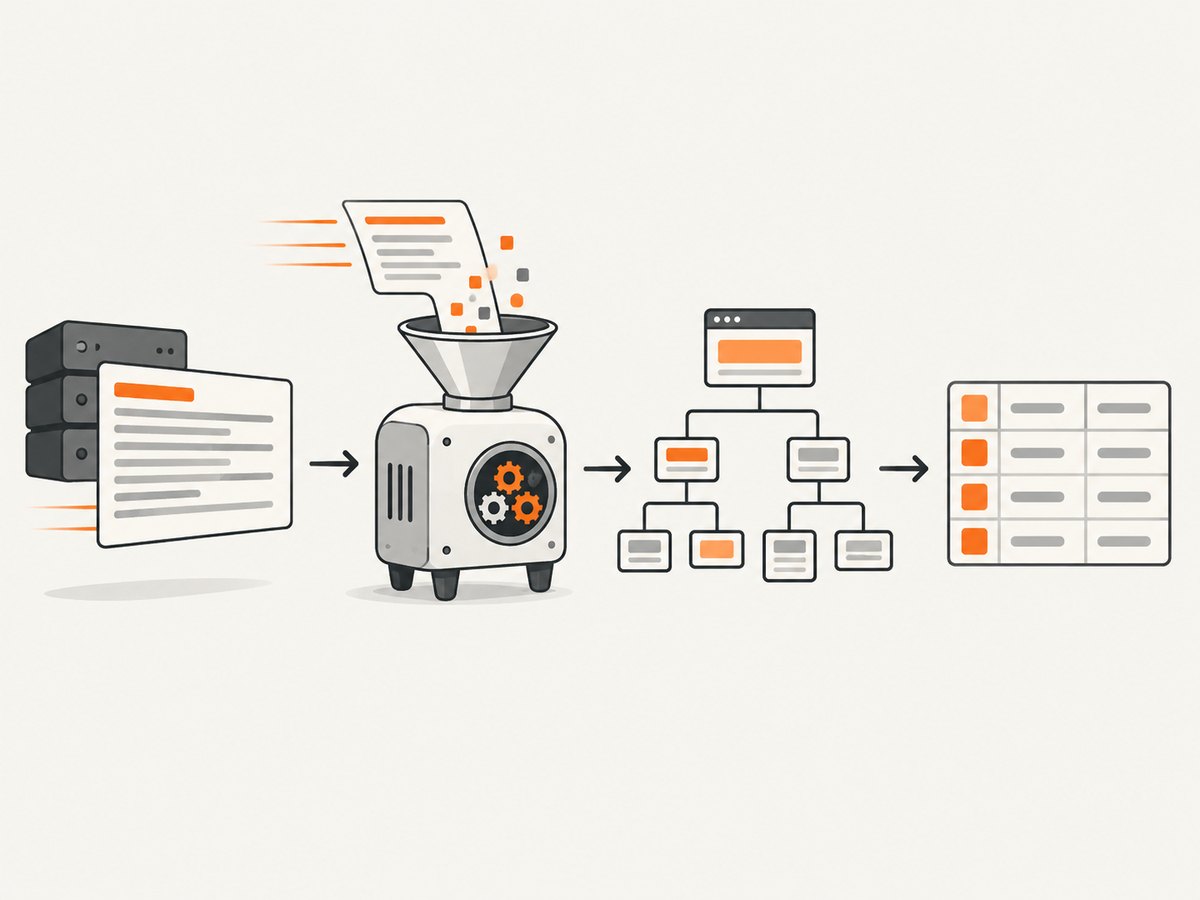
Changing the parser can improve parsing behavior or speed, but it does not change the methods exposed by soup. If you need XPath, keep the input string and hand it to lxml directly.
Use lxml for XPath
Install lxml with pip, parse HTML with lxml.html, then call xpath() on the returned element.
python -m pip install lxml
from lxml import html

html_text = '''
<html>
  <body>
    <div class="item">
      <a href="/one">First</a>
      <a href="/two">Second</a>
    </div>
  </body>
</html>
'''

root = html.fromstring(html_text)

# Return matching element objects.
items = root.xpath('//div[@class="item"]//a')
for item in items:
    print(item.text_content().strip(), item.get('href'))

# Return text nodes directly.
texts = root.xpath('//div[@class="item"]//a/text()')
print(texts)

# Predicates are useful when a simple CSS selector is not enough.
second_link = root.xpath('(//div[@class="item"]//a)[2]')
if second_link:
    print(second_link[0].get('href'))
lxml’s Element and ElementTree classes expose complete XPath expressions. The lxml XPath documentation covers expressions, compiled XPath, namespaces, and return types. Its HTML parsing documentation describes the HTML helpers used above.
Beautiful Soup and lxml side by side
| Need | Recommended API | Example |
|---|---|---|
| Readable Python extraction | Beautiful Soup | soup.find_all('a') |
| CSS selectors | select() or lxml CSS support |
soup.select('article h2 a') |
| XPath predicates and axes | lxml | root.xpath('//a[contains(@href, "docs")]') |
| Namespaces | lxml with a namespace map | root.xpath('//svg:rect', namespaces=ns) |
| Very large, repeated queries | Usually lxml | Compile and reuse an XPath expression |
Common XPath patterns in lxml
Attributes and text
from lxml import html
root = html.fromstring(page_html)

hrefs = root.xpath('//a[@rel="next"]/@href')
labels = root.xpath('//button[normalize-space()="Continue"]/text()')
images = root.xpath('//img[@alt]/@src')
Class matching
An exact @class comparison fails when an element has multiple classes. Use the token-safe XPath expression:
cards = root.xpath(
    '//div[contains(concat(" ", normalize-space(@class), " "), " card ")]'
)
Relative queries
for row in root.xpath('//table[@id="orders"]/tbody/tr'):
    order_id = row.xpath('./td[1]/text()')
    status = row.xpath('./td[3]/text()')
    print(order_id, status)
Namespaces
from lxml import etree

root = etree.fromstring(xml_bytes)
ns = {'svg': 'http://www.w3.org/2000/svg'}
rectangles = root.xpath('//svg:rect', namespaces=ns)
Converting a Beautiful Soup workflow
When an existing scraper uses Beautiful Soup but one query needs XPath, there are two practical approaches.
- Convert the selector to CSS. Replace simple XPath such as
//article//awitharticle a, then keep the rest of the scraper in Beautiful Soup. - Parse with lxml from the beginning. This is cleaner when most queries use XPath or when you need lxml element methods.
# Before: Beautiful Soup
article_links = soup.select('article a')

# After: lxml
article_links = root.xpath('//article//a')
Do not mix node types accidentally. A Beautiful Soup Tag and an lxml HtmlElement have different methods for attributes, text, and parent traversal. Choose one tree representation for each pipeline stage and convert deliberately if a third-party function requires a particular type.
Fetching the page before parsing
Both libraries parse the HTML you provide; neither executes JavaScript or waits for client-side rendering. A basic request flow is:
import requests
from lxml import html

response = requests.get('https://example.com', timeout=30)
response.raise_for_status()
root = html.fromstring(response.content)
links = root.xpath('//main//a/@href')
print(links)
If the content appears only after JavaScript runs, fetch a rendered page with a browser automation tool or a screenshot/rendering service first. Check the response status, encoding, redirects, and whether the desired nodes exist in the returned HTML before changing selectors.
Or skip the browser setup
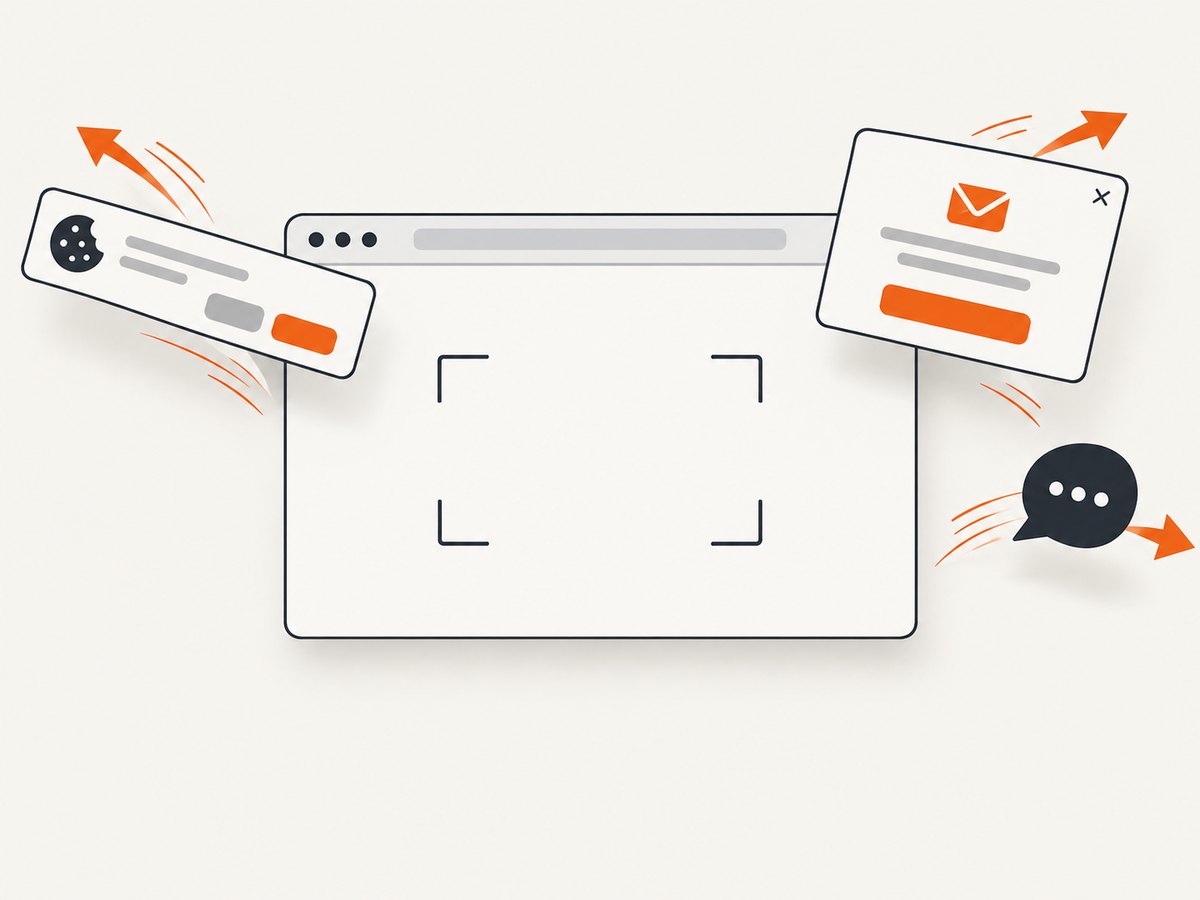
For a rendered page image or PDF, ScreenshotNeo provides a single GET request. It accepts cookie and consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and whether the request was billed. Its MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all options, including full-page capture, CSS element capture, device presets, custom headers and cookies, waits, request blocking, caching, signed links, asynchronous jobs, bulk capture, and PDF settings.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webp
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
There are 1,000 screenshots per month on the free plan with no card. Paid plans start at $5 for 3,000 shots; every feature is available on every plan. Create a free ScreenshotNeo account and try the API.
Troubleshooting
AttributeError: 'BeautifulSoup' object has no attribute 'xpath'
Cause: You called an lxml method on a Beautiful Soup object. Fix: rewrite the query with select(), or parse the original HTML using lxml.html.fromstring().
ImportError: No module named lxml
Cause: lxml is not installed in the active Python environment. Fix: run python -m pip install lxml with the same interpreter that runs your script, then verify with python -c "import lxml".
XPath returns an empty list
Cause: the path does not match the actual tree, the page is JavaScript-rendered, namespaces are missing, or the HTML was malformed. Fix: print the response body, inspect root.xpath('//body'), simplify the expression one step at a time, and provide a namespace map for XML. Confirm that the node exists in the downloaded HTML rather than only in browser developer tools.
Text contains unexpected whitespace
Cause: HTML text is split across descendants. Fix: use lxml’s text_content() and normalize whitespace, or use XPath’s normalize-space() when selecting a text value.
CSS and XPath return different matches
Cause: CSS and XPath have different indexing and class semantics. XPath indexes are commonly one-based, while CSS pseudo-classes such as :nth-of-type() follow CSS rules. Also check whether your XPath matches descendants with // while your CSS selector uses a direct-child combinator >.
Performance and reliability notes
- For CSS-only work, Beautiful Soup is convenient, while the Beautiful Soup documentation recommends direct lxml parsing when speed matters.
- Parse once and reuse the tree for multiple queries. Repeatedly reparsing the same response costs more than changing selector syntax.
- Use compiled XPath expressions when the same complex query runs many times:
from lxml import etree, html

root = html.fromstring(page_html)
find_products = etree.XPath('//article[@data-type="product"]//a/@href')
for href in find_products(root):
    print(href)
- Set network timeouts, call
raise_for_status(), and record the final URL after redirects. - Keep selectors resilient: prefer stable IDs, data attributes, and semantic structure over generated class names.
- Cache downloaded HTML when repeatedly developing selectors, but refresh it before production runs so you notice markup changes.
Decision checklist
- Need a simple Python API and tolerant HTML parsing? Use Beautiful Soup.
- Need CSS selectors only? Use
select(); direct lxml parsing may be faster. - Need XPath predicates, axes, functions, namespaces, or compiled expressions? Use lxml.
- Need JavaScript-rendered screenshots or PDFs rather than parsed DOM data? Use a browser renderer such as ScreenshotNeo.
- Need both styles temporarily? Keep separate parsing variables and convert explicitly.
FAQ
Can I install Soup Sieve to add XPath?
No. Soup Sieve powers Beautiful Soup’s CSS selector support; it does not turn CSS selectors into XPath evaluation. Use lxml for XPath.
Does Beautiful Soup support XPath strings through find()?
No. find() and find_all() accept Beautiful Soup’s name, attribute, string, and filter arguments, not XPath expressions.
Should I always replace Beautiful Soup with lxml?
No. Keep Beautiful Soup when its API and tolerant parsing fit the job. Switch when XPath or lxml’s tree operations are central, or when direct lxml performance is important.
Can lxml parse broken HTML?
Yes, lxml.html is intended for HTML and is generally forgiving, but you should still inspect the parsed tree and validate assumptions against representative pages.
Can ScreenshotNeo return the DOM for XPath queries?
ScreenshotNeo is a screenshot and PDF API with page information tooling. It is useful when the output you need is a rendered capture; use Beautiful Soup or lxml when you need to extract and transform DOM nodes.


