How to Debug Headless Chrome PDF Printing Problems
Fix blank, incomplete, or misstyled headless Chrome PDFs by isolating startup, readiness, print CSS, fonts, colors, and timing issues.
Headless Chrome PDF failures usually come from one of two places: Chrome never started successfully, or the page was captured before it was ready. Blank pages, missing sections, incorrect colors, and layout changes then come from print CSS, fonts, resource loading, or timing.
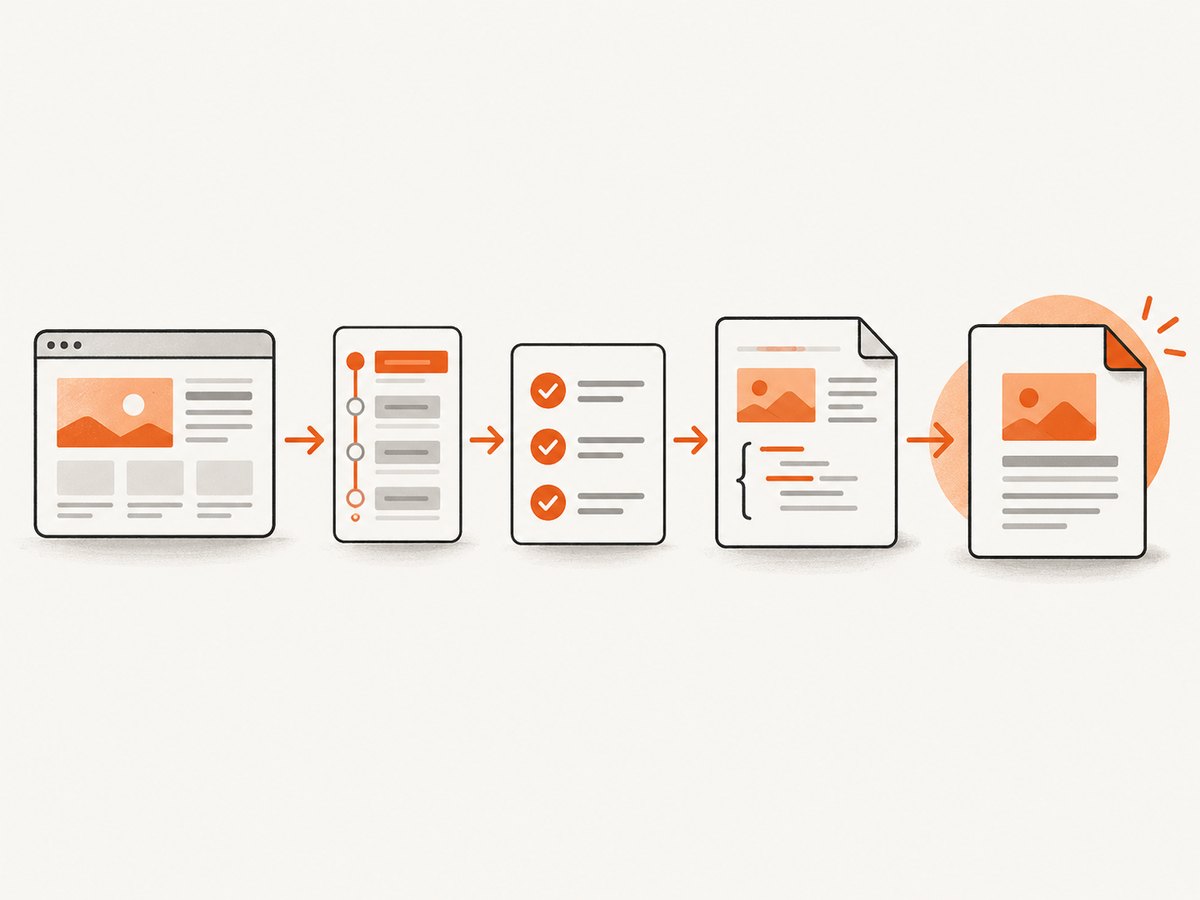
Use this order when debugging:
- Record the exact Chrome, Chromium, Puppeteer, operating system, launch mode, and command.
- Prove that Chrome starts and can write any PDF.
- Check navigation, console errors, page errors, and failed requests.
- Wait for the page’s real ready condition, not only a fixed delay.
- Inspect print media CSS, fonts, colors, margins, and page breaks.
- Reduce the problem to a small reproducible page.
Chrome’s command-line mode uses --headless --print-to-pdf. Puppeteer uses Page.pdf(), which generates output with the print CSS media type by default. A successful navigation does not prove that application data, charts, images, or web fonts have finished rendering.
1. Identify the PDF generation path
Start by writing down the complete environment. A change in the browser build or Puppeteer version can alter flags, sandbox behavior, font availability, or print layout.
| Item | Record | Why it matters |
|---|---|---|
| Browser | Chrome or Chromium version and executable path | Flags and rendering behavior are version-sensitive |
| Automation | Puppeteer version or CLI command | Waiting and PDF defaults differ by tool |
| Host | OS, container image, architecture | Fonts, libraries, and sandbox support vary |
| Launch mode | Headless mode, arguments, environment variables | Startup failures can occur before page rendering |
| Input | URL, authentication, cookies, and request headers | The browser may receive a different page than your desktop |
The Chrome documentation covers --print-to-pdf, --timeout, --virtual-time-budget, and header/footer flags in its headless mode documentation. Current builds document --no-pdf-header-footer; older builds may use --print-to-pdf-no-header.
2. Prove Chrome can start and write a file
Do not investigate CSS while the browser process is failing. First run a minimal command against a simple page:
google-chrome \
  --headless \
  --disable-gpu \
  --no-pdf-header-footer \
  --print-to-pdf=/tmp/minimal.pdf \
  https://example.com
Use the executable available on your system, such as chromium or chromium-browser. Check the exit code and file metadata:
echo $?
file /tmp/minimal.pdf
pdfinfo /tmp/minimal.pdf | head
If this fails, capture stderr. A common Linux error is No usable sandbox!. Puppeteer’s troubleshooting guide explains that the host may not provide a usable sandbox. Running with --no-sandbox can be a security-sensitive workaround only when the content is absolutely trusted; it should not be a default launch argument for arbitrary URLs. See the Puppeteer troubleshooting guide.
3. Use Puppeteer with explicit diagnostics
The following script records navigation status, browser errors, failed requests, console output, and the generated file. It waits for network idle, then waits for an application-specific selector before printing.
import puppeteer from 'puppeteer';

const browser = await puppeteer.launch({
  headless: true,
  // Add no-sandbox only in a trusted, isolated environment when required.
  args: []
});

try {
  const page = await browser.newPage();

  page.on('console', message => {
    console.log(`[console:${message.type()}] ${message.text()}`);
  });
  page.on('pageerror', error => {
    console.error('[pageerror]', error);
  });
  page.on('requestfailed', request => {
    console.error('[requestfailed]', request.url(), request.failure());
  });

  const response = await page.goto('https://example.com/report', {
    waitUntil: 'domcontentloaded',
    timeout: 60000
  });
  console.log('navigation status:', response?.status());

  await page.waitForNetworkIdle({ idleTime: 500, timeout: 30000 });
  await page.waitForSelector('[data-report-ready="true"]', {
    visible: true,
    timeout: 30000
  });

  await page.pdf({
    path: 'report.pdf',
    format: 'A4',
    printBackground: true,
    preferCSSPageSize: true,
    displayHeaderFooter: false,
    margin: { top: '16mm', right: '16mm', bottom: '16mm', left: '16mm' }
  });
} finally {
  await browser.close();
}
Replace the selector with the signal your application actually sets. It could be a populated table, a chart container, or a promise exposed by the page. A fixed sleep can hide race conditions and still fail when a backend response is slower.
4. Separate real-time waiting from virtual time
Chrome’s --timeout waits up to a maximum real-time duration before capturing. It does not guarantee that application JavaScript has completed. A page can remain visually incomplete after the timeout.
--virtual-time-budget advances timer-driven JavaScript in virtual time. It can help diagnose pages that use setTimeout or animation timers, but it is not an application-ready check. Confirm the resulting DOM and PDF rather than assuming that a budget means the page is complete.
google-chrome \
  --headless \
  --timeout=30000 \
  --virtual-time-budget=10000 \
  --no-pdf-header-footer \
  --print-to-pdf=/tmp/timed.pdf \
  https://example.com
5. Check print media CSS
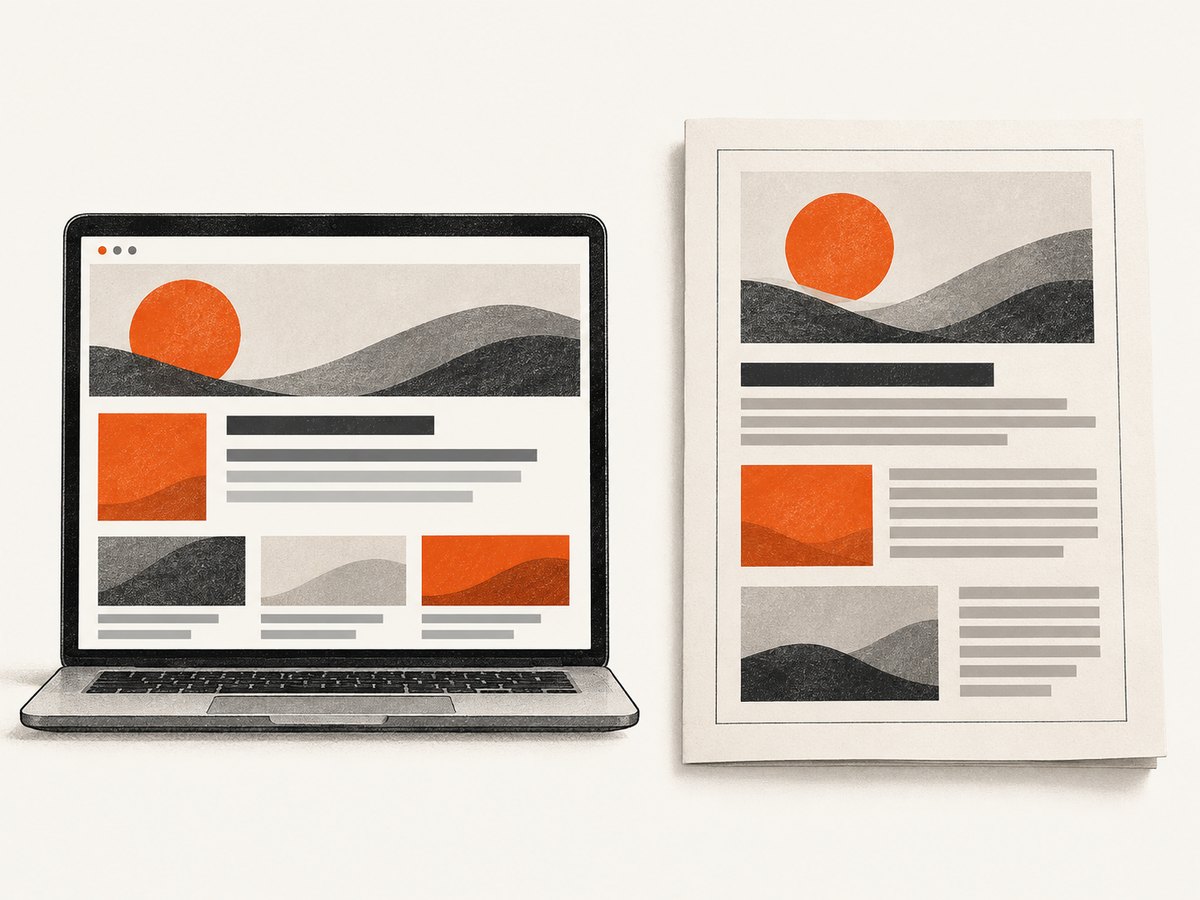
Puppeteer prints with the print media type. Rules inside @media print can hide navigation, change widths, reposition elements, or remove backgrounds. A page that looks correct in a normal browser tab may therefore produce a different PDF.
@media print {
  .site-nav,
  .cookie-banner,
  .interactive-controls {
    display: none !important;
  }

  .report {
    width: 100%;
  }

  @page {
    size: A4;
    margin: 16mm;
  }
}
To compare screen and print behavior in Puppeteer, render once with the documented default and once with screen media:
await page.emulateMediaType('screen');
await page.pdf({
  path: 'screen-media.pdf',
  printBackground: true
});
If the screen-media PDF is correct but the default PDF is not, inspect every print rule before changing browser flags. Keep the print stylesheet intentional: define page size, margins, visibility, widths, and page-break behavior explicitly.
6. Diagnose colors and backgrounds
Print output can modify colors by default. Puppeteer documents -webkit-print-color-adjust for requesting exact colors:
@media print {
  html {
    -webkit-print-color-adjust: exact;
    print-color-adjust: exact;
  }
}
Also set printBackground: true in page.pdf(). Check both sides: CSS may suppress a background, while the PDF call may omit backgrounds even when the CSS is correct.
7. Check fonts, images, and external resources
Puppeteer’s PDF guide says PDF generation waits for fonts by default, but a font can still be unavailable because its request failed, it requires authentication, its hostname is blocked, or the container lacks a fallback font.
- Watch
requestfailedevents for font and image URLs. - Open the font URL from the same container and network namespace.
- Check CORS, CSP, signed URL expiry, and authentication headers.
- Inspect the computed font family and compare it with the intended font.
- Install required system fonts in the image when a local fallback is expected.
Lazy-loaded images need special handling. Scroll through the document, wait for image completion, or wait for the application’s loaded marker before printing:
await page.evaluate(async () => {
  const images = [...document.images];
  for (const image of images) {
    image.scrollIntoView({ block: 'center' });
    if (!image.complete) {
      await new Promise(resolve => {
        image.addEventListener('load', resolve, { once: true });
        image.addEventListener('error', resolve, { once: true });
      });
    }
  }
});
8. Explain common symptoms
| Symptom | Likely cause | Fix |
|---|---|---|
| Blank PDF | Navigation failed, page is still loading, content is client-rendered, or a bot check is shown | Log status and errors; wait for a real ready selector; inspect the captured DOM |
| Only the header appears | Body is hidden by print CSS or data has not arrived | Compare screen and print media; wait for the data marker |
| Missing images | Lazy loading, failed requests, expired URLs, or blocked resources | Log request failures and force image loading before PDF generation |
| Wrong colors | Print color adjustment or omitted backgrounds | Use printBackground: true and print-color-adjust CSS |
| Different layout | Print media rules, viewport width, paper size, or margins | Set viewport and @page; inspect @media print |
| Truncated content | Fixed-height containers, overflow rules, or page-break constraints | Remove clipping in print CSS and test long content |
| PDF never appears | Chrome startup failure, permissions, disk path, or process timeout | Run a minimal command, check stderr, output directory permissions, and exit code |
| Fonts look substituted | Font request failed or font is absent in the runtime | Verify requests and install or bundle the required font |
9. Make a minimal reproducible case
Copy the smallest failing page into a local fixture. Include one heading, one web font, one image, one asynchronous data update, and the relevant print rules. Capture it with the same browser build and launch arguments.
node capture.js
sha256sum report.pdf
node --version
which google-chrome || which chromium
google-chrome --version
Then compare:
- the same URL in a normal browser and in headless mode;
- screen media and print media;
- the page before and after the ready selector;
- the same container image locally and in production;
- a PDF with and without backgrounds and custom fonts.
Keep the exact invocation, versions, stderr, console output, failed requests, navigation status, and a copy of the generated PDF. Those details make browser-specific failures reproducible.
10. Performance, reliability, and cost considerations
PDF generation cost is usually dominated by navigation, JavaScript execution, font loading, image decoding, and page layout. Reduce avoidable work while preserving the page state required by the document.
- Reuse a browser process when generating many documents, but create an isolated page per job.
- Set explicit navigation and readiness timeouts so a stuck page cannot occupy a worker forever.
- Block analytics, ads, and unrelated resources only when doing so cannot change the document.
- Use a stable viewport and paper size so line wrapping does not vary between runs.
- Wait for the application-ready signal instead of adding an unnecessarily large fixed delay.
- Retry transient navigation failures with a bounded retry count and record each attempt.
- Write PDFs to unique paths and verify file size before publishing them.
Do not treat a zero-byte or unusually small file as a valid PDF. Check the process exit status, PDF signature, page count, and, when possible, a text extraction or thumbnail preview.
11. Or skip the browser setup
ScreenshotNeo provides a website capture API and MCP server. It handles the browser capture path for you and can return PNG, JPEG, WebP, or PDF output. Its cleanup step accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be disabled.
One request looks like this. See the ScreenshotNeo documentation for the complete option list and PDF configuration.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
await import('node:fs/promises').then(fs => fs.writeFile('shot.webp', buffer));
ScreenshotNeo bills only clean shots. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and the response identifies the result with X-Page-Verdict and X-Billed headers. The service also supports full-page capture with lazy images loaded, element capture, custom CSS and JavaScript, click and wait actions, blocked resources, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture, usage reporting, and an MCP server with take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
There are 1,000 free shots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Create a free ScreenshotNeo account.
12. FAQ
Why does Puppeteer produce a different PDF than the screen?
Page.pdf() uses print media by default. Compare with page.emulateMediaType('screen') and inspect print-specific CSS, page size, margins, and backgrounds.
Does network idle mean the page is ready?
No. A page can finish network activity while timers, client-side rendering, workers, or application data processing continue. Wait for a selector or other application-ready signal.
Should I always use --no-sandbox?
No. Use it only as a security-sensitive workaround for a trusted, isolated environment when the host has no usable sandbox.
Why are web fonts missing even though PDF generation waits for fonts?
The font request may fail, require credentials, be blocked by policy, or have no available fallback in the runtime. Inspect requests and the container’s installed fonts.
When should I use Chrome CLI instead of Puppeteer?
Use the CLI for a simple reproducible command and Puppeteer when you need page events, application-specific readiness checks, DOM inspection, or per-page PDF options.


