How to Fetch a Web Page Programmatically
Learn how to fetch HTML with Python, browser JavaScript, cURL and Node.js, handle CORS and errors, and capture JavaScript-rendered pages.

Fetching a web page programmatically means making an HTTP request, checking the response, and reading its body. For a static page, a GET request is enough. The smallest reliable implementation also sets a timeout, checks the status code, inspects the content type, and handles network and decoding failures.
Use a server-side HTTP client when your application needs to retrieve another origin’s HTML. Use the browser Fetch API when the request is part of a permitted web application and the target server allows your origin with CORS. If the page builds its content with JavaScript, an ordinary HTTP client returns the initial response, not the final rendered page; use a documented data endpoint or an allowed browser automation or rendering service.
1. The request-response pattern
Every implementation follows the same sequence:

- Validate and normalize the URL.
- Send a GET request with a finite timeout.
- Follow redirects according to your client’s policy.
- Check the HTTP status before parsing.
- Inspect
Content-Typeand character encoding. - Read the body, while enforcing a response-size limit.
- Classify errors so callers can retry only the cases that make sense.
GET requests ask for a representation of a resource. They have no request body and are safe, idempotent and cacheable according to HTTP semantics. Query parameters belong in the URL and must be encoded. Use another method only when the site’s API contract requires it.
2. Fetch HTML with Python
Python’s standard library includes urllib.request, so no dependency is required. A Request object lets you send a truthful User-Agent and other headers. The Python documentation demonstrates the same urlopen pattern used below: Python urllib HOWTO.
from urllib.request import Request, urlopen
from urllib.error import HTTPError, URLError

url = "https://example.org/"
request = Request(url, headers={"User-Agent": "my-fetcher/1.0"})

try:
    with urlopen(request, timeout=10) as response:
        status = response.status
        content_type = response.headers.get("Content-Type", "")
        html_bytes = response.read()
        if status < 200 or status >= 300:
            raise RuntimeError(f"HTTP status {status}")
        if "text/html" not in content_type.lower():
            raise RuntimeError(f"Unexpected content type: {content_type}")
        charset = response.headers.get_content_charset() or "utf-8"
        html = html_bytes.decode(charset, errors="replace")
        print(html)
except HTTPError as exc:
    print(f"HTTP error: {exc.code} {exc.reason}")
except URLError as exc:
    print(f"Network or URL error: {exc.reason}")
except UnicodeDecodeError as exc:
    print(f"Character decoding error: {exc}")
HTTPError covers an HTTP response such as 404 or 500. URLError covers URL and network failures. A response can have a successful transport connection but still be the wrong resource, content type or encoding, so check those separately.
Python with requests
The third-party requests package has a convenient API and connection pooling controls. Set both a connect and read timeout in production, and call raise_for_status() before parsing.
import requests

response = requests.get(
    "https://example.org/",
    headers={"User-Agent": "my-fetcher/1.0"},
    timeout=(5, 15),
)
response.raise_for_status()
content_type = response.headers.get("content-type", "")
if "text/html" not in content_type.lower():
    raise ValueError(f"Unexpected content type: {content_type}")
html = response.text
print(html)
3. Fetch a page in browser JavaScript
The browser Fetch API is promise-based. It resolves to a Response even when the server returns 404 or 504, so you must check ok or status. The API and body readers are documented by MDN’s Fetch guide.
async function fetchPage(url) {
  const response = await fetch(url, { method: "GET" });
  if (!response.ok) {
    throw new Error(`HTTP ${response.status}`);
  }
  const contentType = response.headers.get("content-type") || "";
  if (!contentType.includes("text/html")) {
    throw new Error(`Unexpected content type: ${contentType}`);
  }
  return await response.text();
}

fetchPage("https://example.org/")
  .then(html => console.log(html))
  .catch(error => console.error(error));
Use response.json() for JSON, response.arrayBuffer() for binary data, and response.blob() when you need a browser Blob. A response body is a stream and can normally be consumed once.
4. CORS and the browser boundary
Browser scripts are restricted by the same-origin policy. A cross-origin Fetch request is readable only when the server returns an appropriate Access-Control-Allow-Origin header. A failed preflight, missing header or disallowed method produces a CORS error in the browser even if the server is reachable.
mode: "no-cors" is not a solution for reading another site’s HTML. It usually returns an opaque response whose headers and body are unavailable to JavaScript. When you control the application, use one of these designs:
- Expose a documented API that permits your origin.
- Fetch from your own same-origin backend and return only the data your frontend needs.
- Run the retrieval in a server-side worker where browser CORS rules do not apply.
These choices still require permission to access the target, and you should follow authentication requirements, rate limits, robots guidance and site terms.
5. Fetch with cURL
cURL is useful for debugging headers, redirects and status codes from a shell.
curl --fail-with-body --location --max-time 30 \
  --user-agent "my-fetcher/1.0" \
  --header "Accept: text/html" \
  "https://example.org/" \
  --output page.html
Add --dump-header headers.txt to save response headers. Use --head for a HEAD request when the server supports it, but do not assume a HEAD response proves that a subsequent GET will succeed. --location follows redirects; inspect the final URL when redirects matter.
6. Fetch with Node.js
Modern Node.js provides a promise-based global fetch. This example enforces a timeout with AbortController and limits the response size while reading it.
const controller = new AbortController();
const timer = setTimeout(() => controller.abort(), 15000);

try {
  const response = await fetch("https://example.org/", {
    headers: {
      "user-agent": "my-fetcher/1.0",
      "accept": "text/html"
    },
    signal: controller.signal
  });
  if (!response.ok) throw new Error(`HTTP ${response.status}`);
  const type = response.headers.get("content-type") || "";
  if (!type.toLowerCase().includes("text/html")) {
    throw new Error(`Unexpected content type: ${type}`);
  }
  const html = await response.text();
  console.log(html);
} finally {
  clearTimeout(timer);
}
For large or untrusted responses, consume the stream incrementally and stop after your configured byte limit instead of calling text() without a cap.
7. Headers, cookies, authentication and URL options
Only send headers the target documents or your application requires. A truthful, identifiable User-Agent helps site operators diagnose traffic; do not impersonate a browser to bypass controls.
| Need | Implementation | Common mistake |
|---|---|---|
| Query parameters | Use a URL builder or parameter object | Concatenating unescaped values |
| Authentication | Use the documented Authorization or cookie mechanism | Logging secrets in URLs or errors |
| Cookies | Use a cookie jar on the server | Assuming browser cookies exist in a server process |
| Redirects | Enable and limit redirects | Following an untrusted redirect indefinitely |
| Encoding | Read the charset from Content-Type when available | Assuming every page is UTF-8 |
Validate schemes and hosts before fetching user-supplied URLs. Restrict your application to https when appropriate, and protect internal networks from server-side request forgery by applying an allowlist or network egress policy.
8. Static HTML versus JavaScript-rendered pages
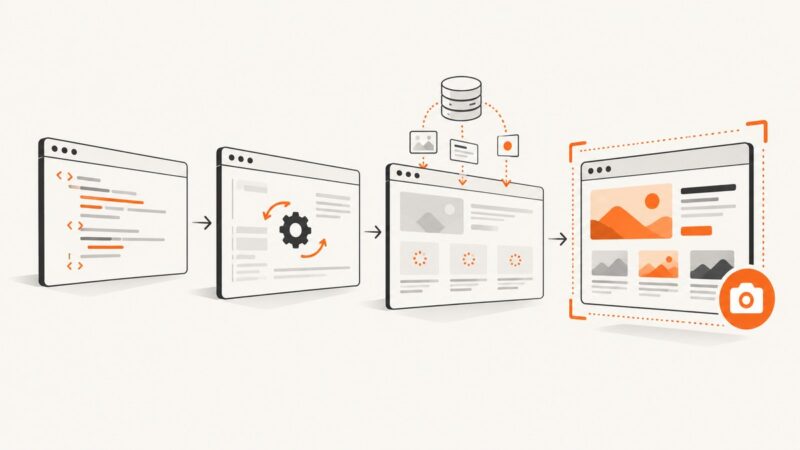
An HTTP client downloads bytes; it does not execute scripts, create a DOM, run layout, preserve browser storage or click controls. Many applications return a minimal HTML shell and fill it after load. A 200 status therefore does not prove that the visible page has been reproduced.
First inspect the HTML for a documented JSON or GraphQL endpoint. Calling that endpoint is usually faster and more stable than rendering a page. If no permitted endpoint exists, use browser automation or a rendering service that can wait for the application to become ready. Define a readiness condition such as a selector, network idle, or a bounded delay. Treat CAPTCHA and bot checks as access controls, not as errors to bypass.
9. Or skip the browser setup
If your goal is a screenshot or PDF of the finished page, ScreenshotNeo provides a single GET request that returns PNG, JPEG, WebP or PDF. Its capture pipeline accepts cookie and consent banners as a visitor and removes more than 60 known consent platforms, newsletter popups and chat widgets; each step can be turned off.

See the ScreenshotNeo API documentation for all options. A minimal call is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo supports full-page captures with lazy images loaded, CSS-selector element captures, dark mode, 12 device presets and custom viewports, retina scale, PDF paper size and margins, custom CSS and JavaScript, clicks, selector or network-idle waits, blocked ads and trackers, custom headers, cookies, user agents and Authorization, timezone and geolocation, transparent backgrounds, image resizing, configurable caching, signed links, asynchronous jobs with signed webhooks, bulk capture of 100 URLs per call, a usage API and an OpenAPI specification. Parameter names used by other screenshot APIs also work.
Only clean shots are billed. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits cost nothing, and the response identifies the result with X-Page-Verdict and X-Billed headers. An MCP server exposes take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients.
Free usage includes 1,000 screenshots per month without a card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Create a free ScreenshotNeo account.
10. Reliability, performance and cost
Timeouts and retries
Set separate connect and read limits where your client supports them. Retry only transient DNS, connection-reset, 408, 429 and selected 5xx failures. Use exponential backoff with jitter and a maximum attempt count. Do not retry malformed URLs, authentication failures or most 4xx responses without changing the request.
Connection reuse
Reuse a session or HTTP agent for repeated requests. Pooling reduces handshake overhead and keeps throughput predictable. Respect the target’s rate limits and avoid unbounded concurrency.
Memory and response size
Cap bytes before buffering a response. Reject unexpected content types before attempting expensive parsing. Store large bodies on disk or stream them to downstream processing.
Caching
Honor cache headers when possible. An application cache can reduce latency and origin load, but include the URL, relevant headers and authentication context in the cache key. Never share a private response across users.
Rendered capture costs
Rendering requires more work than downloading HTML because a browser must load resources and execute scripts. Keep waits bounded, block resources you do not need, capture one element instead of a full page when that is sufficient, and use a chosen cache TTL for repeated captures. ScreenshotNeo reports whether a response was billed, so your accounting can distinguish clean captures from failed or cached attempts.
11. Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Browser says “blocked by CORS policy” | Target did not authorize your origin | Use a permitted API, same-origin backend or server-side fetch. |
| Fetch resolves but status is 404 or 500 | Fetch does not reject on HTTP errors | Check response.ok or status before reading. |
| HTML is a nearly empty shell | Content is inserted by JavaScript | Find the data endpoint or use permitted rendering. |
| Python raises HTTPError | Server returned an HTTP error status | Log the status, handle the class explicitly and avoid blind retries. |
| Timeout or connection reset | Slow origin, network path or overloaded service | Set bounded timeouts, retry transient failures with backoff and reduce concurrency. |
| Garbled accented characters | Wrong assumed encoding | Read the declared charset and decode with a controlled fallback. |
| Unexpected JSON, PDF or image | URL redirected or content type changed | Inspect final URL and Content-Type before parsing. |
| Screenshot shows a consent banner | Capture happened before consent handling or the site uses an unsupported flow | Enable the relevant ScreenshotNeo consent step and wait for a stable selector. |
12. Production checklist
- Accept only URL schemes and hosts your application is designed to fetch.
- Use finite connect, read and total timeouts.
- Check status, content type, final URL and encoding before parsing.
- Limit response bytes and concurrency.
- Use a truthful User-Agent and documented authentication.
- Reuse connections and apply bounded backoff for transient errors.
- Respect robots.txt guidance, rate limits and site terms.
- Record request duration, status, retry count and failure category without logging secrets.
- For rendered pages, define a readiness condition and a maximum wait.
13. FAQ
Can I fetch any URL from browser JavaScript?
No. The target must permit your origin through CORS, and the request must satisfy browser security rules.
Does a 200 response mean I downloaded what a user sees?
No. It means the server returned a successful response. JavaScript-rendered content may not be present in that body.
Should I use GET or POST?
Use GET for retrieving a representation. Follow the target API’s contract when it requires POST or another method.
How do I avoid hanging workers?
Set finite timeouts, cancel requests that exceed them, cap body size and keep retries bounded.
When is a screenshot API preferable to raw HTML?
Use one when you need the rendered visual result, browser waits, PDF output or consistent consent and popup cleanup rather than source HTML.