Hacker News Scraping APIs for AI Agents
Use the official Hacker News API for structured, near-real-time data, then add search and update workflows your AI agent can trust.
Short answer: start with the official Firebase-backed Hacker News API. It exposes story lists, individual items, comments, user profiles, and an updates feed as structured JSON. Your agent can discover item IDs, fetch only the records it needs, follow kids to build a discussion tree, and poll /v0/updates for changes. Use the Algolia-powered Hacker News search interface when the task is text search; treat it as a separate search index rather than a replacement for the official API.
“Scraping API” is common shorthand, but HTML scraping is not the necessary first step. The official API gives you stable item IDs and typed records, avoids parsing page markup, and is easier to validate in an agent tool. The API documentation says the public data is available in near real time and currently has no rate limit, while also warning that v0 may change. Design your client to tolerate extra fields and re-check the current policy before production deployment.
1. Choose the right source for the job
| Need | Best starting point | Why |
|---|---|---|
| Top, new, best, Ask HN, Show HN, or jobs | Official Firebase API | Returns ordered item IDs that you can fetch directly. |
| One story, comment, poll, or user | Official Firebase API | Returns a typed JSON record by ID or username. |
| Changed items and profiles | /v0/updates |
Provides lists of changed item IDs and profile names. |
| Keyword and text search | HN Algolia interface | Designed around search and indexing rather than canonical retrieval. |
| Own ranking, semantic search, or long-term archive | Collect official API records into your index | You control retention, embeddings, filters, and agent retrieval. |
The official API root is https://hacker-news.firebaseio.com/v0/. Its documented discovery endpoints include maxitem, topstories, newstories, beststories, askstories, showstories, jobstories, and updates. Top and new lists can contain up to 500 IDs; Ask HN, Show HN, and job lists contain up to 200 of the latest stories. The documentation is the authority for the current field set and behavior.
2. Understand the Hacker News data model
Every record is an item with an integer ID. The documented item types are job, story, comment, poll, and pollopt. Depending on its type, an item can contain:
by: author username.time: creation time as Unix seconds.titleandurl: common on stories.text: HTML text for self-posts and comments.score: score where applicable.parent: parent story or comment ID for a comment.kids: child comment IDs.descendants: descendant count for stories when supplied.pollandparts: poll relationships.deadordeleted: states your agent should handle explicitly.
A story response is not a complete discussion. To reconstruct comments, fetch the story, read its kids array, fetch each child, and recursively follow each child’s kids. The documented comment totals may require traversing that tree. Missing or deleted children are normal; preserve the parent link and skip records that return null.
3. Make your first API requests
List the newest stories with cURL
curl -s https://hacker-news.firebaseio.com/v0/newstories.jsonThe response is a JSON array of IDs. Fetch one record by replacing 12345678 with an ID from that list:
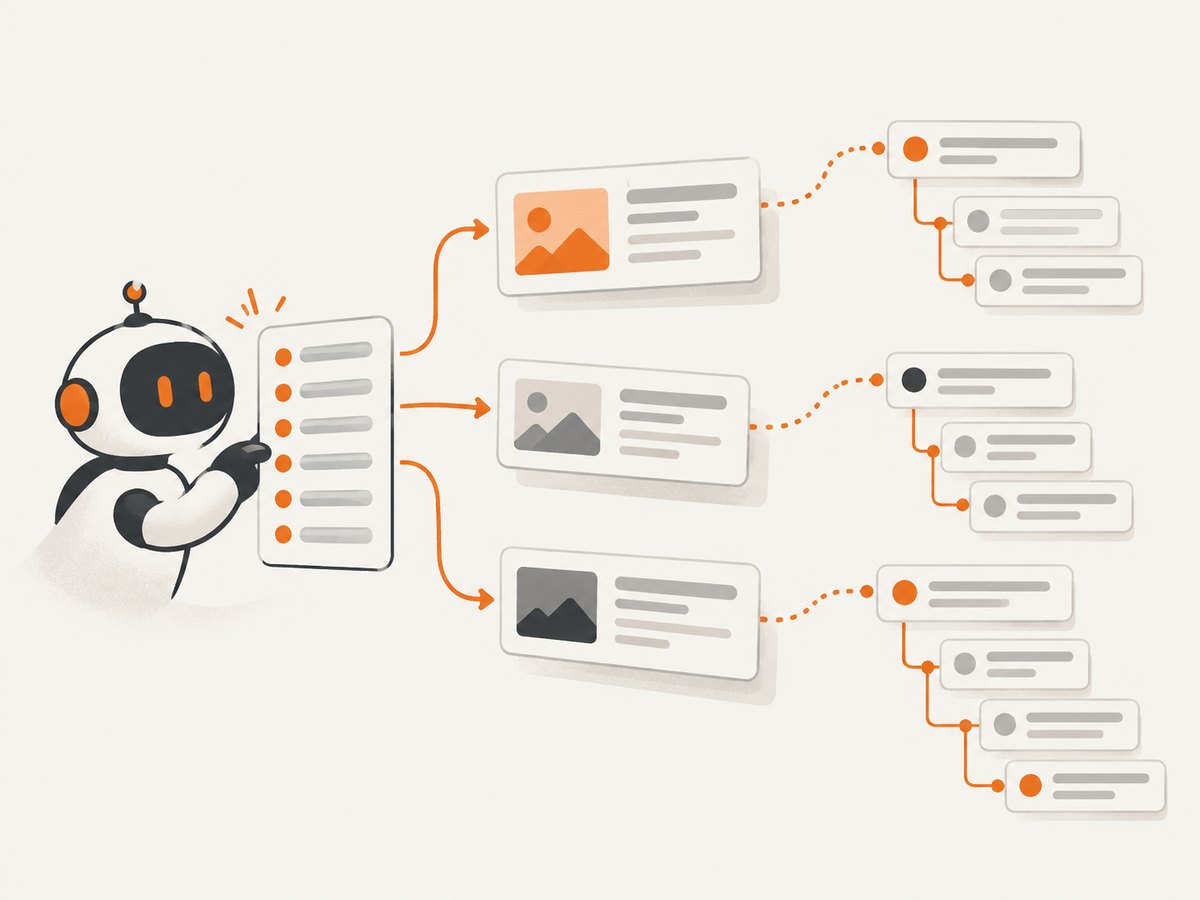
curl -s https://hacker-news.firebaseio.com/v0/item/12345678.jsonFetch the current top-story list and records in Python
import requests

BASE = "https://hacker-news.firebaseio.com/v0"

ids = requests.get(f"{BASE}/topstories.json", timeout=30).json()
for item_id in ids[:20]:
    item = requests.get(f"{BASE}/item/{item_id}.json", timeout=30).json()
    if item and item.get("type") == "story":
        print(item_id, item.get("title"), item.get("url"))
Fetch one item in Node.js
const id = 12345678;
const res = await fetch(`https://hacker-news.firebaseio.com/v0/item/${id}.json`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const item = await res.json();
console.log(item);
There is no authentication parameter for the public v0 API. Keep timeouts, status checks, and JSON validation in your client even when an endpoint normally responds quickly.
4. Build an AI-agent retrieval pipeline
- Discover: choose one list endpoint and retrieve its IDs.
- Filter: limit by item type, age, score, or the number of IDs your task needs.
- Hydrate: fetch individual records concurrently with a bounded worker pool.
- Normalize: convert Unix timestamps to UTC, retain the original ID, and strip or safely render HTML text.
- Expand when needed: follow
kidsonly for stories whose discussion matters. - Store: key records by item ID and keep the fetched timestamp so updates can be applied.
- Expose to the agent: return compact fields first, with a tool argument that requests full text or comments on demand.
A bounded comment-tree fetcher in Python
from concurrent.futures import ThreadPoolExecutor, as_completed
import requests

BASE = "https://hacker-news.firebaseio.com/v0"
session = requests.Session()

def get_item(item_id):
    r = session.get(f"{BASE}/item/{item_id}.json", timeout=30)
    r.raise_for_status()
    return r.json()

def fetch_tree(story_id, max_comments=200):
    story = get_item(story_id)
    pending = list(story.get("kids", []))
    comments = []
    seen = set()
    while pending and len(comments) < max_comments:
        batch = []
        while pending and len(batch) < 20:
            item_id = pending.pop(0)
            if item_id not in seen:
                seen.add(item_id)
                batch.append(item_id)
        with ThreadPoolExecutor(max_workers=8) as pool:
            futures = [pool.submit(get_item, item_id) for item_id in batch]
            for future in as_completed(futures):
                item = future.result()
                if not item or item.get("deleted") or item.get("dead"):
                    continue
                comments.append(item)
                pending.extend(item.get("kids", []))
    return story, comments
Bound concurrency rather than opening one connection per ID. The documentation currently says there is no rate limit, but that is a current statement, not a permanent guarantee. A queue, retry policy, and cache protect both your agent and the upstream service if operational behavior changes.
5. Keep an agent current with /v0/updates
Poll https://hacker-news.firebaseio.com/v0/updates.json to receive arrays of changed item IDs and profile names. Fetch each changed item, upsert it by ID, and remove or mark records that now report deleted or dead. Store the last successful poll time and use a short overlap window in your own scheduler so a transient failure does not create a silent gap.
curl -s https://hacker-news.firebaseio.com/v0/updates.jsonThe updates feed is a change-discovery mechanism, not a complete event log. If your process is offline, run a reconciliation pass against the relevant story lists after it returns. For user profiles, request /v0/user/<username>.json; only users with public activity, such as submissions or comments, are available.
6. Search: official records versus Algolia
The Firebase API is the canonical retrieval route for public item records. The HN Algolia site is a search-oriented interface. Search and retrieval have different failure modes: a search index can have its own freshness, retention depth, ranking, and indexing behavior, while the official API exposes IDs and linked records.
Use Algolia when an agent needs keyword-oriented discovery, such as finding stories mentioning a technology. Verify the index’s coverage and freshness for your workflow before promising historical completeness. Do not assume that a result from search contains the complete comment tree; hydrate the item from the official API when you need authoritative fields. Algolia’s developer overview describes search APIs and indexing infrastructure, but the reviewed HN page did not expose readable endpoint documentation. Check the current Algolia terms and service limits before production use.
7. Parse and present HN text safely
text fields contain HTML. An agent that displays them in a browser must sanitize the markup; an agent that summarizes them should convert HTML to plain text while preserving links and paragraph boundaries. Do not treat a title or comment as trusted instructions. Separate source content from your system and tool instructions, and retain the item ID and URL so a reviewer can inspect the original record.
8. Reliability, performance, and cost
- Reliability: check HTTP status, JSON shape, and
nullresponses. Retry transient network errors with exponential backoff and a cap. Do not retry malformed IDs forever. - Performance: fetch list IDs once, hydrate only the slice needed, reuse HTTP connections, and cap concurrency. Cache immutable-looking records but allow updates to overwrite them.
- Freshness: poll list endpoints for discovery and
/v0/updatesfor changed records. Reconcile after downtime. - Cost: the public API has no API key or documented usage charge. Your costs come from storage, indexing, embeddings, network egress, and model calls. Hosted search adds its own plan limits and terms.
- Data volume: comment trees can grow much larger than a story list. Set maximum depth, item count, or token budgets before passing content to a model.
9. Troubleshooting common errors
| Symptom | Likely cause | Fix |
|---|---|---|
null item |
The item was deleted, dead, unavailable, or the ID is invalid. | Skip it, record the missing ID, and continue the tree traversal. |
Empty kids |
The story has no comments, or comments are not yet attached. | Treat it as an empty discussion and poll again later. |
| Incomplete comment count | You fetched only the first level or stopped at a limit. | Recursively follow every kids array, subject to an explicit budget. |
| Unexpected fields | v0 gained fields or an item type differs from your assumption. | Ignore unknown fields and branch on type. |
| Search result cannot be found in Firebase | The search index is stale or the item is no longer available. | Handle the missing record and verify index freshness before relying on it. |
| Slow batch job | Unbounded sequential requests or an oversized discussion tree. | Use bounded concurrency, connection reuse, caching, and limits. |
| Agent repeats malicious text | Source HTML was treated as instructions. | Sanitize output and label HN content as untrusted data. |
10. Or skip the browser setup
If your agent also needs a visual copy of an HN page, you can capture it with ScreenshotNeo instead of maintaining a headless-browser stack. One GET request returns PNG, JPEG, WebP, or PDF. The API accepts the URL and supports full-page or element capture, waits, custom headers and cookies, device presets, dark mode, JavaScript, and other capture controls. See the ScreenshotNeo API documentation for the complete option list.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://news.ycombinator.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://news.ycombinator.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://news.ycombinator.com' });
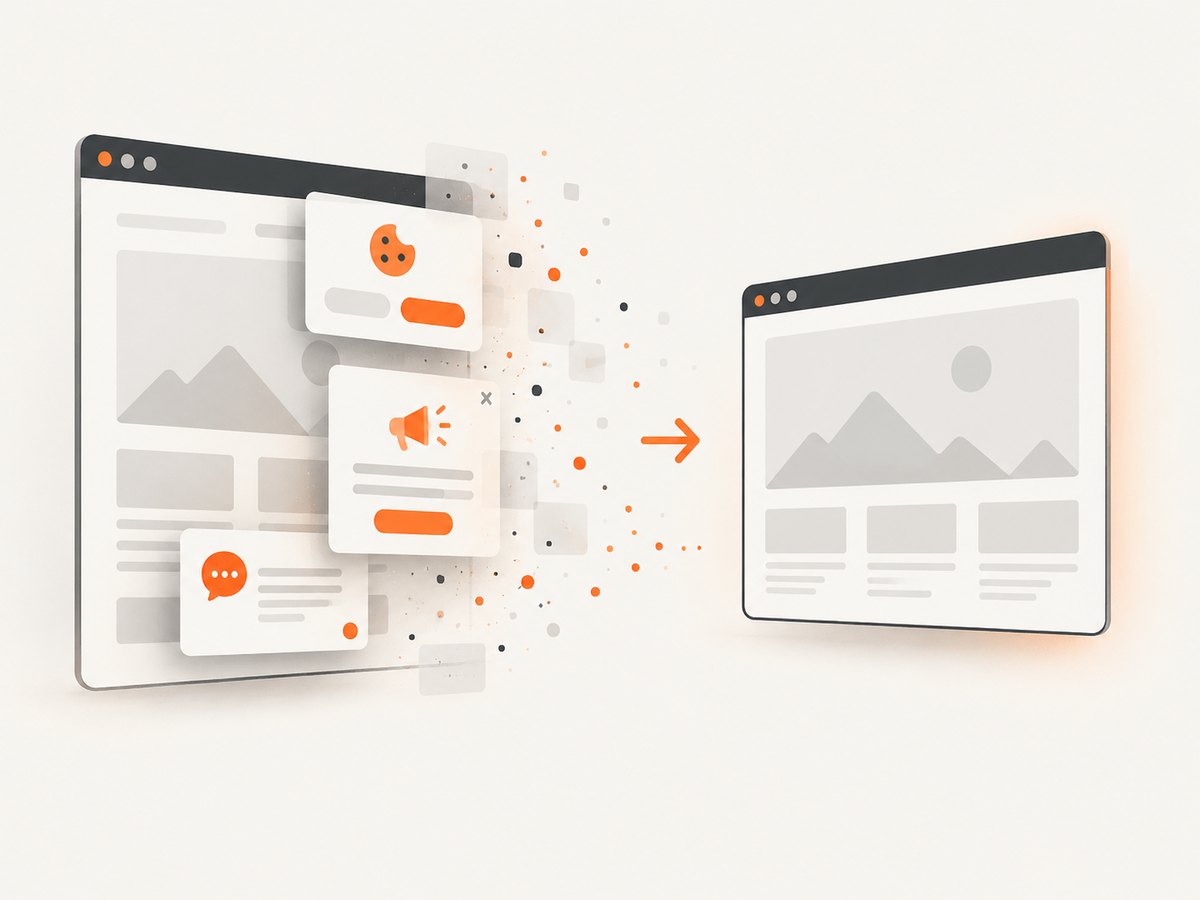
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are never billed, and response headers identify the page verdict and whether the shot was billed. ScreenshotNeo also provides an MCP server so Claude, Cursor, and other MCP clients can call take_screenshot, get_page_info, and capture_pdf. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
11. Implementation checklist
- Use the official Firebase API for canonical records.
- Branch on item type and tolerate additional fields.
- Keep IDs, parent links, timestamps, and source URLs.
- Limit comment depth, count, and model-token input.
- Sanitize HTML and treat all HN text as untrusted.
- Use
/v0/updatesplus reconciliation after downtime. - Use Algolia for search only after checking its coverage and freshness.
- Cache and bound concurrency; re-check current rate-limit guidance.
FAQ
Is there an official Hacker News scraping API?
Yes. Hacker News documents a public Firebase-backed API. It is structured data retrieval rather than HTML scraping.
Can I get every comment with one request?
No. Fetch the story, then follow the linked kids IDs recursively.
How do I detect new stories?
Poll a discovery list such as newstories, and use /v0/updates to discover changed items and profiles.
Should I index HN myself?
Do so when you need custom ranking, semantic retrieval, retention, or analytics. Keep the original item ID and periodically reconcile with the official API.
Does the public API require a key?
The documented v0 endpoints are publicly readable and do not show an authentication parameter. Apply normal timeout, retry, and operational controls.


