HTTP vs. HTTPS in Web Scraping
HTTPS should be your default for scraping: learn what it protects, how redirects and cookies change results, and how to implement it safely.
Use HTTPS by default when scraping. HTTPS is HTTP carried over Transport Layer Security (TLS), so it encrypts traffic, detects in-transit modification, and helps your client authenticate the server. HTTP sends the same requests and responses without that transport protection. HTTPS does not make scraping authorized, guarantee complete data, or prevent a site from detecting automation.
The practical rule is simple: start with an https:// URL, keep certificate and hostname verification enabled, follow redirects deliberately, preserve the final HTTPS URL, and log enough metadata to explain differences between captures.
What HTTPS changes for a scraper
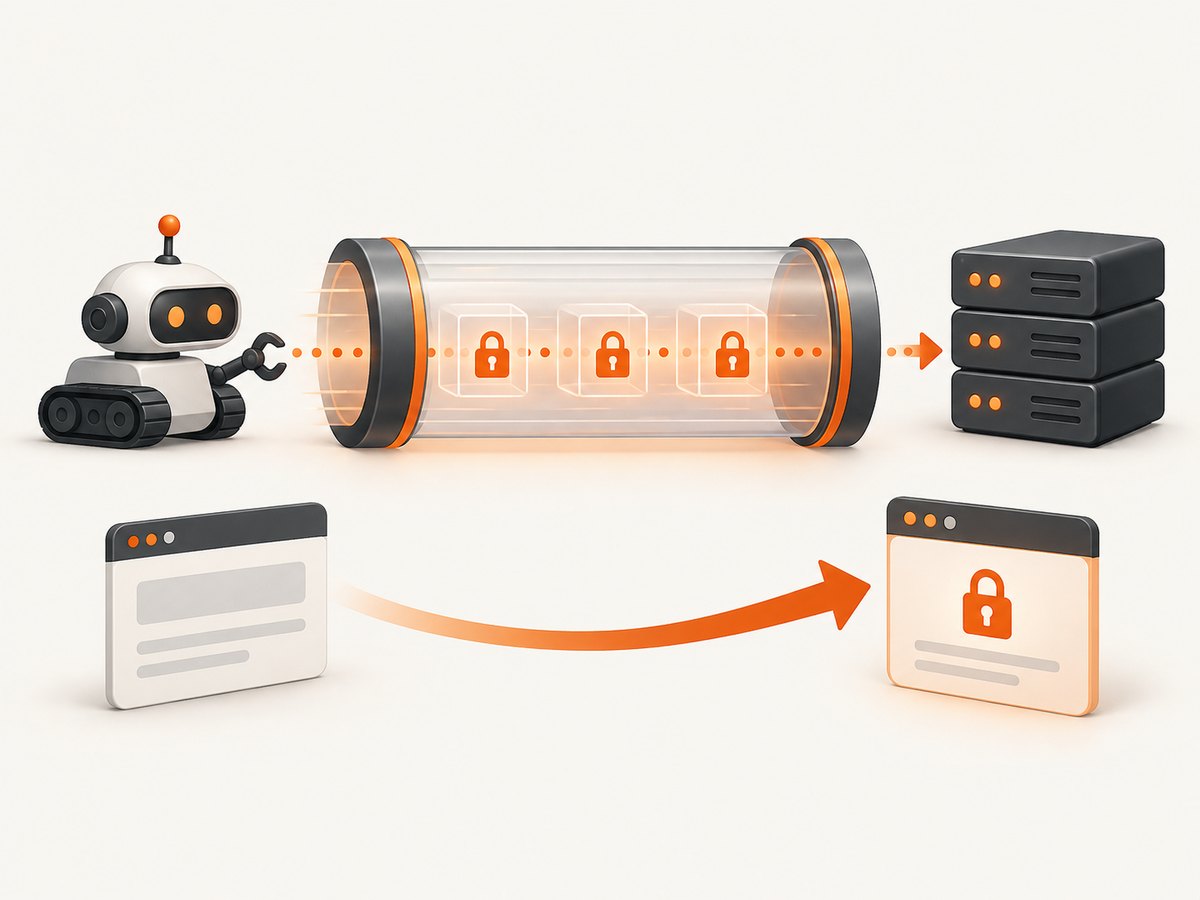
MDN describes TLS as providing encryption, integrity, and authentication for a network connection. With plain HTTP, an on-path observer can read or alter URLs, headers, cookies, request bodies, and responses. HTTPS protects those bytes while they travel and helps your client verify that it reached the intended host. See MDN’s TLS explanation and its MITM guidance.
| Concern | HTTP | HTTPS |
|---|---|---|
| Confidentiality | Traffic is readable on the path. | Application data is encrypted in transit. |
| Integrity | Traffic can be modified without reliable detection. | Tampering is detected by TLS. |
| Server identity | No certificate-based server authentication. | Certificate and hostname checks help verify the endpoint. |
| Cookies | Secure cookies are not sent. |
Secure cookies can be sent to the matching HTTPS origin. |
| Browser subresources | HTTP resources can load, subject to policy. | HTTP subresources may be blocked as mixed content. |
| Compatibility | Some legacy servers still accept it. | Required by many modern sites and APIs. |
HTTPS protects transport only. The page can still contain stale or false information, JavaScript can still render data after the initial response, and the site can still enforce authentication, rate limits, robots directives, or anti-bot controls.
HTTP-to-HTTPS redirects, HSTS, and canonical URLs
Many sites keep port 80 open only to return a permanent redirect to HTTPS. That is convenient when a user types an HTTP address, but the first request is exposed to interception before the redirect. HSTS tells a user agent to use HTTPS directly on later visits and helps prevent SSL-stripping attacks. OWASP recommends TLS for all pages and says API-only endpoints should generally disable HTTP or reject unencrypted requests instead of relying on redirects. Read the OWASP TLS Cheat Sheet.
For a crawler:
- Seed the job with the HTTPS URL when you know it.
- Allow redirects only to policies and hosts your crawler permits.
- Record every status code and
Locationvalue. - Use the final HTTPS URL as the canonical fetch address.
- Handle authenticated, signed, or POST requests explicitly; blindly replaying credentials across a redirect can leak them.
Does HTTPS change scraped results?
It can. A server may return identical HTML over both schemes, but the origin is different and site policy can vary. HTTPS may:
- Redirect to a different canonical URL.
- Send
Securecookies that HTTP cannot receive. - Enable authentication or signed requests bound to the scheme.
- Load JavaScript and API calls that fail when requested over HTTP.
- Block HTTP scripts, images, fonts, or stylesheets as mixed content.
- Reach a different virtual host, cache key, or regional edge configuration.
When comparing captures, treat the schemes as separate origins. Log the status code, redirect chain, final URL, response headers, cookie attributes, content hash, and the time of the request. HTTPS itself is not a completeness guarantee: client-rendered content, personalization, authentication, and anti-bot controls often have a larger effect on output.
Implementing an HTTPS-first scraper in Python
Python Requests enables certificate verification, sessions, proxies, timeouts, streaming, decompression, and status handling. The following example follows redirects, retains cookies, checks the response, and records the final URL.
import hashlib
import requests

url = "https://example.com/"
headers = {
    "User-Agent": "ExampleResearchBot/1.0 (+https://example.com/bot-info)"
}

with requests.Session() as session:
    response = session.get(
        url,
        headers=headers,
        timeout=(10, 45),       # connect timeout, read timeout
        allow_redirects=True,
        verify=True,
    )
    response.raise_for_status()

    body = response.content
    print("status:", response.status_code)
    print("final_url:", response.url)
    print("redirects:", [r.status_code for r in response.history])
    print("sha256:", hashlib.sha256(body).hexdigest())

    with open("page.html", "wb") as output:
        output.write(body)
Do not set verify=False to silence a certificate error. Fix the target certificate, install the documented private trust store, or escalate the infrastructure issue. If you need a proxy, configure it explicitly and understand that the proxy can observe traffic according to its trust model.
Handling size, status, and retries
Set a maximum accepted response size before storing large downloads. Retry transient connection failures and selected 5xx responses with exponential backoff, but do not retry non-idempotent requests automatically. A retry policy should also respect the site’s rate limit and any Retry-After header. For a large response, use stream=True, read in bounded chunks, and stop when your limit is reached.
Equivalent commands with cURL
curl --fail --show-error --location \
  --connect-timeout 10 --max-time 60 \
  --user-agent "ExampleResearchBot/1.0 (+https://example.com/bot-info)" \
  --dump-header response.headers \
  "https://example.com/" \
  --output page.html
cURL verifies certificates by default. Use a specific CA bundle with --cacert for a documented private environment. Avoid -k/--insecure in production because it disables certificate verification.
Node.js implementation
Modern Node.js provides fetch. Check the status before consuming the body and use an abort signal to enforce a deadline.
const controller = new AbortController();
const timer = setTimeout(() => controller.abort(), 60_000);

try {
  const response = await fetch('https://example.com/', {
    redirect: 'follow',
    headers: {
      'user-agent': 'ExampleResearchBot/1.0 (+https://example.com/bot-info)'
    },
    signal: controller.signal
  });

  if (!response.ok) {
    throw new Error(`HTTP ${response.status} for ${response.url}`);
  }

  const html = await response.text();
  console.log({ status: response.status, finalUrl: response.url });
  console.log(html);
} finally {
  clearTimeout(timer);
}
Node’s default TLS validation should remain enabled. For advanced connection pooling, proxy support, or custom CA configuration, use the supported HTTPS agent or dispatcher for your Node version and document the trust decision.
Configuration checklist for production crawlers
- URL policy: accept only schemes and hosts your job is allowed to visit; normalize URLs without destroying meaningful query parameters.
- TLS: verify certificates and hostnames; keep TLS libraries and the runtime current.
- Redirects: cap redirect hops, record the chain, and prevent unexpected host changes.
- Timeouts: separate connect and read timeouts; add an overall deadline.
- Sessions: reuse connections and cookies when the workflow requires them.
- Headers: send an honest User-Agent and only the authentication headers required for the target.
- Resources: for browser rendering, request scripts, styles, images, and APIs over HTTPS where possible.
- Limits: cap response sizes, queue depth, concurrency, and retry count.
- Compliance: respect robots.txt, terms, authentication boundaries, rate limits, and opt-out mechanisms. robots.txt is guidance, not permission or a security boundary.
- Observability: store timestamps, status, redirect history, final URL, certificate errors, response size, and a content hash.
Performance, reliability, and cost
There is no authoritative universal percentage for how much HTTPS slows scraping. Latency varies with TLS version, connection reuse, HTTP version, network path, and server configuration. A new TLS connection adds handshake work; persistent sessions amortize that cost. Measure your own workload with and without connection reuse instead of applying a fixed rule.
HTTPS usually improves reliability because it avoids interception and supports the cookies and APIs modern sites require. It can also expose certificate, hostname, clock, or trust-store problems that HTTP would hide. Fix those failures rather than bypassing validation.
Transport encryption does not determine your total scraping cost. The larger drivers are browser rendering, bandwidth, retries, proxy usage, storage, and request volume. Keep concurrency within the site’s limits and cache responses when policy allows.
Common errors and fixes
| Error | Likely cause | Fix |
|---|---|---|
| Certificate verify failed | Expired, mismatched, untrusted, or privately issued certificate; incorrect system clock. | Correct the target or install its documented CA. Keep verification enabled. |
| Hostname mismatch | The URL host is not covered by the certificate. | Use the correct canonical hostname or fix server certificate configuration. |
| Too many redirects | HTTP/HTTPS loop, locale redirect, or authentication flow. | Inspect the chain, cap hops, and start from the canonical HTTPS URL. |
| 401 or 403 | Missing credentials, disallowed crawler, or anti-bot policy. | Use authorized credentials, follow the site’s policy, and do not evade controls. |
| 429 | Rate limit exceeded. | Reduce concurrency, honor Retry-After, and add backoff. |
| Blank or incomplete HTML | Content is rendered by JavaScript or requires cookies and API calls. | Use an authorized browser workflow, wait for the required selector, and capture dependent resources over HTTPS. |
| Mixed-content warnings | A secure page requests HTTP subresources. | Prefer HTTPS resource URLs and investigate blocked requests. |
| Timeout | Slow origin, blocked resource, or overloaded worker. | Use separate connect/read deadlines, bounded retries, and capture diagnostics. |
Or skip the browser setup
ScreenshotNeo provides a website screenshot API and MCP server when your job needs a rendered page rather than raw HTML. One GET request returns PNG, JPEG, WebP, or PDF. See the ScreenshotNeo API documentation for the complete option list.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
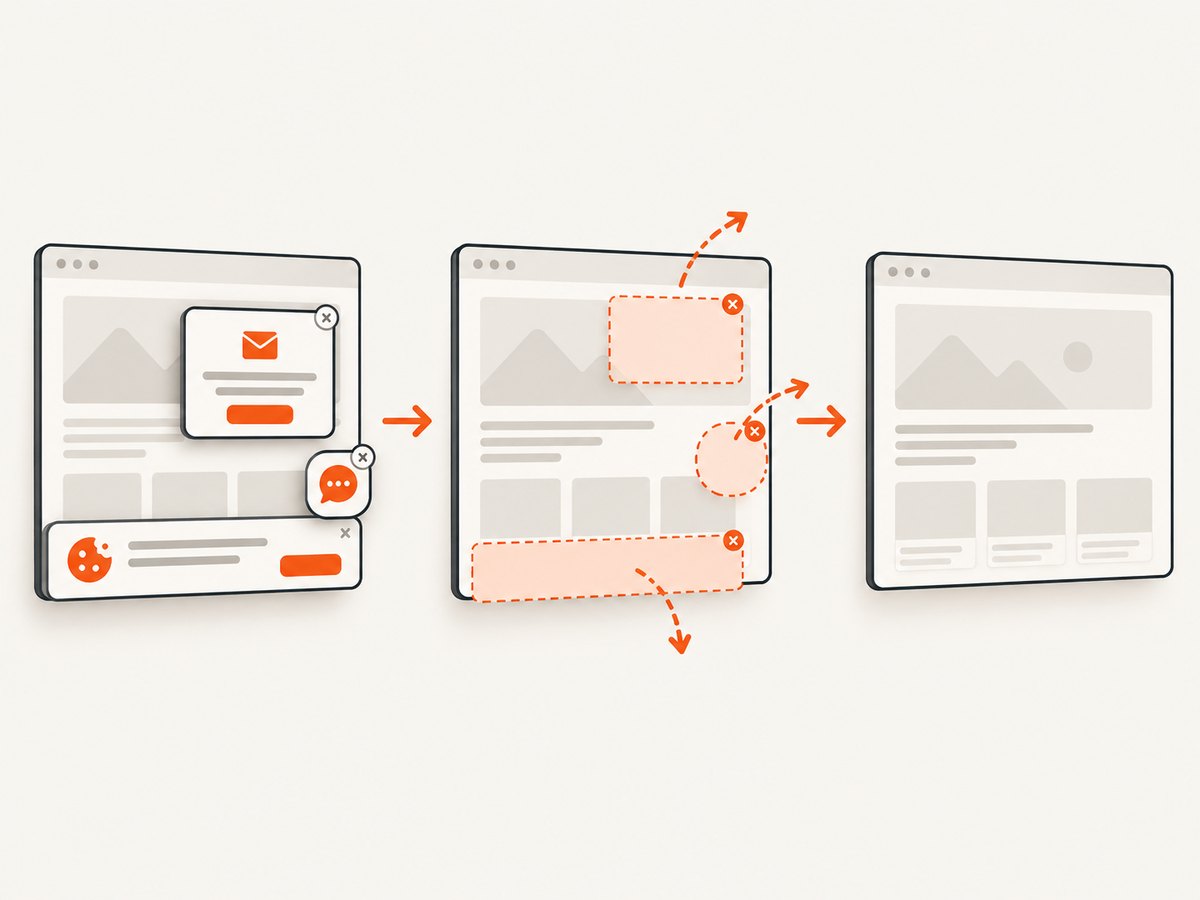
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot; bot checks, blank pages, timeouts, failed loads, and cache hits are never billed, and response headers identify the page verdict and billing result. The MCP server includes take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. You can also set viewport and device options, wait conditions, custom headers and cookies, JavaScript and CSS, blocking rules, caching TTL, PDF settings, signed links, asynchronous webhooks, and bulk capture.
There are 1,000 screenshots per month free with no card. Paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Should every scraper use HTTPS?
Use HTTPS by default. Use HTTP only when you have a specific, authorized legacy requirement and understand that traffic can be observed or modified.
Does HTTPS make a crawler anonymous?
No. TLS protects the connection in transit. The destination can still see your IP, headers, behavior, cookies, and authentication state.
Can I scrape a site because it uses HTTPS?
No. HTTPS says how the connection is protected, not whether crawling is permitted. Check the site’s terms, robots guidance, authentication boundaries, rate limits, and opt-out process.
Should I compare HTTP and HTTPS as the same page?
No. Compare final URLs, redirects, cookies, headers, content hashes, and rendered resources because the two schemes can produce different results.
Is disabling certificate verification ever a good production fix?
No. Repair the certificate or configure the documented trust store. Disabling verification removes the identity and integrity checks HTTPS is meant to provide.
Does HTTPS always require a browser?
No. Requests, cURL, and Node.js can fetch HTTPS directly. Use a browser only when JavaScript execution, interaction, or layout rendering is part of the data you need.


