How to Extract Structured Data from Websites with an API
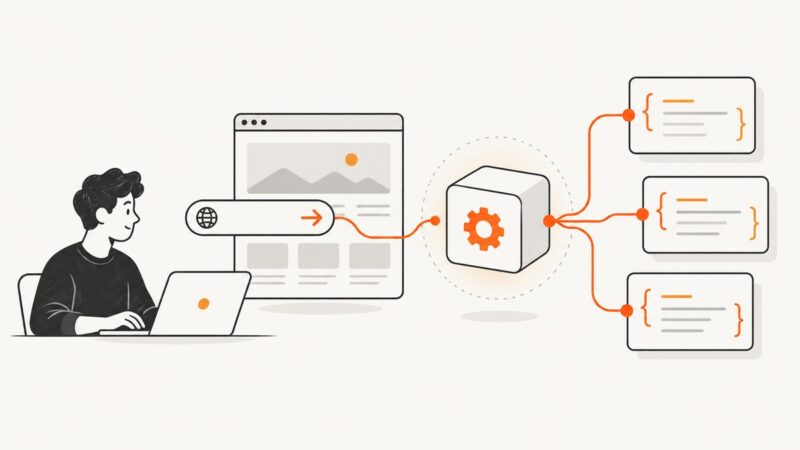
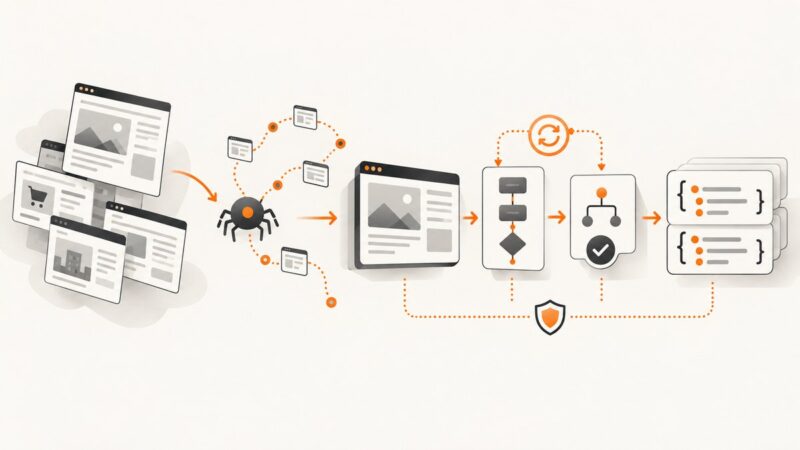
Learn how to turn web pages into validated JSON with extraction APIs, schemas, crawlers, browser rendering, retries, and production safeguards.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
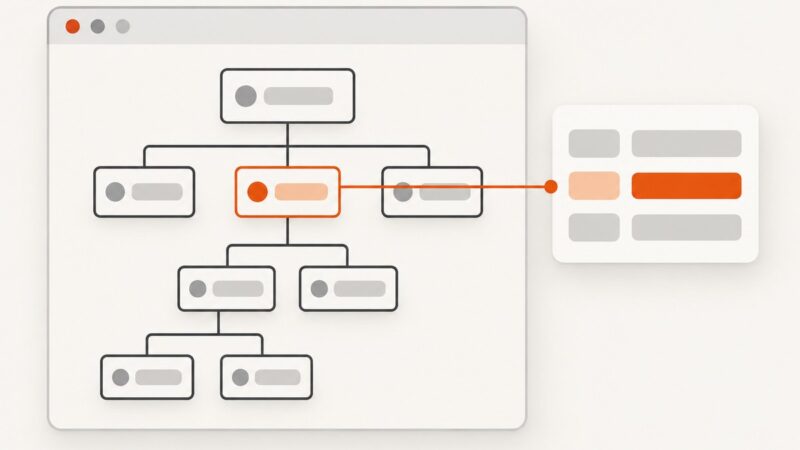
Learn how to turn web pages into validated JSON with extraction APIs, schemas, crawlers, browser rendering, retries, and production safeguards.
Build a reliable Open Graph scraper for link previews with Python, cURL, Node.js, fallbacks, troubleshooting, and a managed API option.
There is no universal API quota reset. Identify whether you hit a temporary rate limit, an account spending cap, or a changeable service quota, then use the right fix.
Learn how to configure, authenticate, test, automate, and troubleshoot web-scraping API requests in Postman, with reusable collections and scripts.
Build a reliable Google Sheets queue that drafts, renders, publishes and tracks Instagram carousels and Reels without duplicate posts.
Build a secure Node.js screenshot webhook receiver: preserve raw bodies, verify provider signatures, process events safely, and troubleshoot delivery.
Compare hosted HTML-to-DOCX APIs and local libraries, with runnable cURL, Python, Node.js and .NET examples, troubleshooting and production guidance.
Learn every CSS attribute selector: presence, exact, token, prefix, suffix, substring, case flags, combinations, debugging, and automation examples.
Learn how to check CAA records, trace parent and CNAME policies, fix blocked renewals, and verify which certificate authorities can issue for your domain.
Capture consistent screenshots of prospect websites at scale. Learn how to queue URLs, choose views, handle failures, secure images, and control cost.
Compare the PDF options APIs expose, from page size and margins to fonts, accessibility, pagination, and asynchronous jobs.
Fetch a known page with HTTP or a browser, convert it to Markdown for readable context, or extract validated fields into JSON.
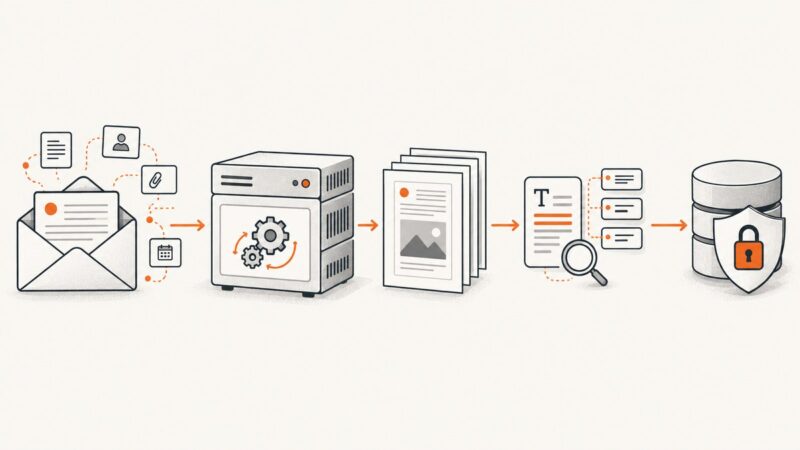
Design a reliable email-to-image archive with originals, manifests, OCR, validation, and a scalable rendering pipeline.
A permission-first guide to inspecting BigGo pages, extracting article text with Python, cURL and Node.js, and handling rendering and errors.
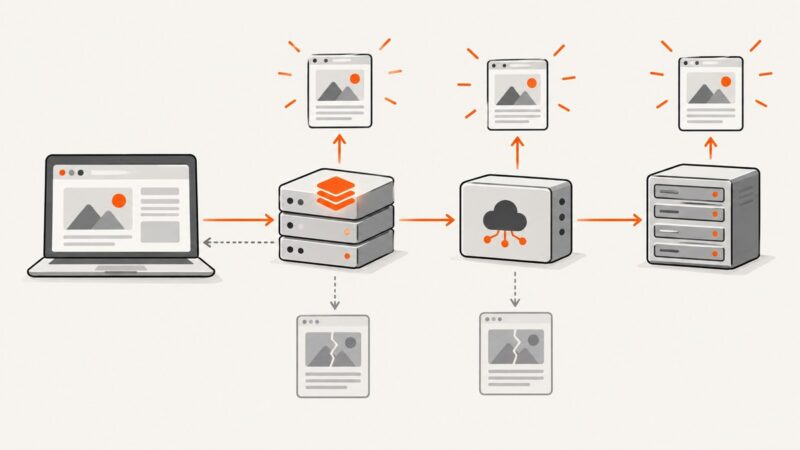
Learn how HTTP caches differ from scraper result caches, how freshness and revalidation work, and what to check before relying on a vendor’s cache.
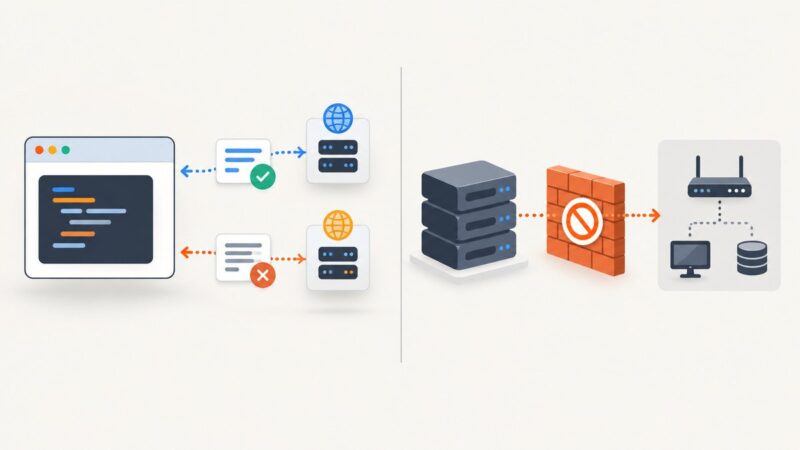
CORS controls what browser scripts can read; it does not stop a server-side URL fetch from reaching internal services. Learn how to protect both boundaries.
Build a traceable competitor website audit with Claude, web search, page retrieval, browser tools, and MCP. Capture pages and separate evidence from inference.
Capture a webpage as a PNG in TypeScript with Playwright, including full-page, element, and in-memory screenshots, plus reliable waits and cleanup.