How to Process All Scraped Pages with Playwright Python Async
Build a reliable async Playwright scraper that handles readiness, pagination, infinite scroll, bounded concurrency, retries, and complete result tracking.
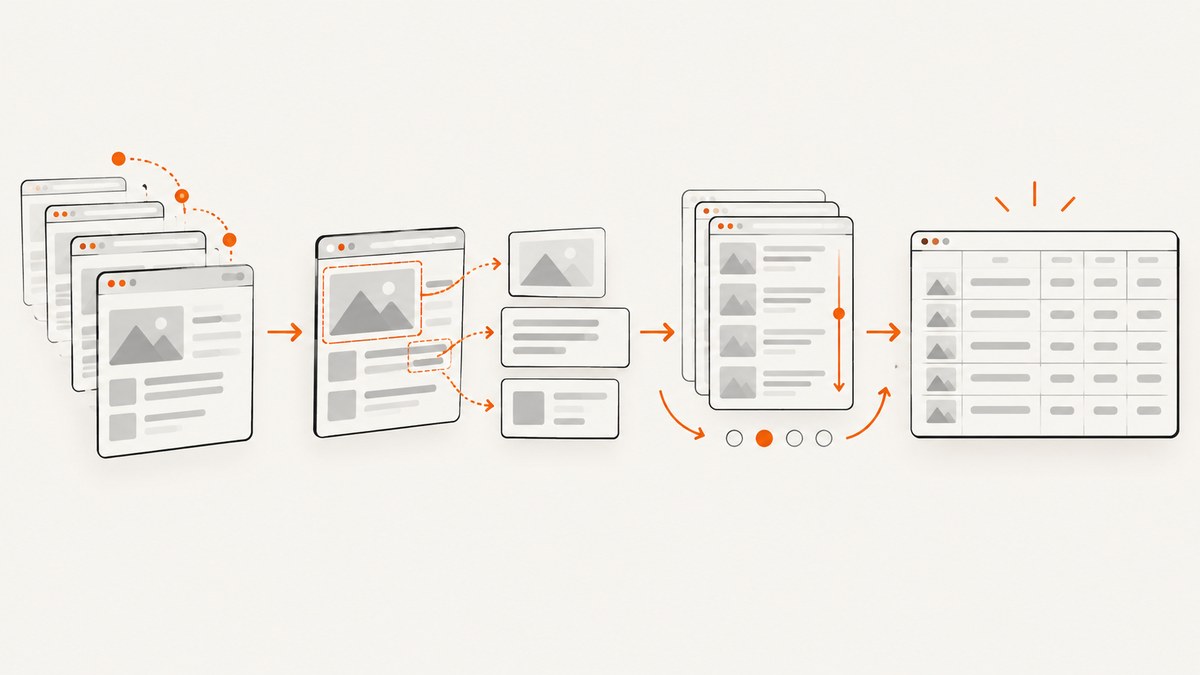
To process every page in a scraped workflow with Playwright Python async, treat the job as a controlled pipeline: discover page URLs or page states, wait for the target content, extract stable fields, advance through pagination or scrolling, record what was processed, and stop only when the site-specific end condition is true. There is no universal “scrape all pages” command because every site exposes different selectors, loading states, pagination controls, and access rules.
This guide shows a complete async design for numbered pagination, “Next” controls, infinite scrolling, known URL lists, retries, bounded concurrency, duplicate prevention, and failure reporting. The selectors and readiness checks are examples. Replace them with signals from the site you are allowed to access.
1. Define what “all pages” means
“All pages” can refer to three different things:
- Paginated result states: page 1, page 2, page 3, and so on.
- Infinite-scroll batches: one URL whose list grows as you scroll.
- Detail URLs: a listing produces links, and each link must be opened and processed.
Write down the records and fields you need before writing selectors. For example, a product record might contain a detail URL, title, price, and availability. Also define the end condition: a disabled next button, no next link, an end marker, or no increase in the number of loaded records after a bounded wait.
2. Install Playwright and create an async browser
python -m pip install playwright
playwright install chromium
Playwright’s Python API supports asynchronous browser, context, and page operations. A browser context can contain multiple pages, which is useful when processing independent detail URLs. See the official Pages documentation for the async API and multiple-page model.
import asyncio
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as pw:
        browser = await pw.chromium.launch(headless=True)
        context = await browser.new_context()
        page = await context.new_page()
        await page.goto("https://example.com", wait_until="domcontentloaded")
        print(await page.title())
        await browser.close()

if __name__ == "__main__":
    asyncio.run(main())
domcontentloaded only means that the initial document was parsed. Modern applications often fetch and render records afterward. Always add a condition for the content your extractor needs.
3. Wait for the application, not just the load event
A reliable scraper waits for a meaningful signal such as a result card becoming visible, a loading indicator disappearing, a result count reaching an expected value, or an application-specific end marker. The navigation documentation explains why a navigation event alone does not prove that application data is ready.
from playwright.async_api import TimeoutError as PlaywrightTimeoutError

async def wait_for_results(page):
    # Replace these selectors with signals from the target site.
    await page.locator("[data-testid='result-card']").first.wait_for(
        state="visible", timeout=15_000
    )
    await page.locator("[data-testid='loading']").wait_for(
        state="hidden", timeout=15_000
    )
If a page can legitimately contain zero records, wait for either a card or an explicit empty-state element. Do not use an arbitrary sleep as your only readiness check.
4. Use stable locators and extract the current batch
Playwright recommends locators based on user-facing roles, labels, text, or explicit test IDs. These are generally less coupled to incidental DOM nesting than deep CSS or XPath expressions. The official locator guide describes this approach.
async def extract_current_records(page):
    cards = page.locator("[data-testid='result-card']")
    records = []

    count = await cards.count()
    for index in range(count):
        card = cards.nth(index)
        link = card.get_by_role("link").first
        records.append({
            "title": (await card.locator("[data-testid='title']").inner_text()).strip(),
            "url": await link.get_attribute("href"),
            "price": (await card.locator("[data-testid='price']").inner_text()).strip(),
        })
    return records
locator.all() deserves special care. It returns locators for elements present immediately; it does not wait for a changing list to finish. The API reference warns that locator.all() can produce unpredictable results when the list changes dynamically. Wait for your site-specific completion condition first, then read the matches.
5. Process numbered pagination
For a traditional listing, process one result state at a time. Track visited URLs or page identifiers so a broken “Next” link cannot create an endless loop.
import asyncio
from urllib.parse import urljoin
from playwright.async_api import async_playwright, TimeoutError as PlaywrightTimeoutError

START_URL = "https://example.com/catalog"

async def wait_for_listing(page):
    cards = page.locator("[data-testid='result-card']")
    empty = page.locator("[data-testid='empty-state']")
    await cards.first.or_(empty).wait_for(state="visible", timeout=15_000)

async def extract_listing(page):
    cards = page.locator("[data-testid='result-card']")
    output = []
    for i in range(await cards.count()):
        card = cards.nth(i)
        href = await card.get_by_role("link").first.get_attribute("href")
        output.append({
            "title": (await card.locator("[data-testid='title']").inner_text()).strip(),
            "url": urljoin(page.url, href),
        })
    return output

async def process_paginated_listing(page, start_url, max_pages=500):
    records = []
    visited_states = set()
    await page.goto(start_url, wait_until="domcontentloaded")

    for _ in range(max_pages):
        state = page.url
        if state in visited_states:
            break
        visited_states.add(state)

        await wait_for_listing(page)
        records.extend(await extract_listing(page))

        next_link = page.get_by_role("link", name="Next")
        next_button = page.get_by_role("button", name="Next")
        if await next_link.count():
            if await next_link.is_disabled():
                break
            await next_link.click()
        elif await next_button.count():
            if await next_button.is_disabled():
                break
            await next_button.click()
        else:
            break

        await page.wait_for_url(lambda url: str(url) != state, timeout=15_000)

    return records

async def main():
    async with async_playwright() as pw:
        browser = await pw.chromium.launch()
        context = await browser.new_context()
        page = await context.new_page()
        try:
            records = await process_paginated_listing(page, START_URL)
            print(f"Collected {len(records)} listing records")
        finally:
            await browser.close()

asyncio.run(main())
Some sites update results without changing the URL. In that case, replace wait_for_url with a condition such as a changed page number, changed first-card URL, or a loading indicator that becomes hidden.
6. Handle infinite scrolling
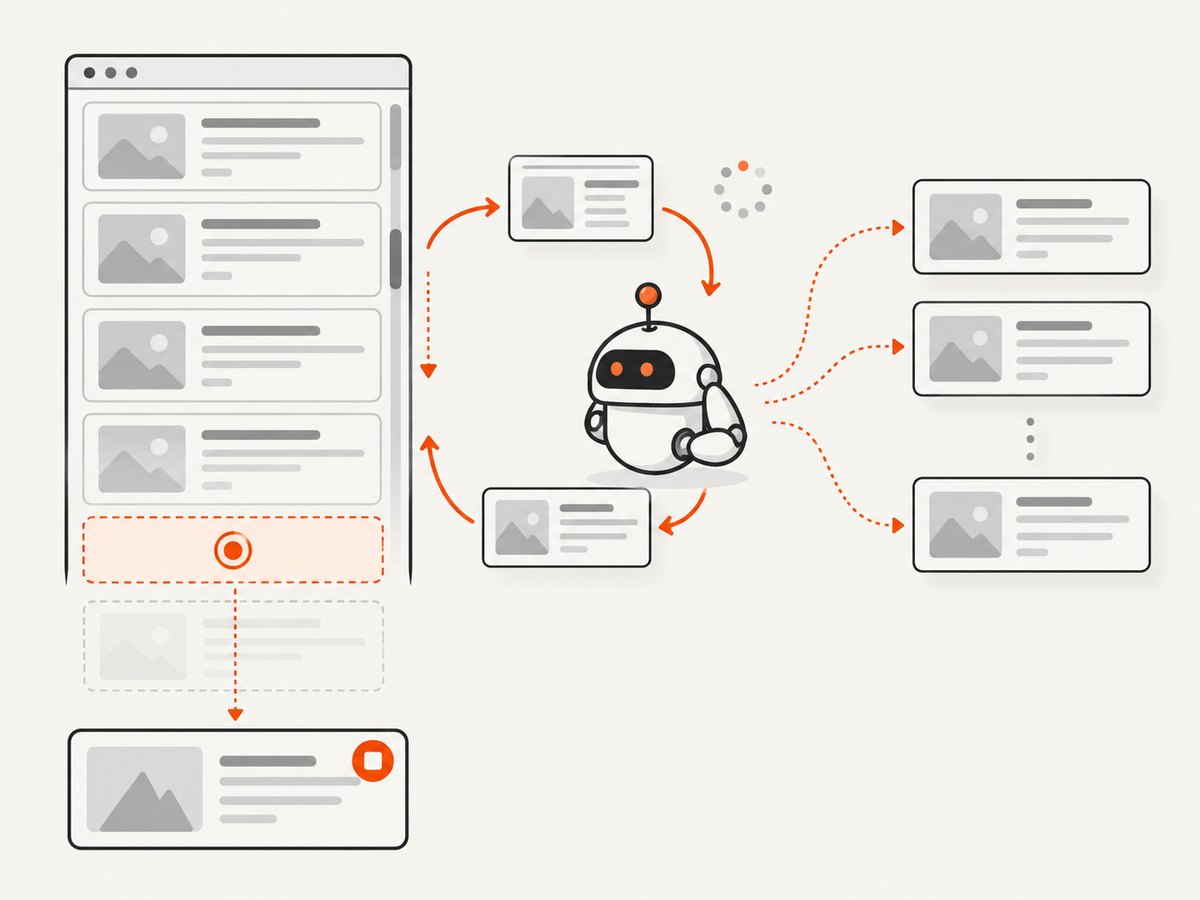
Infinite lists need a loop that performs four actions: measure the current list, scroll a meaningful element or the page, wait for new content, and test the end condition. Playwright documents scrolling actions in its Actions guide.
async def process_infinite_list(page, url, max_rounds=200):
    await page.goto(url, wait_until="domcontentloaded")
    cards = page.locator("[data-testid='result-card']")
    end_marker = page.locator("[data-testid='end-of-results']")
    all_records = []
    seen_urls = set()

    for round_number in range(max_rounds):
        await cards.first.wait_for(state="visible", timeout=15_000)
        before = await cards.count()

        for index in range(before):
            card = cards.nth(index)
            href = await card.get_by_role("link").first.get_attribute("href")
            absolute_url = urljoin(page.url, href)
            if absolute_url in seen_urls:
                continue
            seen_urls.add(absolute_url)
            all_records.append({
                "url": absolute_url,
                "title": (await card.locator("[data-testid='title']").inner_text()).strip(),
            })

        if await end_marker.count() and await end_marker.is_visible():
            break

        await cards.last.scroll_into_view_if_needed()
        try:
            await page.wait_for_function(
                "([selector, oldCount]) => document.querySelectorAll(selector).length > oldCount",
                ["[data-testid='result-card']", before],
                timeout=10_000,
            )
        except PlaywrightTimeoutError:
            after = await cards.count()
            if after <= before:
                break

    return all_records
The termination logic is deliberately defensive. A site may stop loading because the end has been reached, because a request failed, or because a bot check appeared. Record which condition occurred so operators can distinguish a complete collection from a partial one.
7. Process discovered detail URLs with bounded concurrency
Do not open every discovered URL at once. Use a small, configurable worker pool. The official documentation establishes that contexts can host multiple pages, but it does not define a universal safe concurrency number. Choose a conservative bound for the target site and machine, then observe timeouts and resource use.
import asyncio
from playwright.async_api import async_playwright, TimeoutError as PlaywrightTimeoutError

async def scrape_detail(context, url, semaphore, attempts=3):
    async with semaphore:
        page = await context.new_page()
        try:
            for attempt in range(attempts):
                try:
                    await page.goto(url, wait_until="domcontentloaded", timeout=30_000)
                    await page.locator("[data-testid='detail-title']").wait_for(
                        state="visible", timeout=15_000
                    )
                    return {
                        "url": url,
                        "title": (await page.locator("[data-testid='detail-title']").inner_text()).strip(),
                    }
                except (PlaywrightTimeoutError, Exception) as exc:
                    if attempt == attempts - 1:
                        return {"url": url, "error": type(exc).__name__}
                    await asyncio.sleep(2 ** attempt)
        finally:
            await page.close()

async def process_details(context, urls, concurrency=4):
    semaphore = asyncio.Semaphore(concurrency)
    tasks = [scrape_detail(context, url, semaphore) for url in urls]
    return await asyncio.gather(*tasks)
In production, catch specific exceptions where possible, classify HTTP or application errors separately, and persist each result as it completes. A process restart should not force you to repeat successful pages.
8. Add deduplication, checkpoints, and failure reporting
- Normalize absolute URLs and remove tracking parameters when that is safe for the target site.
- Keep a set of visited page states and detail URLs.
- Write successful records incrementally to JSON Lines, a database, or another durable store.
- Write failures with URL, stage, exception type, attempt count, and timestamp.
- Use a maximum page or scroll count as a circuit breaker.
- Separate “no records found” from “page failed before extraction.”
For repeatable jobs, store a run identifier and configuration such as start URL, selectors, concurrency, and timeout values alongside the output.
9. Configuration choices and edge cases
| Concern | Recommended approach |
|---|---|
| Readiness | Wait for a record, empty state, loading completion, or application state that proves extraction can begin. |
| Selectors | Prefer role, label, text, or test ID locators; avoid brittle DOM paths. |
| Pagination | Use the site’s real next control or URL scheme. Track visited states. |
| Infinite scroll | Scroll a relevant element, wait for a measurable increase, and stop on an end marker or repeated no-growth. |
| Timeouts | Set navigation and selector timeouts separately so slow content is diagnosable. |
| Concurrency | Use a bounded semaphore and lower it when the site or machine shows pressure. |
| Sessions | Use a context for cookies, headers, locale, timezone, and authentication state when permitted. |
| Popups | Register popup handlers before the action that opens a new page, then process the returned page explicitly. |
| Empty pages | Model empty state as a valid outcome when the site uses it; do not wait forever for a card. |
Browser automation does not override a site’s access controls or permission requirements. Follow the target site’s terms, robots guidance where applicable, authentication rules, and privacy obligations.
10. Troubleshooting common failures
Only the first batch is returned
Cause: extraction ran before the list finished rendering, or locator.all() was called while the list was changing. Fix: wait for a site-specific readiness condition and verify that the card count stops increasing before reading records.
The script hangs after navigation
Cause: the page keeps network connections open, so a broad network-idle assumption never becomes true. Fix: wait for the actual record or empty-state locator and apply an explicit timeout.
Pagination repeats the same page
Cause: the control changes content without changing the URL, or the click was accepted before the state changed. Fix: compare a page number, first-record identifier, or card count; stop when that measurable state does not change.
Infinite scroll stops early
Cause: the scroll target is wrong, the site needs a longer application wait, or a bot check replaced the list. Fix: scroll the list’s sentinel or last card, inspect the rendered state, wait for a count increase, and classify bot-check pages separately.
Selectors fail after a redesign
Cause: selectors depended on incidental classes or nesting. Fix: use roles, labels, visible text, or stable test IDs and keep selectors in configuration.
One bad URL aborts the run
Cause: an exception escaped from a gather task. Fix: catch per-URL failures, return structured error records, and continue while preserving a failure report.
11. Performance, reliability, and cost notes
Measure a defined workload rather than assuming a universal speedup. Useful measurements include pages discovered, records extracted, successful and failed URLs, median and worst-case page time, retries, browser memory, and output throughput. Compare sequential and bounded-concurrent runs under the same selectors, network, machine, and date.
Concurrency improves throughput for independent URLs but increases browser memory, network demand, and coordination complexity. Increase it gradually. Reuse one browser and context where session settings are shared, but create and close pages per detail URL to avoid state leakage.
Reliability comes from explicit state: readiness checks, bounded retries with backoff, deduplication, checkpoints, circuit breakers, and separate failure accounting. A successful process exit is not proof that every page was collected; report completeness from your counters and end condition.
12. Or skip the browser setup
If your goal is a clean image or PDF of each URL rather than custom DOM extraction, ScreenshotNeo provides a single screenshot API request. It accepts options for full-page capture, lazy images, element selectors, device presets, dark mode, custom CSS and JavaScript, waits, cookies, headers, blocking, resizing, PDFs, caching, signed links, async jobs, and bulk capture. See the ScreenshotNeo API documentation for the request parameters.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Before capture, ScreenshotNeo accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server exposes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000 shots.
Create a free ScreenshotNeo account to start with 1,000 screenshots a month and no card.
13. Short FAQ
Should I use one page per result?
For independent detail URLs, separate pages make cleanup and failure isolation clearer. Limit how many are active with a semaphore.
Is networkidle always the best wait condition?
No. Long-lived analytics, chat, or streaming requests can prevent network idle. A content-specific locator or application-state check is usually more meaningful.
How do I know an infinite list is complete?
Use the site’s end marker when available. Otherwise require repeated no-growth after a defined wait and enforce a maximum scroll count, then record that termination reason.
Can Playwright process pages that require login?
Yes, when you are authorized. Create a context with the required storage state, cookies, or headers and keep authentication data secure.
What should I save for debugging?
Save the URL, page state, attempt number, exception type, timeout stage, and a screenshot or HTML snapshot when policy permits. These details show whether the failure occurred during navigation, readiness, extraction, or advancement.


