Real-Time Product Data for AI Agents
Build a reliable product feed for AI agents with stable IDs, fresh prices, explicit availability, and incremental updates.
Direct answer: Make your product catalog available to AI agents through a structured feed and an update API. Publish a complete snapshot at least daily, then send incremental product, inventory, price, and promotion changes whenever commercial state changes. Every purchasable product or variant needs a stable identifier, canonical URLs, current price, currency, and explicit availability. This combination gives an agent enough reliable context to recommend the right item without guessing.
OpenAI describes product feeds as structured catalog data that helps ChatGPT surface products with accurate pricing, availability, and seller context. The Agentic Commerce Protocol (ACP) is an open standard for connecting merchants and ChatGPT users. Access to product-feed onboarding and Instant Checkout is approval-dependent, so publishing a feed does not automatically enable purchasing inside ChatGPT.
1. What real-time product data contains
A useful feed has two layers:
- Catalog identity: the item ID, title, description, brand, seller, product URL, image URL, and variant relationships.
- Offer state: price, currency, availability, promotions, shipping, returns, and fulfillment details.
The minimum contract for each item is:
| Field | Purpose | Implementation rule |
|---|---|---|
item_id |
Stable key for retrieval and updates | Never reuse it for a different product or variant |
title |
Human-readable product name | Use a factual, specific name |
description |
Product facts | Avoid claims that cannot be supported by your source system |
url |
Canonical product page | Point to the purchasable item or selected variant |
brand |
Brand context | Use the catalog’s canonical spelling |
seller_name |
Seller context | Identify the merchant responsible for the offer |
image_url |
Product media | Serve a stable, accessible image URL |
availability |
Stock state | Use in_stock, out_of_stock, pre_order, backorder, or unknown |
price |
Current payable amount | Update it when a sale begins or ends |
Add shipping methods, return policy, review data, promotions, and fulfillment options when your source systems can provide them accurately. Richer attributes can improve relevance and trust, but incorrect optional data is worse than omitting it.
2. Choose the source of truth
Start with the system that owns each fact rather than copying data manually into a spreadsheet. Common sources include a product information manager (PIM), commerce platform, pricing service, warehouse system, and promotion service.
- Define which system owns identity, content, price, inventory, and fulfillment.
- Join records using one immutable product or variant ID.
- Resolve conflicts before publishing. For example, inventory should come from the service that reserves stock, not a delayed analytics database.
- Record the source timestamp for every update so stale data can be detected.
Represent each purchasable variant separately when price, stock, image, or URL differs. Do not collapse size, color, regional, or seller variants into one row if an agent could recommend or sell them independently.
3. Feed architecture: snapshot plus incremental updates
The practical operating model is a complete snapshot plus changes during the day:
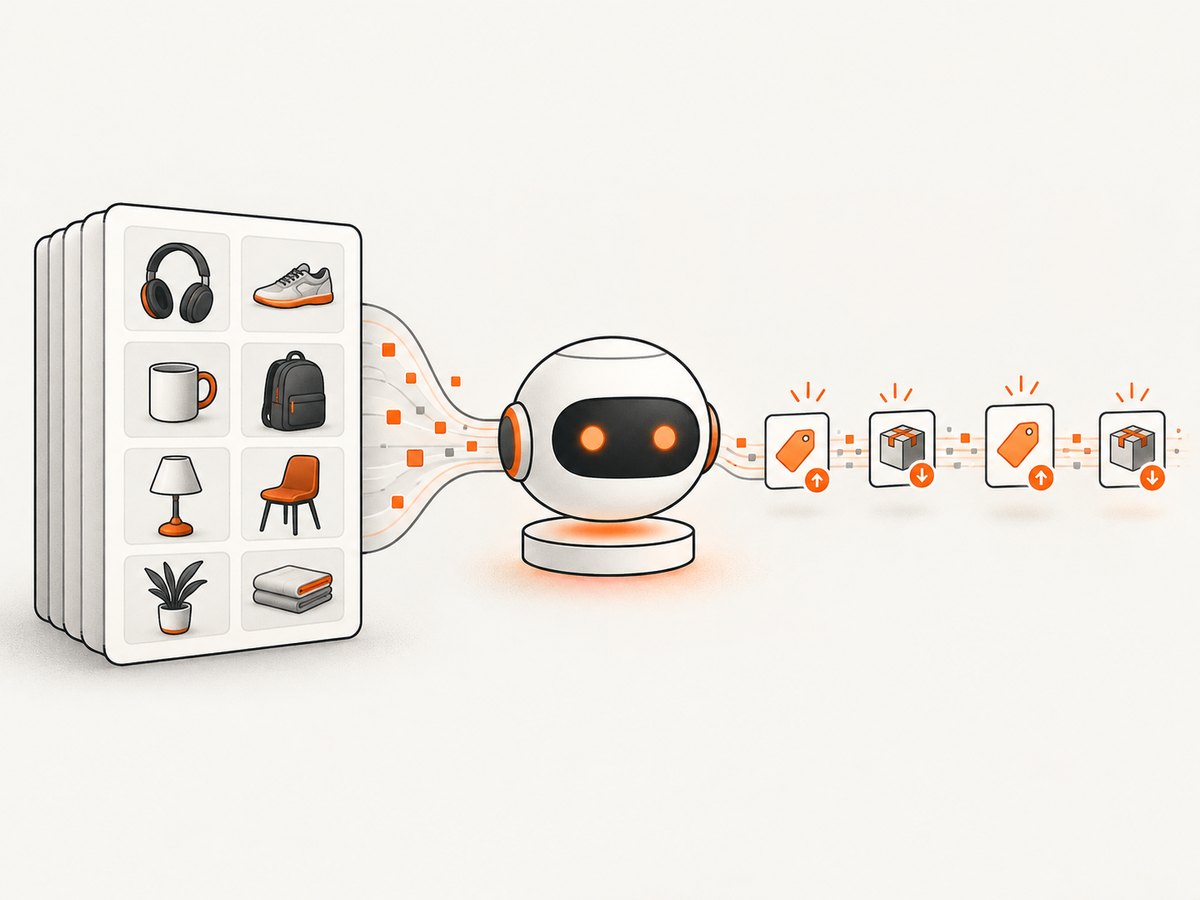
- Snapshot: generate the entire CSV or JSON catalog once a day. It establishes completeness and gives you a recovery path after missed updates.
- Incremental API updates: send product and promotion upserts whenever price, inventory, content, or a promotion changes.
- Reconciliation: compare the source catalog with accepted records and investigate rejected rows, missing IDs, and stale timestamps.
Omitted products in a partial update remain unchanged, so an update request should include every field that actually changed and use the stable ID used by the original snapshot. Make updates idempotent: retrying the same event should produce the same final state.
4. A minimal JSON feed
Here is a compact record format you can generate from your catalog service:
{
  "item_id": "shoe-421-blue-42",
  "title": "Trail Runner Shoes, Blue, EU 42",
  "description": "Water-resistant trail running shoe with a lugged outsole.",
  "url": "https://shop.example.com/shoes/trail-runner?size=42&color=blue",
  "brand": "Example Athletics",
  "seller_name": "Example Athletics Store",
  "image_url": "https://cdn.example.com/images/shoe-421-blue-42.jpg",
  "availability": "in_stock",
  "price": {
    "amount": "129.00",
    "currency": "USD"
  }
}
Keep prices numeric in your internal model and serialize them in the exact representation required by the receiving schema. Include currency explicitly. A formatted string such as “$129.00” is not a substitute for amount plus currency.
5. CSV generation with Python
A daily export can be produced from a list of normalized catalog records. The example validates required fields before writing the file.
import csv
from pathlib import Path

REQUIRED = [
    "item_id", "title", "description", "url", "brand",
    "seller_name", "image_url", "availability", "price", "currency"
]
VALID_AVAILABILITY = {
    "in_stock", "out_of_stock", "pre_order", "backorder", "unknown"
}

products = load_products_from_your_catalog()  # return dictionaries

output = Path("products.csv")
with output.open("w", newline="", encoding="utf-8") as handle:
    writer = csv.DictWriter(handle, fieldnames=REQUIRED)
    writer.writeheader()
    for product in products:
        missing = [key for key in REQUIRED if not product.get(key)]
        if missing:
            raise ValueError(f"{product.get('item_id', '')}: missing {missing}")
        if product["availability"] not in VALID_AVAILABILITY:
            raise ValueError(f"Invalid availability: {product['availability']}")
        writer.writerow({key: product[key] for key in REQUIRED})

print(f"Wrote {output} with {len(products)} products")
Run this export after your source systems have committed their daily changes. Store the generated file and a checksum so you can prove which snapshot was published.
6. Incremental updates with Node.js
Your update worker should consume price and inventory events, normalize them, and upsert by stable ID. The endpoint and authentication details depend on the approved integration you receive; the important behavior is the payload shape and retry model.
const event = {
  item_id: "shoe-421-blue-42",
  price: { amount: "119.00", currency: "USD" },
  availability: "in_stock"
};

async function sendUpdate(update) {
  const response = await fetch(process.env.PRODUCT_UPDATE_URL, {
    method: "POST",
    headers: {
      "Content-Type": "application/json",
      "Authorization": `Bearer ${process.env.PRODUCT_FEED_TOKEN}`,
      "Idempotency-Key": `catalog-${update.item_id}-${update.price.amount}-${update.availability}`
    },
    body: JSON.stringify(update)
  });

  if (!response.ok) {
    const body = await response.text();
    throw new Error(`Update rejected (${response.status}): ${body}`);
  }
  return response.json();
}

sendUpdate(event).catch(error => {
  console.error(error);
  process.exitCode = 1;
});
Use a durable queue for events, exponential backoff for transient failures, and a dead-letter queue for records that need human correction. Do not silently discard rejected updates.
7. Delivery choices and when to use each
| Approach | Strength | Risk | Best use |
|---|---|---|---|
| Hosted CSV or JSON URL | Simple recurring retrieval | Freshness depends on retrieval interval | Stable catalogs and daily snapshots |
| SFTP or file upload | Easy batch ownership and audit trail | Changes wait for the next file | Large catalogs with scheduled publishing |
| API upserts | Fast propagation of price and stock changes | Requires authentication, retries, and idempotency | Inventory, pricing, and promotion events |
| Snapshot plus API | Freshness and recovery together | Two pipelines to operate | Most production catalogs |
8. Freshness, reliability, and performance
Freshness rules
- Send an availability update whenever stock changes from available to unavailable or back.
- Send price updates at the moment a sale starts and ends, including scheduled promotions.
- Refresh descriptions, images, and URLs when the canonical product page changes.
- Track the age of the newest accepted update per item and alert on stale records.
Reliability controls
- Use immutable IDs and idempotency keys.
- Persist every outbound payload, response, retry, and rejection reason.
- Keep the last known good snapshot so a failed deployment cannot publish an empty catalog.
- Reconcile counts and IDs after each batch.
- Test transitions such as in-stock to out-of-stock, price reduction, promotion expiry, and deleted variants.
Performance controls
Partition large exports into predictable batches, stream CSV generation instead of holding the whole catalog in memory, and process independent update events concurrently within the receiving service’s limits. Prioritize inventory and price events over descriptive edits when the queue is delayed. Cache source lookups carefully; never let a stale cache overwrite a newer event.
9. Edge cases developers miss
- Variants: give every purchasable combination its own ID when its offer differs.
- Backorders and preorders: use the explicit state instead of pretending the item is in stock.
- Unknown inventory: use
unknownwhile your source is unavailable, then repair it; do not retain an old in-stock value indefinitely. - Regional pricing: model the market, currency, tax treatment, and destination rules in the offer layer.
- Promotion windows: schedule both activation and expiry updates.
- Deleted products: define a deliberate removal or deactivation process instead of reusing the ID.
- Canonical URLs: preserve meaningful variant parameters while avoiding tracking parameters that create duplicate pages.
- Images: verify that URLs remain accessible to the receiving system and do not require a browser session.
10. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Rows rejected for missing fields | Mapping omitted a required key | Validate every row before upload and report the item ID with the error |
| Price shown is old | Promotion or price event was not emitted | Publish an update at both promotion start and end; monitor event age |
| Out-of-stock item still appears available | Inventory source is delayed or update failed | Send explicit out_of_stock, retry failures, and alert on stale records |
| Variant links to the wrong page | Variants share a URL or unstable ID | Generate a canonical URL and immutable ID for each purchasable variant |
| Duplicate products appear | Different IDs represent the same offer | Define an identity key and deduplicate before publishing |
| Retries create inconsistent data | Updates are not idempotent or arrive out of order | Use idempotency keys and source event timestamps; reject older events |
| Entire catalog disappears after a bad job | Empty snapshot replaced the last good one | Validate row count and required fields before promoting a snapshot |
| Checkout is unavailable | Partner approval or capability is not enabled | Confirm onboarding and Instant Checkout approval before promising transactions |
11. Cost and operating model
The main costs are feed generation, storage and transfer, event processing, monitoring, and engineering time. A daily snapshot is usually cheaper to reason about, while incremental updates reduce freshness delay and unnecessary transfer. Keep the snapshot as a recovery mechanism even when your API pipeline is reliable.
Measure operational indicators rather than inventing accuracy claims: rejected-row count, update age, price-change propagation time, inventory transition failures, snapshot completeness, retry volume, and time to repair a malformed record.
12. Or skip the browser setup
Product data is structured, but product pages still provide important visual and page-level context. ScreenshotNeo captures a URL with one GET request when you need a current image for an agent workflow, catalog QA job, or review queue.
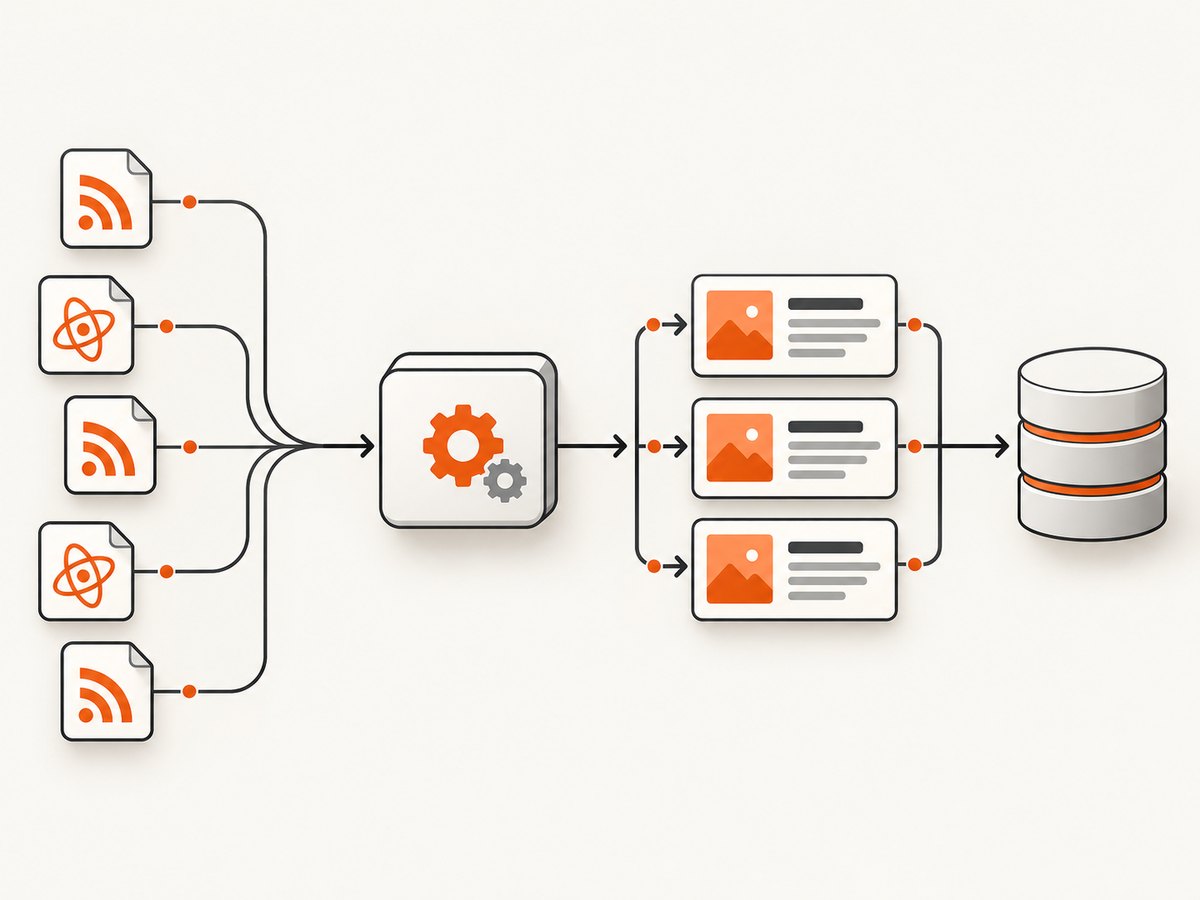
With the API, cookie and consent banners are accepted and 60+ known consent platforms, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing result. ScreenshotNeo also provides an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);It supports full-page and element captures, device presets, custom viewports, retina scale, dark mode, custom CSS and JavaScript, waits, blocking rules, headers, cookies, user agents, authorization, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture, PDFs, HTML-to-image, and a usage API. One thousand screenshots a month are free with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
13. Implementation checklist
- Identify the source of truth for every catalog and offer field.
- Assign an immutable ID to every purchasable item and variant.
- Populate all required fields and validate before delivery.
- Publish a complete snapshot and retain the last known good copy.
- Send API upserts for price, inventory, and promotion changes.
- Make retries idempotent and preserve audit logs.
- Monitor rejected rows, stale timestamps, stock transitions, and promotion windows.
- Confirm partner approval before advertising feed publication or Instant Checkout.
FAQ
Does ChatGPT require a special product-feed language?
No special prose format is required. Use the supported structured feed schema with stable IDs and explicit offer fields, then deliver it through an approved file or hosted-feed method and API workflow.
How often should inventory be updated?
Update whenever inventory changes. A daily snapshot alone can be too slow for fast-moving stock, which is why incremental updates are used during the day.
Can I send only changed fields?
Yes, partial updates can carry changed fields matched by the stable product ID. Keep the full snapshot as the completeness and recovery mechanism.
Should every color and size have a separate row?
Yes when that combination has its own price, availability, image, or destination URL. Agents need a stable identity for the offer they recommend.
Is product-feed onboarding automatic?
No. Product-feed onboarding and Instant Checkout are described as available to approved partners, so confirm your approval and enabled capabilities.


