Reverse Engineering Websites for Web Scraping
Learn how to inspect a website’s data flow, choose an API, parser or browser, and build a respectful scraper without bypassing access controls.
Reverse engineering a website for scraping means observing what an ordinary browser receives and how the page obtains its data. You identify the useful source—an official API, downloadable export, server-rendered HTML, or a browser request—then collect the smallest permitted dataset with conservative request rates.
This is inspection of client-visible behavior, not a method for defeating authentication, CAPTCHAs, bot checks, rate limits or other access controls. The Internet Engineering Task Force states in RFC 9309 that robots.txt rules “are not a form of access authorization.” Read RFC 9309 before treating a crawler rule as part of your workflow.
What reverse engineering a website involves
A useful investigation answers five questions:
- What exact fields do you need, and why?
- Does the site publish an official API, export or dataset?
- Is the data in the initial HTML, embedded JSON, or loaded by later requests?
- What pagination, filters, authentication and rate limits does the permitted interface expose?
- How will you validate results, handle changes and stop when access is denied?
Start with the least fragile source. A documented API is easier to monitor than undocumented page behavior. HTML parsing is appropriate when the needed fields are server-rendered. Browser automation is justified when JavaScript execution, interaction or lazy loading is required.
Permission, robots.txt and responsible collection
Check the target’s current terms, privacy notices and published machine-readable guidance before collecting data. RFC 9309 describes robots.txt as a protocol in which site owners publish crawler rules grouped by user agent; a successfully fetched file’s parseable rules are followed by crawlers implementing the protocol. It does not grant permission, override terms or replace authentication.
Google describes robots.txt mainly as a way to manage crawler traffic. Blocking a URL there does not reliably keep it out of search results; Google recommends controls such as noindex or password protection for that goal. Google’s robots.txt documentation explains the distinction.
MDN warns that robots.txt is publicly accessible and must not be used to hide private information. Malware robots and harvesters may ignore it, so confidential content needs real access controls. MDN’s overview and security guidance provide useful context.
Do not make a blanket claim that scraping is legal or illegal. The answer depends on jurisdiction, data, access method, contract terms and how results are used. For consequential projects, obtain advice specific to your situation. Operationally, minimize collection, avoid sensitive personal data without a clear lawful basis, identify your crawler honestly, keep request rates low and stop when the service denies access.
A repeatable reverse-engineering workflow
1. Define the smallest useful dataset
Write a field list and sample output before opening developer tools. Record whether each field is public, personal, user-generated or sensitive. Decide how many pages and how often you truly need to collect. A narrow scope reduces load and maintenance.
2. Search for an official source
Look for developer documentation, an export button, a sitemap, feeds or a downloadable dataset. Prefer documented authentication and pagination. Save the version or date of the documentation you used so a later change is explainable.
3. Inspect a normal browser session
Open the page normally and use the browser’s Network panel. Reload with the panel open, filter to Fetch/XHR, and inspect requests that appear when you search, paginate or change a filter. Record the request method, URL, query parameters, request body, response content type, pagination fields and any headers that are genuinely required for an ordinary permitted session.
Do not copy session cookies or authorization tokens into a shared script. Never turn inspection into an attempt to bypass a login, challenge or quota.
4. Classify the data delivery
| Observation | Likely approach | What to verify |
|---|---|---|
| Fields are in the response HTML | HTTP client plus HTML parser | Stable selectors, encoding, pagination links |
| A JSON script tag contains the records | Parse the embedded JSON | Schema, escaping, whether it is complete |
| A later request returns JSON | Use the documented endpoint when permitted | Parameters, cursor or page limits, rate policy |
| Content appears only after JavaScript or interaction | Browser automation | Required waits, selectors, lazy loading and failure states |
5. Validate a small sample
Capture a handful of pages across categories, empty results and the final page. Compare extracted values with what a browser displays. Store the source URL, retrieval time, parser version and observed schema. Add checks for missing fields and duplicate records before scaling up.
Inspecting requests with browser tools
In Chromium-based browsers, open DevTools, choose Network, enable “Preserve log,” reload, then perform one action at a time. Select a request and inspect its Headers, Payload and Response tabs. “Copy as cURL” is useful for understanding parameters, but remove personal cookies and temporary tokens before saving or sharing it.
Look for cursor fields such as next, next_cursor or has_more. A page number hidden in a request is not automatically a supported public API; confirm terms and documentation. Watch for retries, redirects, compressed responses and HTTP status changes. A request that succeeds in your browser may depend on a short-lived session or a user-specific response.
DIY browser capture for JavaScript-heavy pages
When content genuinely requires a browser, Playwright provides a repeatable way to load a page, wait for a selector and inspect the rendered DOM. Install it in an isolated project:
npm install playwright
npx playwright install chromium
The following Node.js script saves the rendered HTML after a conservative wait. Replace the URL and selector with values you are allowed to access.
import { chromium } from 'playwright';

const browser = await chromium.launch({ headless: true });
const page = await browser.newPage({
  userAgent: 'ExampleResearchBot/1.0 (+https://example.com/contact)'
});

try {
  await page.goto('https://example.com/catalog', {
    waitUntil: 'domcontentloaded',
    timeout: 30_000
  });
  await page.locator('[data-product]').first().waitFor({ timeout: 10_000 });
  const records = await page.locator('[data-product]').evaluateAll(nodes =>
    nodes.map(node => ({
      name: node.querySelector('.name')?.textContent?.trim() ?? null,
      price: node.querySelector('.price')?.textContent?.trim() ?? null
    }))
  );
  console.log(JSON.stringify(records, null, 2));
} finally {
  await browser.close();
}
Use domcontentloaded when the target data appears quickly. Wait for a specific selector when possible; arbitrary delays are less predictable. For infinite scrolling, scroll in bounded increments, detect whether the number of records increases, and stop after a defined maximum. For pagination, follow the site’s visible next control or documented cursor rather than guessing URL parameters.
Calling a discovered endpoint with cURL, Python and Node.js
If an official or clearly permitted JSON endpoint is available, keep the client simple and honor its documented limits.
curl --fail-with-body --retry 2 \\
  -H 'Accept: application/json' \\
  'https://example.com/api/items?limit=50&cursor=START'
import requests
url = "https://example.com/api/items"
params = {"limit": 50, "cursor": "START"}
r = requests.get(url, params=params, timeout=30)
r.raise_for_status()
data = r.json()
print(data)const params = new URLSearchParams({ limit: '50', cursor: 'START' });
const res = await fetch(`https://example.com/api/items?${params}`);
if (!res.ok) throw new Error(`${res.status} ${await res.text()}`);
const data = await res.json();
console.log(data);Implement cursor pagination from the response, not from assumptions. Bound the number of pages, persist progress, and use exponential backoff only for transient failures. Respect Retry-After when supplied. Keep credentials in environment variables or a secret manager, never in source control or logs.
Parsing static HTML safely
For server-rendered pages, an HTML parser avoids the overhead of a browser. In Python:
import requests
from bs4 import BeautifulSoup

r = requests.get('https://example.com/news', timeout=30,
                 headers={'User-Agent': 'ExampleResearchBot/1.0'})
r.raise_for_status()
soup = BeautifulSoup(r.text, 'html.parser')
rows = []
for card in soup.select('article.card'):
    rows.append({
        'title': card.select_one('h2')?.get_text(' ', strip=True),
        'url': card.select_one('a[href]')['href']
    })
print(rows)
Python does not support optional chaining in ordinary dictionary access; use explicit checks in production:
for card in soup.select('article.card'):
    title_node = card.select_one('h2')
    link_node = card.select_one('a[href]')
    rows.append({
        'title': title_node.get_text(' ', strip=True) if title_node else None,
        'url': link_node.get('href') if link_node else None
    })
Options that affect reliability
- Timeouts: set connection and total time limits. A hung page must not consume a worker forever.
- Retries: retry a small number of network and 5xx failures; do not retry permission errors or repeated 4xx responses.
- Rate: add a bounded delay, cap concurrency and use a queue. More parallelism is not automatically better.
- Idempotency: store completed URLs or cursors so a restart does not duplicate work.
- Validation: check status, content type, required fields and record counts. Save failed responses separately for diagnosis.
- Change detection: alert when selectors disappear, schemas change or empty results suddenly increase.
- Data handling: redact credentials and unnecessary personal data from logs; encrypt stored results where appropriate.
Performance and cost planning
Estimate work as pages multiplied by requests per page, then include retries and browser startup overhead. Reuse a browser context for multiple permitted pages, block resources you do not need only when doing so does not change the data, and prefer an official JSON response over full rendering when it contains the same fields. Cache results with a documented freshness window. Measure your own workload; the research sources establish no universal speed comparison between parsers, APIs and browsers.
Operational cost includes compute, bandwidth, storage, proxy or browser infrastructure, engineering maintenance and the target’s service limits. A scraper that is cheap per request can still be expensive to maintain when undocumented selectors change. Stop collection when the target denies access or a technical control intervenes.
Or skip the browser setup
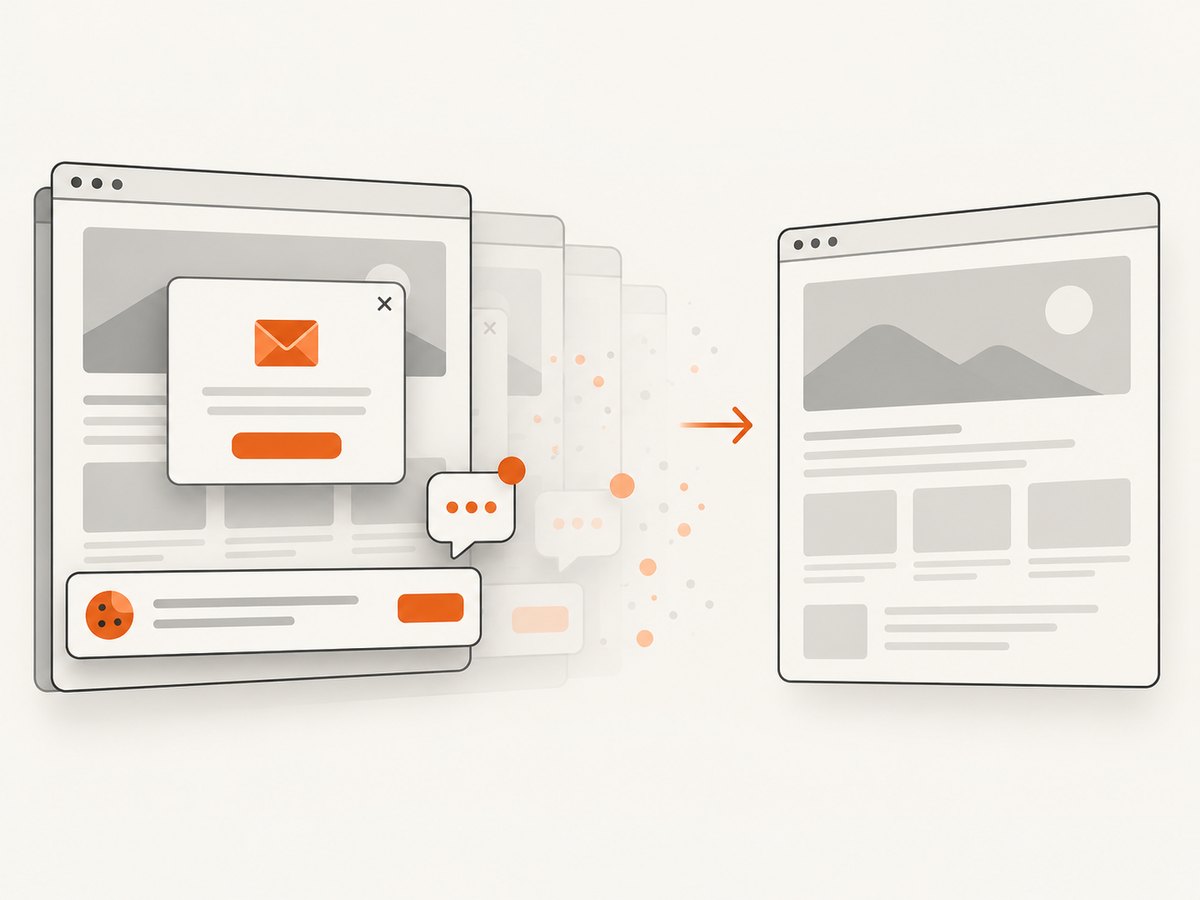
ScreenshotNeo provides a website screenshot API and MCP server. It can capture PNG, JPEG, WebP or PDF with one GET request. Before capture, it accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups and chat widgets; each step can be turned off. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed, and response headers identify the page verdict and billing result.
Use the ScreenshotNeo API documentation for the complete option list, including full-page capture with lazy images, CSS-selector element capture, dark mode, device presets, custom viewports, retina scale, PDF paper sizes and page ranges, custom CSS and JavaScript, clicks, waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, TTL caching, signed links, asynchronous jobs, webhooks, bulk capture and usage reporting.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests; r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90); open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);An MCP server supplies take_screenshot, get_page_info and capture_pdf to Claude, Cursor and other MCP clients, so AI agents can inspect pages without you maintaining browser orchestration. ScreenshotNeo includes 1,000 shots per month free with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| HTML contains no visible records | Data is rendered later | Inspect Fetch/XHR requests or wait for a stable selector in a permitted browser session. |
| JSON endpoint returns 401 or 403 | Authentication or permission is required | Use the documented authorization flow or stop; do not bypass it. |
| Results are empty after several pages | Cursor was not advanced or a filter is invalid | Log the complete response, follow the returned cursor and validate parameters. |
| Playwright times out | Slow load, wrong selector or blocked access | Use a specific wait, inspect the page state, increase the timeout modestly and stop if a challenge appears. |
| Duplicate records | Retries or unstable pagination | Use a stable record key, persist cursors and deduplicate before writing. |
| Parser broke after a redesign | Undocumented markup changed | Prefer a documented source, add schema alerts and update selectors from a fresh inspection. |
| Too many 429 responses | Request rate is too high | Reduce concurrency, honor Retry-After and review the target’s published limits. |
| Robots.txt disallows a path | Crawler rule requests that path not be fetched | Treat it as a signal to honor and investigate another permitted source; it is not authorization or a security boundary. |
Checklist before production
- Document the purpose, fields and minimum collection scope.
- Check the official API, export, terms and current robots.txt.
- Test a small sample and record the observed schema.
- Set timeouts, bounded retries, low concurrency and a clear user agent.
- Persist progress and make reruns idempotent.
- Validate counts, required fields, duplicates and content types.
- Monitor selector and schema changes.
- Stop on access denial, authentication barriers or bot challenges.
- Review privacy, retention and jurisdiction-specific obligations.
FAQ
Is reverse engineering a website the same as hacking it?
No. This guide describes observing responses and browser behavior that you are permitted to access. Defeating authentication, CAPTCHAs, bot checks or technical restrictions is outside the method.
Can I rely on robots.txt as permission?
No. RFC 9309 explicitly says robots.txt rules are not access authorization. They are crawler instructions, and private information requires real security controls.
When should I use a browser instead of requests?
Use a browser when the required data appears only after JavaScript execution or interaction. If the same fields are available in an official API or server response, that simpler source is usually easier to maintain.
How often should a scraper run?
Choose the lowest frequency that satisfies the use case. Base it on how quickly the data changes, the target’s published limits and your storage needs, then monitor failures and adjust conservatively.
What should I do when the site changes?
Keep fixtures from a small validation sample, alert on missing selectors or schema changes, and re-inspect the normal browser flow. Prefer a documented interface when one becomes available.


