11 Web Scraping Best Practices for Reliable Data Collection
Build a reliable, respectful scraper with robots.txt checks, clear identity, modest rates, bounded retries, validation, and observable operations.
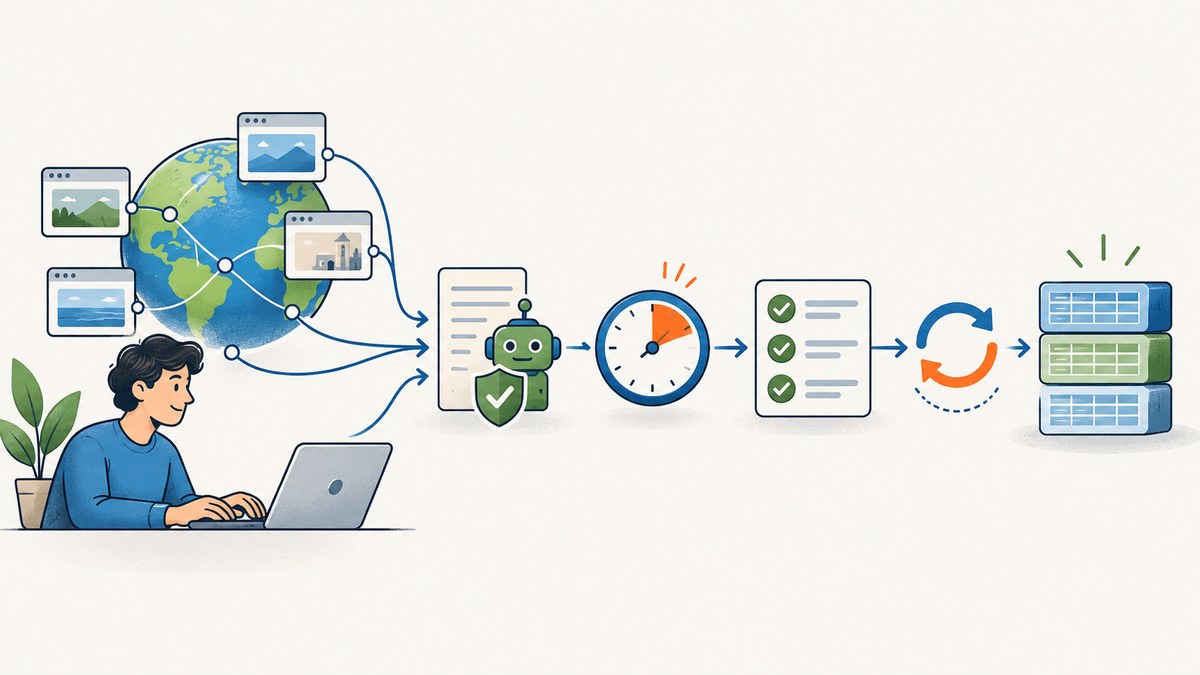
Direct answer: reliable web scraping starts with permission and scope, then combines a clear crawler identity, conservative per-host rates, bounded retries, focused URL discovery, small batches, and strict data validation. Treat robots.txt as crawler guidance rather than authorization, stop when a site signals that you should stop, and record enough metadata to explain every record you collect.
This guide gives you an operational plan, runnable Python code, cURL examples, failure handling, and a production checklist. It is written for public web data collection where you can review the site’s terms, technical controls, and applicable privacy obligations before making requests.
1. Confirm that scraping is the right collection method
Look for an official API, feed, export, or sitemap before writing a page scraper. Compare each option on permission and terms, fields and completeness, freshness, quotas, server impact, operational complexity, and how easily you can validate the output. An API is often easier to maintain, but page scraping may be necessary when the required public fields are not exposed elsewhere.
Define the smallest useful scope before you crawl:
- Which hosts, paths, and page types are in scope?
- Which fields are required, optional, or prohibited?
- How often must data be refreshed?
- What is your retention period and deletion process?
- What evidence will show that a record came from the expected page?
Keep access, security, and privacy reviews separate. A page being publicly reachable does not settle questions about credentials, contractual terms, personal data, or applicable law.
2. Read robots.txt for the exact origin and crawler
Fetch /robots.txt from the exact scheme, host, and port you plan to access. Match your crawler’s product token to the relevant User-agent group and follow parseable Disallow and Allow rules. Google’s explanation of the standard is useful when checking parser behavior (Google’s robots.txt specification guide).
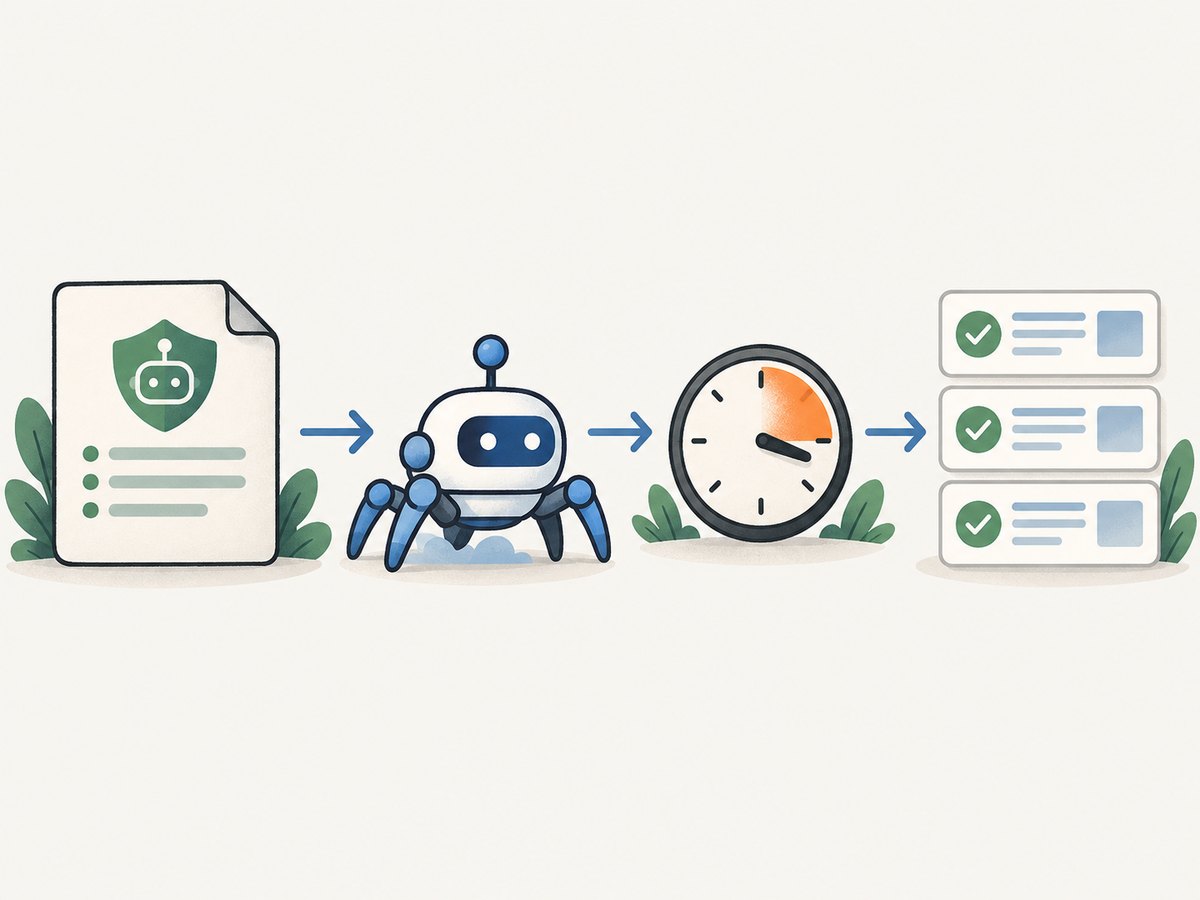
RFC 9309 defines the Robots Exclusion Protocol and states that its rules “are not a form of access authorization.” Read the full RFC 9309 specification, then separately review terms, authentication requirements, technical access controls, and legal obligations. Do not use a disallowed path as a way to discover sensitive locations; robots.txt itself can reveal paths that are not otherwise linked.
from urllib.parse import urlparse
from urllib.robotparser import RobotFileParser


def allowed_by_robots(url: str, user_agent: str) -> bool:
    origin = urlparse(url)
    robots_url = f"{origin.scheme}://{origin.netloc}/robots.txt"
    parser = RobotFileParser(robots_url)
    parser.read()
    return parser.can_fetch(user_agent, url)

ua = "ExampleResearchBot/1.0 (+https://example.org/bot-info)"
print(allowed_by_robots("https://example.com/articles/1", ua))
3. Identify your crawler clearly
Send a stable, descriptive User-Agent that identifies the software and gives an operator a contact or information URL. RFC 9110 §10.1.5 says, “A user agent SHOULD send a User-Agent header field in each request unless specifically configured not to do so.” Avoid pretending to be a browser or another crawler, and avoid needless version detail that increases fingerprinting and latency. See RFC 9110.
HEADERS = {
    "User-Agent": "ExampleResearchBot/1.0 (+https://example.org/bot-info)",
    "Accept": "text/html,application/xhtml+xml"
}
4. Start with a conservative request rate
Rate limits must reflect the host, page weight, crawl window, and any instructions published by the operator. As illustrative guidance, AWS discusses one request every 10–15 seconds for small or medium sites and one to two requests per second for larger sites or sites with explicit crawl permissions. These are examples, not universal safe thresholds. Begin more slowly and reduce load when latency rises, errors increase, or the site asks you to stop.
Use per-host scheduling rather than one global sleep. Add jitter so many workers do not hit a host at the same instant. Limit concurrency and count requests, bytes, status codes, and response time by host.
import random
import time


def wait_between_requests(min_seconds=10, max_seconds=15):
    time.sleep(random.uniform(min_seconds, max_seconds))
5. Handle 429 and 403 responses as control signals
A 429 Too Many Requests response means you should pause and then reassess your rate. Honor Retry-After when present. If 403 Forbidden responses continue, stop the affected crawl instead of increasing traffic or rotating identities. AWS’s ethical web crawler guidance specifically recommends pausing on 429 and considering a stop when 403 responses persist.
import time


def retry_delay(response, attempt):
    retry_after = response.headers.get("Retry-After")
    if retry_after and retry_after.isdigit():
        return min(int(retry_after), 3600)
    return min(60, 2 ** attempt)

if response.status_code == 429:
    time.sleep(retry_delay(response, attempt))
elif response.status_code == 403:
    raise RuntimeError("Persistent access restriction; stop this host")
6. Reduce discovery work with sitemaps and scope rules
Sitemaps provide a focused starting set of URLs and can prevent expensive, duplicate discovery. Parse the sitemap for the content types you need, filter by host and path, and record the sitemap location and retrieval time. AWS recommends using sitemaps to identify important pages and reduce unnecessary work.
Normalize URLs before deduplication: remove fragments, resolve relative links, normalize default ports, and apply only query-parameter rules you understand. Do not discard parameters blindly when they change the content.
7. Crawl in small, resumable batches
Divide a large URL set into batches that can finish within your worker’s timeout and memory budget. Persist a queue with states such as pending, success, retryable, blocked, and failed. AWS recommends smaller batches to distribute load and reduce timeout and resource constraints.
Store a deterministic URL key and an attempt count. If a process exits, resume from persisted state rather than restarting the entire crawl. Keep failed URLs with their last status, error, and timestamp so operators can inspect them.
8. Use bounded retries with visible errors
Retry transient network failures, connection resets, and selected 5xx responses with exponential backoff and jitter. Do not retry malformed URLs, repeated 403 responses, robots-disallowed URLs, authentication failures, or parser errors without a code change. Set both connect and read timeouts.
import requests
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry

session = requests.Session()
retry = Retry(
    total=3,
    connect=2,
    read=2,
    status=2,
    backoff_factor=1,
    status_forcelist=(500, 502, 503, 504),
    allowed_methods=frozenset({"GET"}),
    respect_retry_after_header=True,
)
session.mount("https://", HTTPAdapter(max_retries=retry))

response = session.get(
    "https://example.com/article",
    headers=HEADERS,
    timeout=(10, 60),
)
response.raise_for_status()
9. Validate records, not just HTTP responses
A successful HTTP status only says that bytes arrived. Validate required fields, types, duplicate keys, pagination completion, parsing errors, and timestamps. Compare expected and observed record counts where you have a defensible expectation. Keep the source URL, collection timestamp, parser version, and a content hash or other provenance identifier with each record.
def validate_article(record):
    required = ("url", "title", "collected_at")
    missing = [field for field in required if not record.get(field)]
    if missing:
        return False, f"missing fields: {', '.join(missing)}"
    if not record["url"].startswith("https://"):
        return False, "unexpected URL scheme"
    return True, "ok"

seen = set()
for item in records:
    key = item["url"]
    if key in seen:
        raise ValueError(f"duplicate record: {key}")
    seen.add(key)
10. Recheck selectors and assumptions when pages change
HTML structure, pagination, consent flows, and content rules change. Keep selectors and crawl rules in version control. Emit metrics for empty titles, sudden record-count changes, parse failures, and new content types. Save representative fixtures so parser changes can be reviewed before deployment. Record the collection time and source version because a later fetch may not reproduce the same page.
11. Protect operators, sources, and collected data
Limit concurrency, cap response sizes, and reject unexpected content types before parsing. Store credentials outside source code and redact authorization headers from logs. Treat downloaded HTML as untrusted input: parse it as data, disable unsafe execution, and sanitize anything displayed in an internal dashboard. Minimize personal data, define retention, and restrict access to raw responses.
DIY reference crawler in Python
The following compact example combines identity, robots checking, a per-request delay, bounded retries, and a visible result record. Extend it with persistent queues and validation before using it for a large job.
import random
import time
from datetime import datetime, timezone
from urllib.parse import urlparse
from urllib.robotparser import RobotFileParser

import requests

USER_AGENT = "ExampleResearchBot/1.0 (+https://example.org/bot-info)"
HEADERS = {"User-Agent": USER_AGENT, "Accept": "text/html"}


def can_fetch(url):
    p = urlparse(url)
    robots = RobotFileParser(f"{p.scheme}://{p.netloc}/robots.txt")
    robots.read()
    return robots.can_fetch(USER_AGENT, url)


def fetch(url, attempts=3):
    if not can_fetch(url):
        return {"url": url, "status": "robots_disallowed"}
    for attempt in range(attempts):
        try:
            response = requests.get(url, headers=HEADERS, timeout=(10, 60))
            if response.status_code == 429:
                delay = response.headers.get("Retry-After")
                time.sleep(int(delay) if delay and delay.isdigit() else 30)
                continue
            if response.status_code == 403:
                return {"url": url, "status": "forbidden", "code": 403}
            response.raise_for_status()
            return {
                "url": url,
                "status": "success",
                "code": response.status_code,
                "html": response.text,
                "collected_at": datetime.now(timezone.utc).isoformat(),
            }
        except (requests.Timeout, requests.ConnectionError) as exc:
            if attempt == attempts - 1:
                return {"url": url, "status": "failed", "error": str(exc)}
            time.sleep(min(60, 2 ** attempt) + random.random())
    return {"url": url, "status": "failed"}

result = fetch("https://example.com/")
print(result["status"], result.get("code"))
Or skip the browser setup
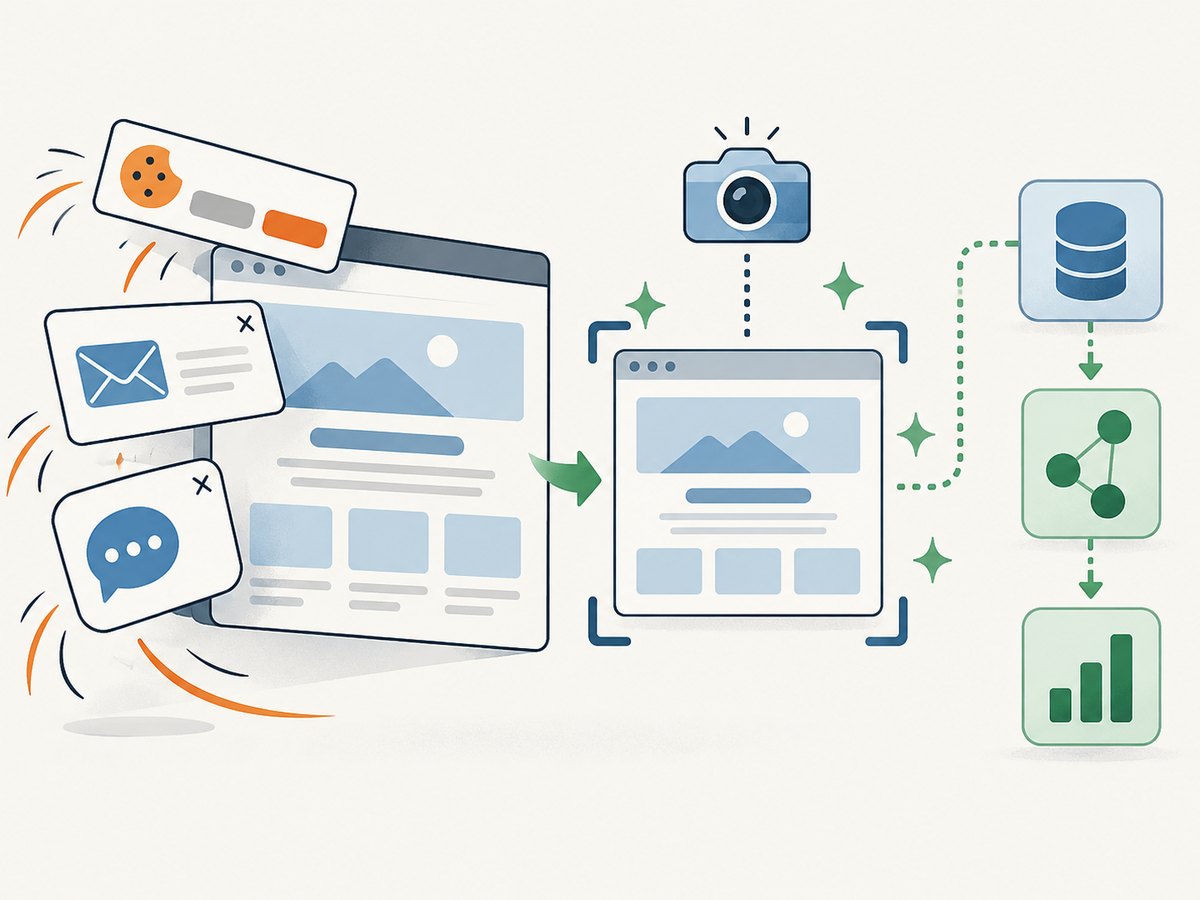
When your workflow needs rendered pages or image evidence, ScreenshotNeo provides a website screenshot API and MCP server. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and responses identify the result with X-Page-Verdict and X-Billed headers. An MCP server lets Claude, Cursor, and other MCP clients use take_screenshot, get_page_info, and capture_pdf.
See the ScreenshotNeo documentation for all options. The same endpoint supports full-page captures with lazy images, CSS-selector element shots, dark mode, device presets or custom viewports, retina scale, PDF output, custom CSS and JavaScript, clicks, waits, blocked resources, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, TTL caching, signed links, async webhooks, bulk capture, usage data, and an OpenAPI specification.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com/ \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://example.com/"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://example.com/'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));
There is a free tier of 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account.
Performance, reliability, and cost planning
- Performance: prioritize URLs with a sitemap, bound concurrency per host, reuse HTTP connections, and avoid downloading assets you do not parse.
- Reliability: persist queue state, make jobs resumable, separate retryable from permanent failures, and alert on validation drift.
- Cost: estimate requests, response bytes, parsing time, storage, and reprocessing. Batching reduces wasted work; caching can prevent duplicate fetches when freshness permits.
- Operations: keep dashboards for status codes, latency, queue age, parser failures, duplicate rate, and records per batch.
Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Many 429 responses | Rate or concurrency is too high | Pause, honor Retry-After, lower per-host rate and concurrency |
| Persistent 403 responses | Access restriction or changed policy | Stop the host crawl; review terms and request permission if appropriate |
| Empty fields with 200 status | Client-rendered content or changed selectors | Inspect the response, use an approved rendered capture path, and update fixtures |
| Duplicate records | URL variants, pagination loops, or retries without idempotency | Normalize URLs, persist page state, and enforce a unique key |
| Jobs never finish | Unbounded retries or oversized batches | Cap attempts, classify failures, and split the queue into smaller batches |
| Parser crashes | Unexpected content type or malformed input | Check headers and size limits, catch parse errors, and quarantine the response |
FAQ
Does robots.txt grant permission to scrape?
No. RFC 9309 describes it as crawler guidance and explicitly says it is not access authorization. Review terms, controls, credentials, and applicable obligations separately.
What User-Agent should a scraper send?
Use a stable product name and a contact or information URL. Do not impersonate another crawler or browser.
How many requests per second are safe?
There is no universal number. Start conservatively, use the host’s instructions, watch responses and latency, and reduce load when the site shows strain. AWS’s published rates are illustrative examples.
Should every failed request be retried?
No. Retry transient network and selected server errors with a cap. Stop or quarantine robots violations, persistent 403 responses, malformed URLs, and parser failures.
How do I prove a dataset is reliable?
Keep provenance, timestamps, parser versions, validation results, duplicate checks, and a record of failed or skipped URLs. Recheck assumptions when the source changes.


