Browser Automation for Fintech
Learn how to automate fintech browser workflows safely with Playwright, isolated accounts, protected session state, and auditable actions.
Puppeteer, Playwright, Selenium and headless Chrome, and what they take to run well.
Learn how to automate fintech browser workflows safely with Playwright, isolated accounts, protected session state, and auditable actions.
Deploy Playwright MCP locally or over HTTP, choose the right browser connection, protect session state, and troubleshoot reliable automation servers.
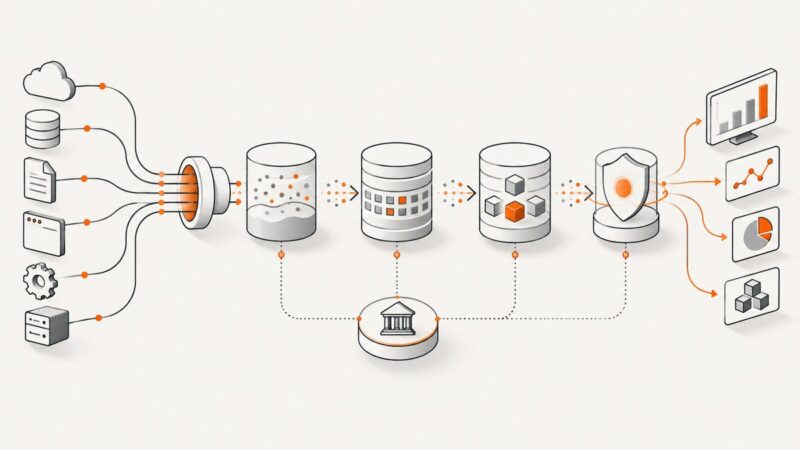
Enterprise extraction needs durable ingestion, raw-to-curated data layers, quality controls, governance, and reliable interfaces—not only a scraper.
Design browser automation sandboxes that isolate browser state, processes, files, and networks with practical Playwright and Docker patterns.
Chrome DevTools Protocol enables browser control and debugging, but it is not a stealth feature. Learn what sites can detect and how to automate safely.
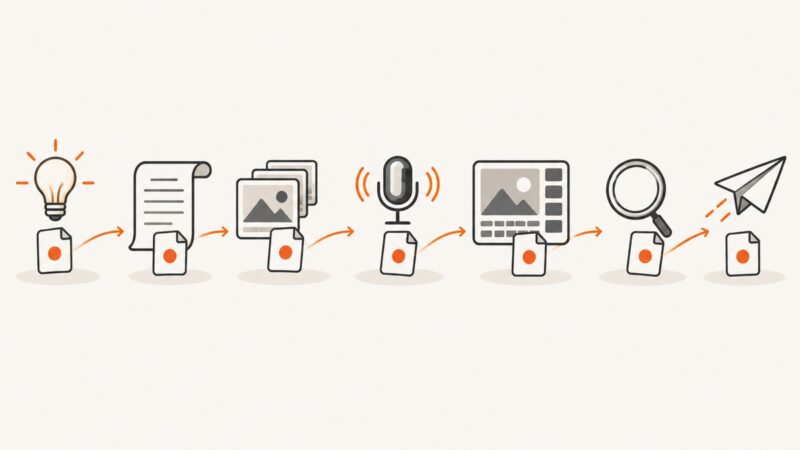
Build a reliable pipeline that captures website walkthroughs, personalizes video, renders asynchronously, and delivers reviewed outputs at scale.
A practical guide to identifying CAPTCHA providers, using authorized test flows, waiting for completion, and securing cloud browser sessions.
Learn how cloud browsers work, connect Playwright or Puppeteer, scale sessions, control costs, and choose between managed and self-hosted setups.
Use webhooks when event-driven updates beat repeated API checks. Learn how to choose, secure, process, and troubleshoot them in reliable automation workflows.
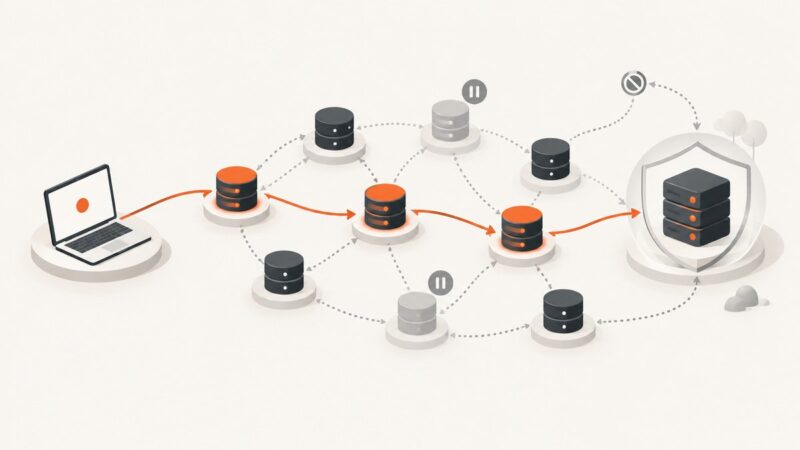
Design extraction pipelines that recover from transient errors, corrupt workers, lost regions, duplicate writes, and CDC interruptions without losing data.
Learn how websites distinguish browsers, crawlers, and automation using headers, Client Hints, fingerprints, JavaScript, and trust checks.
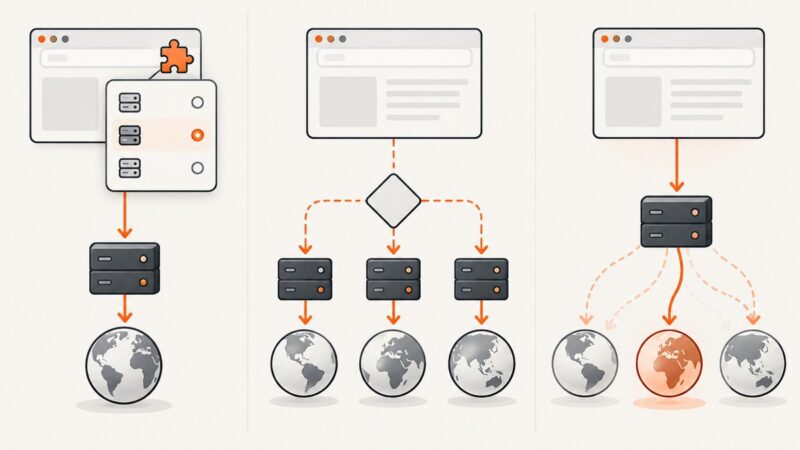
Learn how to automate proxy rotation, choose sticky sessions, handle 429s, and build reliable clients without bypassing access controls.
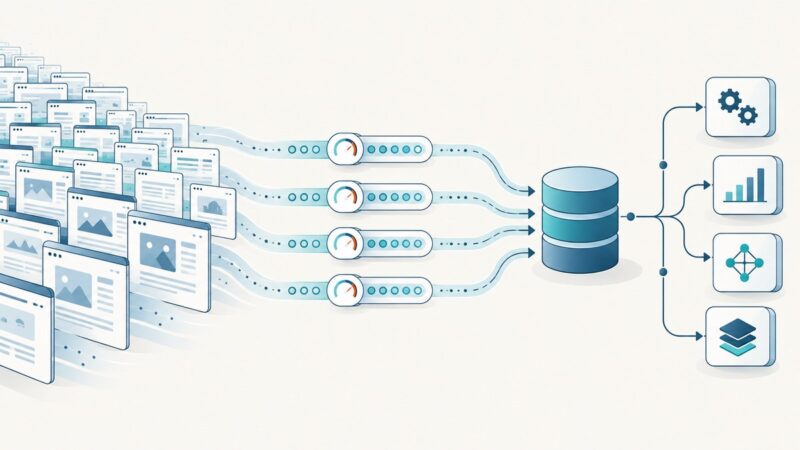
Build reliable collection pipelines by choosing the right source, partitioning work, controlling request rates, and making storage and recovery part of the design.
Make browser automation less flaky with user-focused checks, isolated state, resilient Playwright locators, retrying assertions, and useful failure evidence.
Design bounded MCP tools, reliable n8n workflows, and observable browser automation that can move safely from prototype to production.
Learn how to capture, stream, and embed browser automation replays, with runnable Browserless examples and guidance on formats, privacy, and troubleshooting.
A practical guide to moving records through web interfaces with Selenium, Playwright, Puppeteer and Chrome automation—plus validation, security and retries.
Compare file-conversion APIs for Markdown and text, with runnable cURL, Python, and Node.js workflows, OCR guidance, limits, errors, and costs.