Building AI-Powered Web Scraping Applications
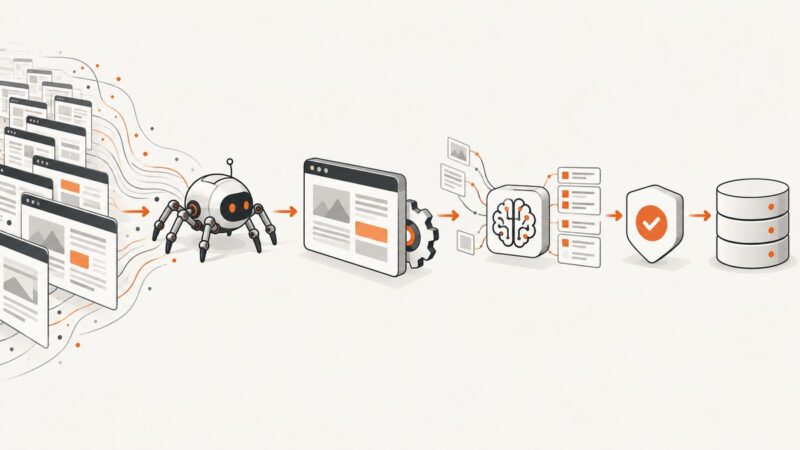
Design a reliable AI scraping pipeline with Scrapy, Playwright, schema validation, provenance, monitoring, and compliant data practices.
Puppeteer, Playwright, Selenium and headless Chrome, and what they take to run well.
Design a reliable AI scraping pipeline with Scrapy, Playwright, schema validation, provenance, monitoring, and compliant data practices.
Learn how to collect, clean, annotate, and govern AI training data, with a practical pipeline for quality, privacy, provenance, and ongoing maintenance.
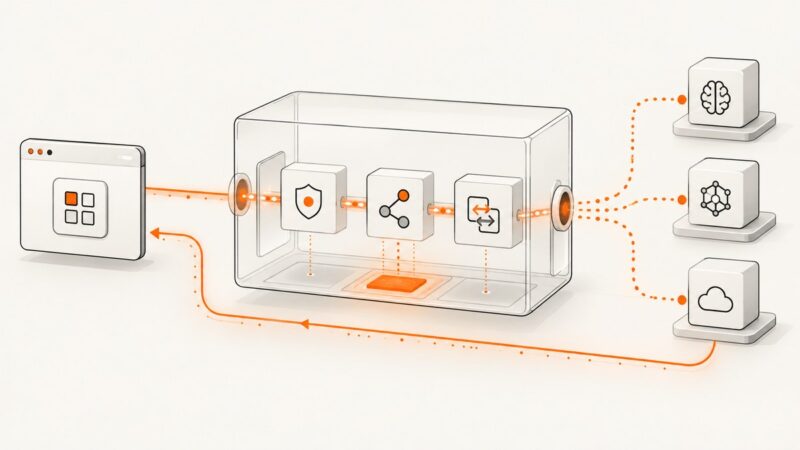
Trace an AI proxy request from authentication and routing to provider response, retries, logging, and practical implementation choices.
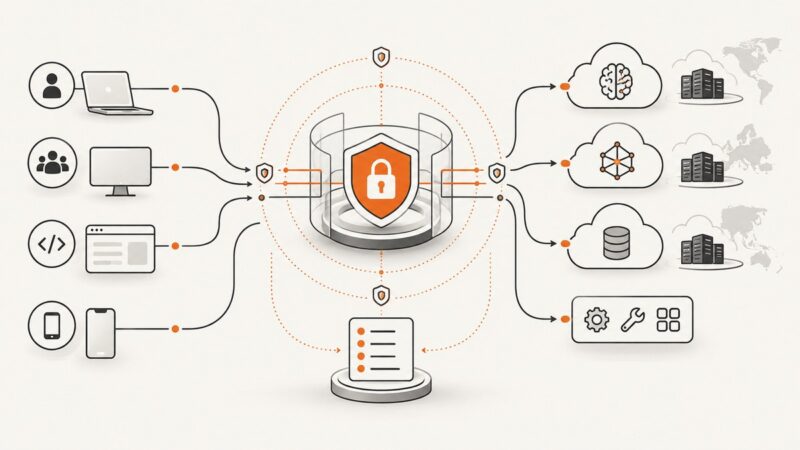
Learn how an enterprise AI proxy centralizes model traffic, enforces zero-trust policy, and creates audit evidence across teams and providers.
CAPTCHAs can protect sensitive actions, interrupt visitors, and stop browser tests. Learn how challenge types differ and how to build reliable, accessible flows.
Learn what CIDR prefixes mean, calculate IPv4 and IPv6 block sizes, plan subnets, aggregate routes, and avoid common addressing mistakes.
Build a concurrent, resource-bounded Go scraping worker with reusable HTTP connections, measured tuning, profiling, and practical troubleshooting.
Scale scraping with Apify Actor factories by batching work, sharing durable storage, and coordinating child runs with retries, rate limits, and cost controls.
Compare fixed, random, sticky and adaptive proxy routing, with implementation patterns, failover limits, session rules, retries and monitoring guidance.
Learn what Akamai documents about _abck, Bot Manager sensor data, bot scores and privacy—and what a cookie value alone cannot tell you.
Run Playwright or Selenium workers in the regions that matter. Learn how to route jobs, configure egress, isolate sessions, and keep failures observable.
Diagnose Scrapy 403, 429 and 503 responses with nine evidence-based checks, safer settings, troubleshooting steps and authorized alternatives.
Learn how browser automation reaches rendered UI, session state, and interaction triggered requests, and when direct APIs remain the better choice.
Learn what HTTP 508 Loop Detected means, why WebDAV recursion triggers it, and how to find and fix cyclic bindings safely.
Learn what Google JAX is, how jit, grad, vmap and pmap work, how to install it on CPU, GPU or TPU, and when to use it.
Retail scraping attacks remain high as AI crawlers and shopping agents focus on product discovery. Here’s what the 2025 data means for retailers in 2026.
Learn how to detect spoofed browser fingerprint values with consistency checks, privacy-aware scoring, runnable code, and practical safeguards.
Build a secure Node.js webhook that verifies raw requests, prevents duplicates, and generates PDFs reliably with PDFKit or a hosted service.