How to Automatically Extract Structured Information from Unstructured Text
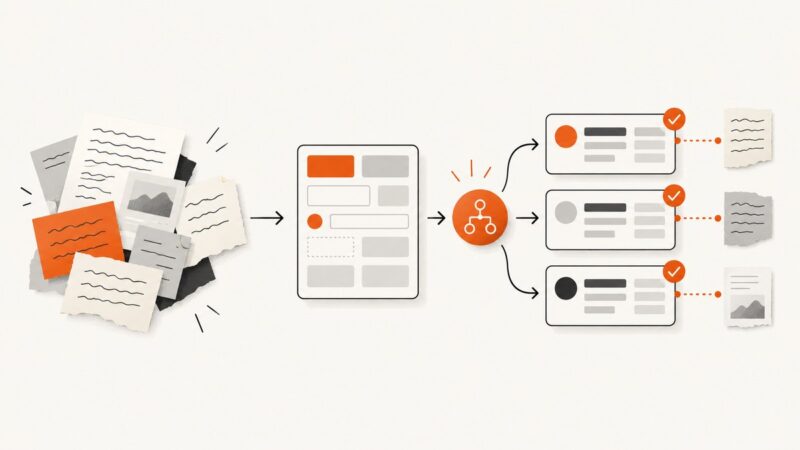
Turn free-form text into validated records by defining a schema, choosing the right extraction method, and checking every value against its source.
Turn free-form text into validated records by defining a schema, choosing the right extraction method, and checking every value against its source.
Choose a ready-made crypto widget for a quick website chart, or build a custom pipeline that fetches market data and renders a branded graphic.
Speed up browser automation by recording a first draft, replacing brittle waits and selectors, isolating test state, and scaling independent tests in CI.
Build an automated content-gap pipeline using site crawling, competitor comparisons, Search Console data, and a scoring model that chooses new pages or updates.
Capture website screenshots in Python with Playwright or a hosted API. Compare the tradeoffs, configure common options, and troubleshoot failures.
Batch property photos into a balanced, branded collage, then export files sized for your listing portal and marketing channels.
Fetch and parse HTML tables in ASP.NET with C#, Html Agility Pack, and reliable handling for headers, nested markup, dynamic pages, and failures.
Capture viewport, full-page, and element screenshots as PNG in Ruby with Ferrum or Cuprite, then compare a browser-free API workflow.
Find where rendered assets are saved, download completed cloud renders, and choose the right format for images, frame sequences, and movies.
Find the BGP origin ASN for an IPv4 or IPv6 address, check the covering prefix, and understand what the result does—and does not—tell you.
Substack documents a publication RSS feed, but its terms prohibit scraping. Here’s how to read the feed, what the API terms cover, and where the limits are.
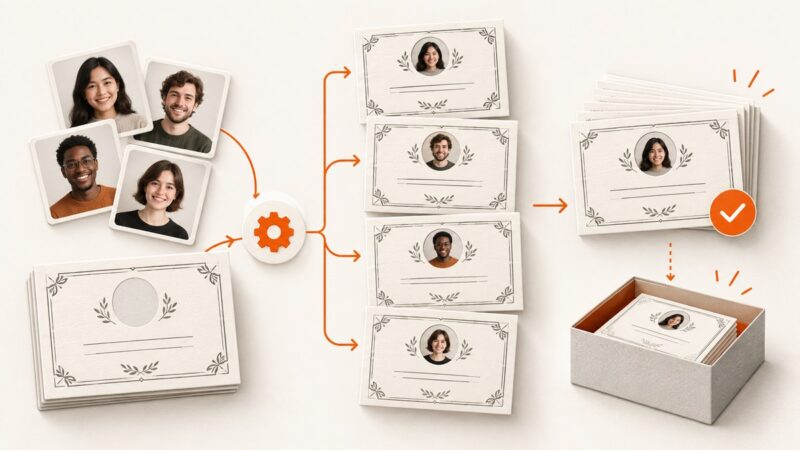
Create personalized certificate images with recipient photos using Canva Bulk Create or a Google automation workflow, then check and export each batch safely.
Configure datacenter proxies in Playwright, choose rotation or sticky sessions, and troubleshoot routing for authorized browser automation.
Capture a viewport, region, element, or full webpage, then convert PNG screenshots to WebP with browser tools, Firefox DevTools, cwebp, or an API.
Use Cloudflare’s dummy keys, validate tokens server-side, and build reliable Playwright tests without solving production bot challenges.
Plan a ScrapeOps API migration by identifying your current integration, mapping provider-specific options, and validating real page content before cutover.
Design a reliable event ID and QR check-in flow with secure identifiers, runnable Python code, validation, duplicate handling, and delivery options.
Build a repeatable workflow to generate branded Instagram carousel covers, validate image requirements, and publish them by hand or API.