How to Click Cookie Popups and Modal Alerts in Selenium
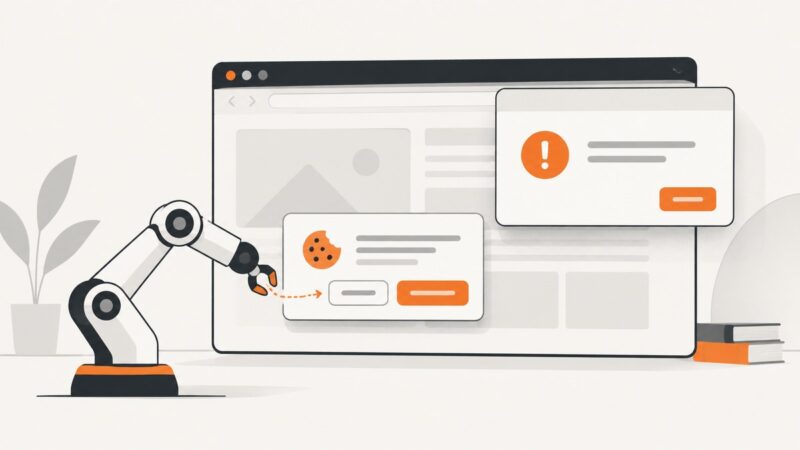
Tell browser alerts from page modals, then use Selenium waits and the right interaction to accept, dismiss, or handle cookie banners reliably.
Tell browser alerts from page modals, then use Selenium waits and the right interaction to accept, dismiss, or handle cookie banners reliably.
Add repeating headers, footers, and page numbers to PDFs in Go with go-pdf/fpdf callbacks, deliberate margins, and a complete runnable example.
Use Activepieces’ Browserless piece to capture website screenshots in a no-code flow, troubleshoot common issues, and compare an API-based shortcut.
Build a date-keyed Airbnb price table in Python using permitted public datasets, with nightly-price semantics, validation, and practical troubleshooting.
Add text or image watermarks to screenshots in Node.js with Sharp, precise positioning, transparent SVGs, output formats, troubleshooting, and automation tips.
Build a reliable flight deal tracker with live API polling, price history, flexible dates, deduplicated alerts, and refresh-before-booking checks.
Build a reliable screenshot pipeline that cleans pages, waits for content, and adds padding, backgrounds, rounded corners, shadows, and annotations.
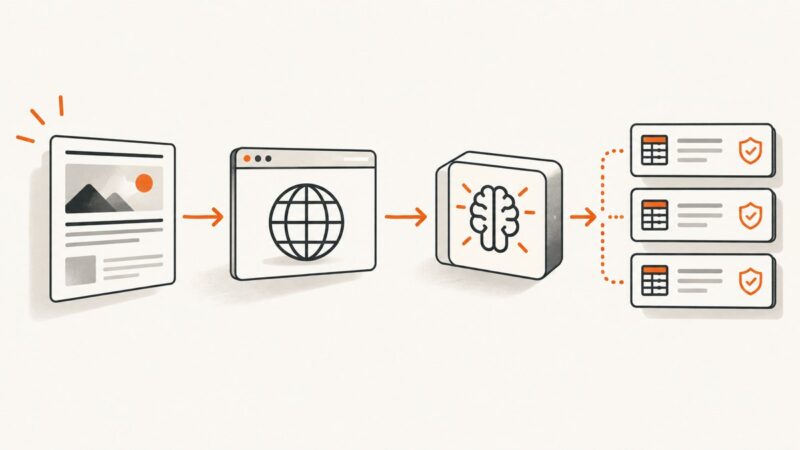
Build a compliant pipeline that fetches permitted pages, extracts fields with ChatGPT, validates JSON, and preserves evidence for every record.
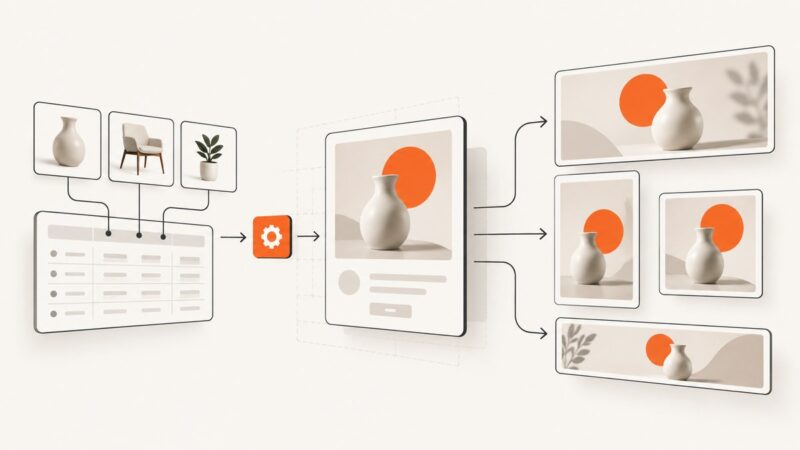
Learn how to automate branded marketing images from reusable templates, compare API workflows, handle async renders, and choose the right approach for your content.
Install Apache Kafka 4.3.1 on Windows or Linux with Java 17, standalone KRaft commands, Docker, verification steps, fixes, and production notes.
Use AI to find cookie banners and overlays, then combine Playwright request blocking and targeted page cleanup for repeatable screenshots.
Change your reported browser identity for compatibility tests in Chrome, Firefox, Safari, Edge, and automation tools—with reset steps and limits.
Configure branded Apache and Nginx error pages while preserving the real HTTP status. Includes static, dynamic, and proxy examples plus validation and troubleshooting.
Learn how to build a reliable AI web scraper that renders JavaScript, extracts typed JSON, validates fields, and preserves provenance.
Build a reliable pipeline that turns article metadata into consistent news cover images with image APIs, validation, storage, and review.
Capture an entire webpage from header to footer using Chrome, Firefox, Edge, Safari, automation, or ScreenshotNeo—with fixes for lazy loading and sticky headers.
Configure CORS in Apache with mod_headers or in Nginx with add_header. Handle preflight, credentials, multiple origins, caching, and common errors safely.
Read Figma file data, export selected layers, and build a reliable automation pipeline with the REST API, including authentication and rate-limit handling.