How to Scrape Job Postings with an AI Job Board Scraper
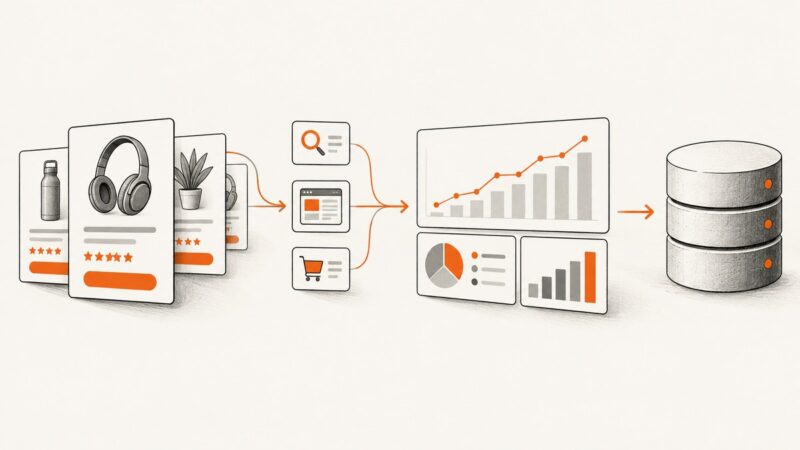
Build a job-posting pipeline that starts with permission, parses predictable fields with rules, and uses AI only for supported extraction.
Build a job-posting pipeline that starts with permission, parses predictable fields with rules, and uses AI only for supported extraction.
Learn how to choose a truthful User-Agent, configure it in Python and other clients, follow robots.txt, and troubleshoot blocks without pretending to be a browser.
Learn the compliant way to collect Amazon Sponsored Products search-term, campaign, and placement data using reports, the Ads API, or browser automation.
Pass Authorization, API key, and other custom headers to the page a screenshot browser loads. Learn the GET and POST patterns, secure credentials, and fix common failures.
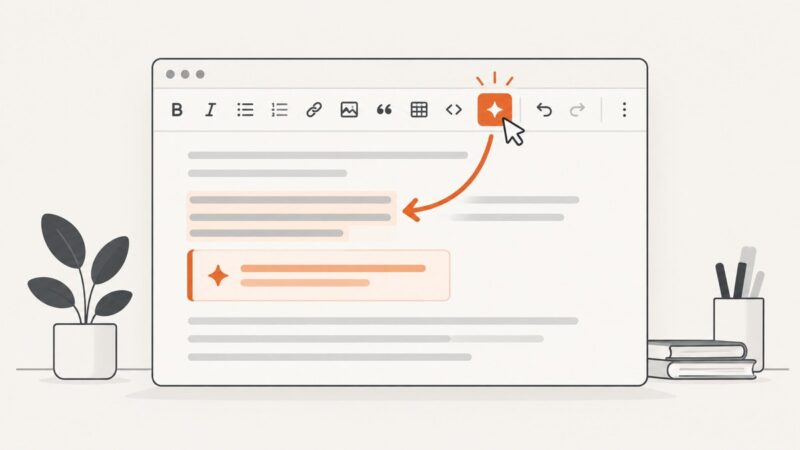
Add custom toolbar buttons to TinyMCE, CKEditor 5, or CKEditor 4 with the right extension API, lifecycle, accessibility, and troubleshooting steps.
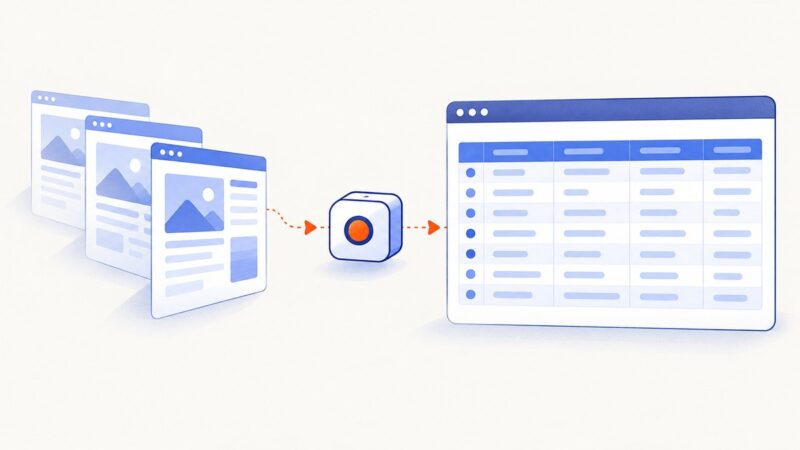
Use Playwright to wait for rendered rows, extract each page safely, paginate, validate results, and avoid common JavaScript scraping failures.
Learn how to test font contrast, resizing, spacing, glyph clarity, and assistive-technology behavior against WCAG.
Capture web pages and rendered Laravel views, save screenshots to local storage or S3, and run reliable screenshot jobs with Spatie Laravel Screenshot.
Install Bootstrap CSS in Angular, configure global styles, and choose a safe path for interactive components. Includes npm, CDN, troubleshooting, and verification steps.
Turn a generated still into an animated GIF, optimize it for the web, or embed a hosted GIF with responsive HTML. Includes workflow, code, and fixes.
Trace JWT embed failures from the browser request to token validation, CORS, frame policy, and cookies, then apply the fix that matches the evidence.
Use httplib2 to make authenticated HTTP requests: add credentials, handle challenge-response authentication, and troubleshoot common failures.
Use Playwright Java to log in, save authenticated browser state, and capture protected pages. Learn cookie and HTTP auth options, security practices, and fixes.
Build a reliable pipeline that turns one master design into channel-ready graphics while protecting text, logos, focal points and brand quality.
Use aiohttp for Basic, Digest, bearer-token and cookie-based pages, with secure sessions, redirects, TLS, retries and troubleshooting.
Learn how to scrape websites with Guzzle in PHP: headers, cookies, redirects, retries, JavaScript limits, troubleshooting, and a browser-rendering alternative.
Check AAAA records, follow CNAMEs, compare authoritative and recursive DNS, then test a real IPv6 connection. A DNS answer alone does not prove readiness.
Build a MAP monitor that collects advertised offers, checks versioned policies, and preserves evidence. Includes architecture, runnable Python, and alerting guidance.