URL Path Parameters: A Complete Guide
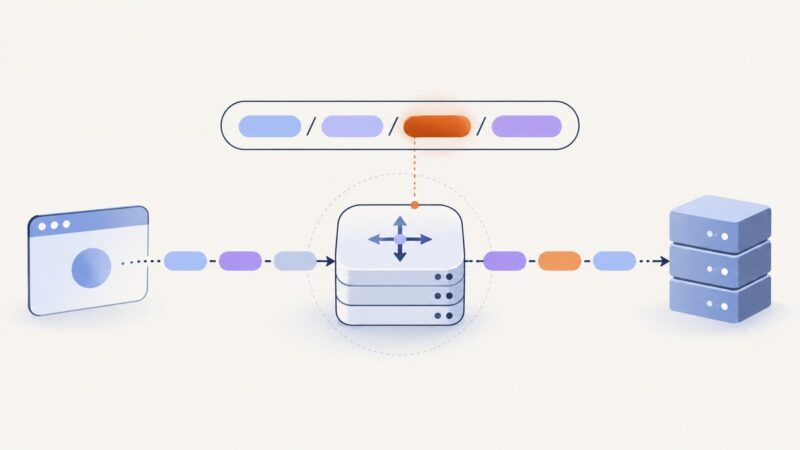
Learn how URL path parameters work, how to validate them, avoid route conflicts, and implement them in Express, FastAPI, and Django.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Learn how URL path parameters work, how to validate them, avoid route conflicts, and implement them in Express, FastAPI, and Django.
Learn when to use WeasyPrint, Playwright, or xhtml2pdf to convert HTML to PDF in Python, with runnable code, deployment guidance, and security fixes.
Send a raw HTML string from C# with HttpClient, receive PDF bytes, resolve assets, handle errors, and choose between hosted APIs and local renderers.
Render HTML as JPEG in C# with CoreHtmlToImage, PuppeteerSharp, or Playwright. Compare setup, control, quality, and a hosted API option.
Install Cursor, open a real project, make your first reviewed change, and configure plans, privacy, models, and usage safely.
Use Playwright for .NET to capture a website from a URL in C#, then choose viewport, full-page, element, and in-memory output for your use case.
Capture complete webpages in PHP with Browsershot or Playwright, handle lazy loading and failures, and compare a hosted ScreenshotNeo workflow.
Build a reliable competitor price tracker with product matching, normalization, change alerts, compliance checks, and production-ready scraping code.
Capture an entire scrollable page with Playwright or Puppeteer, handle lazy content, choose image settings, and troubleshoot common screenshot failures.
Render HTML in a headless browser, wait for assets and JavaScript, then capture a PNG, JPEG, or WebP with Node.js.
Capture a website in TypeScript with Playwright or Puppeteer. Learn viewport, full-page and element screenshots, readiness, formats, troubleshooting and an API alternative.
Stop stuck HTML-to-PDF jobs by separating navigation timeouts, readiness checks, cancellation, and load-error handling in Playwright, Puppeteer, and wkhtmltopdf.
Capture a chosen HTML element when a user clicks a button, convert it to a downloadable image with html2canvas, and understand the browser security and rendering limits.
Hadoop is an ecosystem; Spark is a processing engine. Compare MapReduce, YARN, HDFS, workloads, deployment, performance, and cost before choosing.
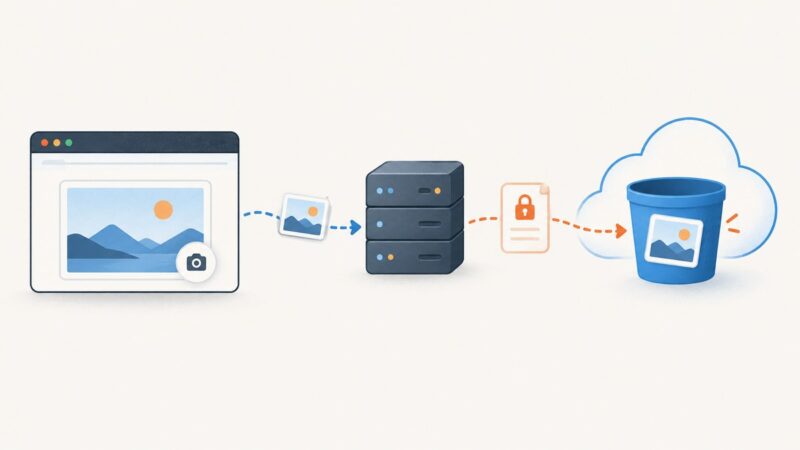
Upload screenshots directly to S3-compatible storage with a backend-generated presigned URL. Learn secure browser PUTs, CORS, multipart uploads, and fixes for common errors.
Build fair, readable comparison graphs and export them as images with practical workflows for spreadsheets, Python, JavaScript, Canva, and Datawrapper.
Compare Trello and monday.com on plans, views, automation, reporting, and team fit. Choose a tier by checking live pricing and your workflow needs.
Learn how MCP servers turn web pages into image results, with a runnable Python server, client examples, security guidance, and a hosted shortcut.