Unit Testing AI Agents in the Browser
Build browser-agent tests that produce useful evidence: deterministic Playwright checks for critical flows, controlled agent exploration, and artifacts that make failures diagnosable.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Build browser-agent tests that produce useful evidence: deterministic Playwright checks for critical flows, controlled agent exploration, and artifacts that make failures diagnosable.
Add text to an existing screenshot or capture a page element, watermark it on a canvas, and export a downloadable image with JavaScript.
Build a concurrent, resource-bounded Go scraping worker with reusable HTTP connections, measured tuning, profiling, and practical troubleshooting.
Build a GIF caption workflow with FFmpeg drawtext, palette generation, and palette use. Learn how to handle fonts, placement, transparency, looping, and common errors.
Build a job-posting pipeline that starts with permission, parses predictable fields with rules, and uses AI only for supported extraction.
Learn how to choose a truthful User-Agent, configure it in Python and other clients, follow robots.txt, and troubleshoot blocks without pretending to be a browser.
Learn the compliant way to collect Amazon Sponsored Products search-term, campaign, and placement data using reports, the Ads API, or browser automation.
Pass Authorization, API key, and other custom headers to the page a screenshot browser loads. Learn the GET and POST patterns, secure credentials, and fix common failures.
Inject runtime CSS into HTML before PDF capture with Playwright, Puppeteer, or WeasyPrint. Fix print media, fonts, pagination, assets, and security issues.
Inject a Java CSS String into HTML, convert it to PDF with iText, resolve assets, troubleshoot ignored styles, and compare a hosted screenshot option.
Build a safe agent workflow for generating PDFs: tool design, HTML rendering, Puppeteer and Playwright code, security, troubleshooting, and ScreenshotNeo.
Add custom toolbar buttons to TinyMCE, CKEditor 5, or CKEditor 4 with the right extension API, lifecycle, accessibility, and troubleshooting steps.
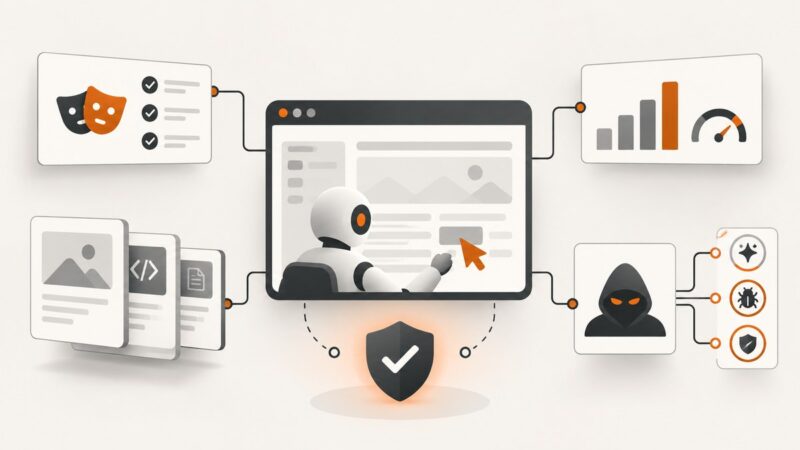
A practical framework for proving browser agents completed tasks safely, with Playwright checks, evidence bundles, benchmarks, and red-team tests.
Add reusable headers, footers, page numbers, first-page variants, and overlays to C# PDFs with Syncfusion, QuestPDF, and iText guidance.
Learn why PHP PDF libraries ignore inline JavaScript, how to prepare dynamic HTML, and when to use a browser-backed renderer or ScreenshotNeo.
Use Playwright to wait for rendered rows, extract each page safely, paginate, validate results, and avoid common JavaScript scraping failures.
Use Browserless MCP to capture webpages as images or PDFs and record browser sessions as WebM, with setup steps, runnable examples, and troubleshooting.
Scale scraping with Apify Actor factories by batching work, sharing durable storage, and coordinating child runs with retries, rate limits, and cost controls.