Add an Image Watermark to PDFs in Python with aiohttp
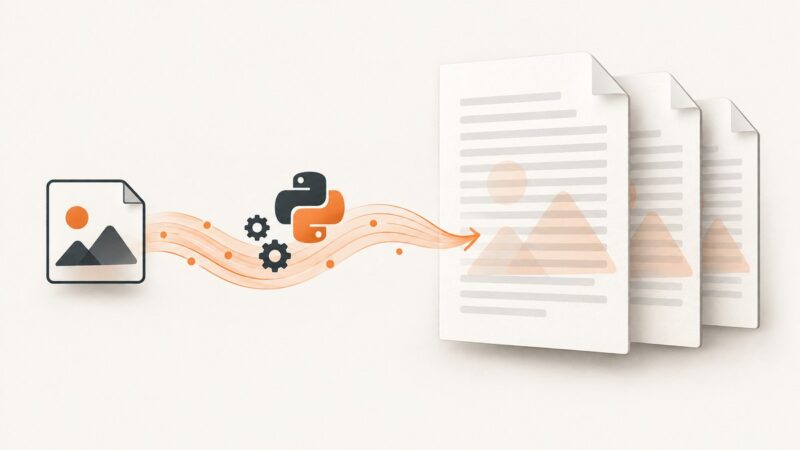
Download a watermark with aiohttp, place it behind every PDF page with PyMuPDF, and choose between in-memory and streamed downloads.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Download a watermark with aiohttp, place it behind every PDF page with PyMuPDF, and choose between in-memory and streamed downloads.
Trace JWT embed failures from the browser request to token validation, CORS, frame policy, and cookies, then apply the fix that matches the evidence.
Use httplib2 to make authenticated HTTP requests: add credentials, handle challenge-response authentication, and troubleshoot common failures.
Use Playwright Java to log in, save authenticated browser state, and capture protected pages. Learn cookie and HTTP auth options, security practices, and fixes.
Learn how URL screenshot APIs give AI agents visual evidence, when to use HTTP, MCP, or Playwright, and how to capture reliable screenshots safely.
Learn when to use CSS selectors, semantic locators, browser protocols, and ReAct agent loops for reliable web automation.
Build a reliable pipeline that turns one master design into channel-ready graphics while protecting text, logos, focal points and brand quality.
Capture a webpage with Playwright, pass it to a LlamaIndex agent as an ImageBlock, and handle multimodal tools, failures, and production trade-offs.
Compare Abyssale, Creatomate, Bannerbear and Cloudinary for high-volume image and video generation, with practical selection criteria and API patterns.
Compare nine Walmart scrapers by reliability, fields, geo-targeting, speed, integrations, price and technical effort before choosing an API.
Build a Cartesia voice agent with Pipecat or Managed Agents. Compare the paths, run a browser demo, estimate costs, and plan tests for real calls.
Connect Claude Code, Cursor, VS Code, or Codex to Figma with MCP, inspect design context, implement a screen, and manage write access safely.
Use aiohttp for Basic, Digest, bearer-token and cookie-based pages, with secure sessions, redirects, TLS, retries and troubleshooting.
Learn how to scrape websites with Guzzle in PHP: headers, cookies, redirects, retries, JavaScript limits, troubleshooting, and a browser-rendering alternative.
AI data extraction turns PDFs, scans, and other documents into structured fields. Learn how the pipeline works, where OCR fits, and how to handle accuracy.
Learn what Akamai documents about _abck, Bot Manager sensor data, bot scores and privacy—and what a cookie value alone cannot tell you.
Learn how Browser MCP connects AI agents to real browsers, with Playwright setup, Chrome session modes, security guidance, troubleshooting, and screenshots.
Learn how MCP hosts call Playwright browsers and Apify Actors, with architecture, code, security guidance, troubleshooting, and a ScreenshotNeo shortcut.