How to Build Production-Ready Web Scrapers in 30 Minutes
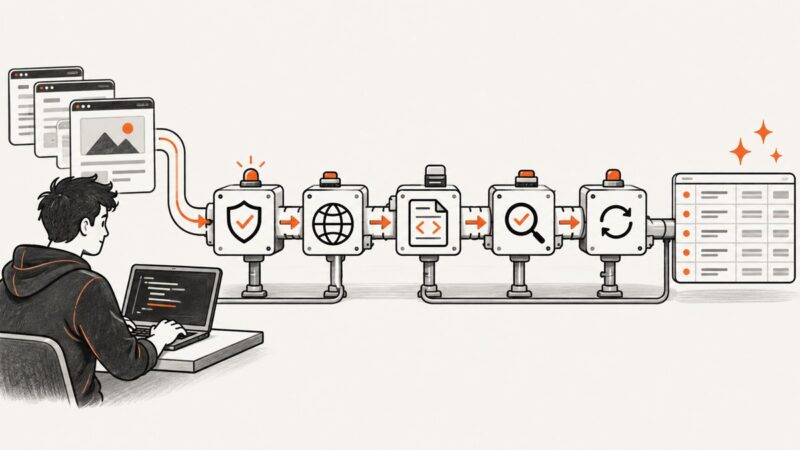
Build a dependable scraper in 30 minutes with permission checks, timeouts, retries, validation, observability, and a clear path to browser rendering.
Puppeteer, Playwright, Selenium and headless Chrome, and what they take to run well.
Build a dependable scraper in 30 minutes with permission checks, timeouts, retries, validation, observability, and a clear path to browser rendering.
Capture oversized pages safely in Puppeteer with full-page, clipped, element, memory, stitching, and troubleshooting guidance.
Improve Puppeteer performance by measuring the real bottleneck, choosing the right headless mode, and tuning capture work without sacrificing correctness.
Run Headless Chrome in Docker with Puppeteer, Selenium, or Playwright. Covers images, sandboxing, shared memory, scaling, security, and debugging.
A load test can hit its throughput target and still miss failures users experience. Learn how to test behavior, observe tails, and diagnose blind spots.
Design an HTML/CSS template editor, render faithful exports, avoid canvas traps, and choose the right capture architecture for production.
Learn how to prove Chrome uses a GPU, build repeatable Linux benchmarks, compare instances fairly, and diagnose rendering failures.
A proxy browser routes browser traffic through an intermediary. Learn how it works, what it hides, security trade-offs, setup options, and safer screenshot workflows.
Learn what stealth browser automation changes, which libraries fit testing, why detection persists, and how to build reliable authorized workflows.
Scale Puppeteer by choosing who owns Chrome, isolating task state, and measuring capacity with representative workloads. Here are runnable worker patterns and a deployment checklist.
A practical guide to reliable Laravel Dusk scaling: reproducible Chrome, isolated data, CI sharding, Selenium, debugging, and cost-aware capacity planning.
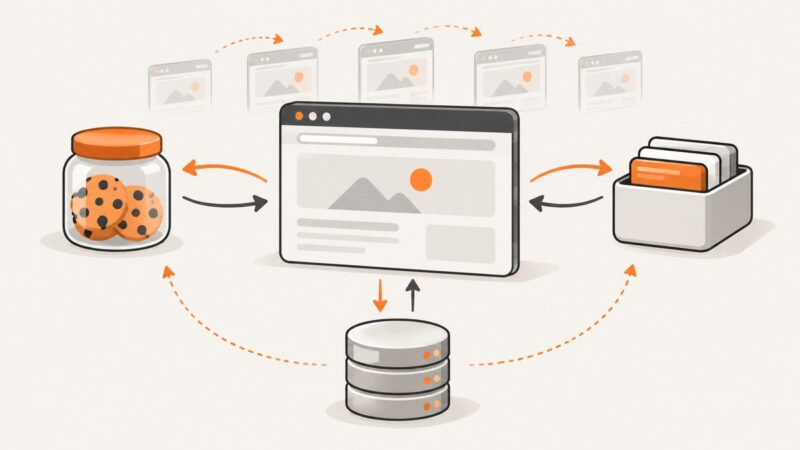
Learn what browser sessions, cookies, storage, and HTTP cache actually preserve, how to reuse them safely, and how to automate clean screenshots.
Learn BrowserQL’s GraphQL workflow for navigation, extraction, screenshots and PDFs, with runnable cURL, Python and Node.js examples.
Learn how CAPTCHA tokens, backend verification, CI test keys, and browser automation fit together without attempting unsafe or unreliable bypasses.
Build a secure Node.js gift-card issuer with cryptographic codes, unique database constraints, atomic redemption, OpenAI metadata, and Shopify integration.
Learn how managed cloud browsers work, when BaaS beats self-hosting, how to compare providers, and how to run Playwright remotely.
Design reliable headless browser automation with practical guidance on worker concurrency, session isolation, browser versions, CI, and scaling.
Learn how to capture generated images, validate them, store them privately in S3-compatible storage, and serve them safely with signed URLs.