How to Embed Base64 Images in HTML-to-PDF Documents
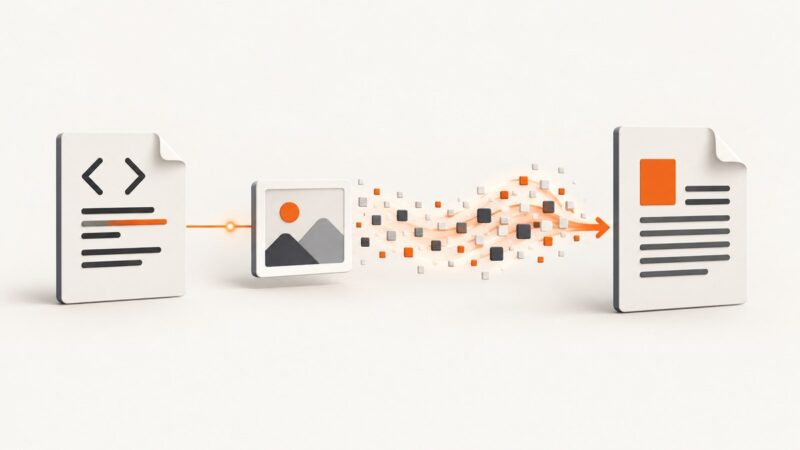
Embed image bytes as data URLs in HTML, render reliable PDFs, and fix MIME, print CSS, sizing, and missing-image errors.
Embed image bytes as data URLs in HTML, render reliable PDFs, and fix MIME, print CSS, sizing, and missing-image errors.
Check HTTP status and PDF signatures before conversion in C#. Handle error bodies, retries, validation, and malformed responses safely.
Build an automated flow from form submission to branded PDF ticket, delivery, storage, and optional check-in validation.
Compare HTML-to-PDF APIs, template platforms, broader document tools, and self-hosted renderers. Use your document workflow, requirements, and real volume to choose.
Compare browser printing, Puppeteer, Playwright, WeasyPrint, and Prince, then choose an HTML-to-PDF workflow with the right rendering and page controls.
Generate reliable invoice PDFs from login-protected URLs with Playwright, Puppeteer, direct HTTP, and ScreenshotNeo.
Embed CSS directly in your Ruby HTML or inject it with Grover to generate styled PDFs without creating a stylesheet file.
Use Puppeteer’s page.pdf() to turn a URL or HTML string into a PDF. Configure page size, print styles, backgrounds, and reliable rendering waits.
Build on-demand PDF reports from live table data, choose the right Python rendering path, save or stream the result, and handle layout and reliability issues.
Create one PDF from a paginated document, separate files, or scanned pages. Learn how to combine and order pages, use Mac Preview, and capture web pages as PDF.
Generate PDFs from web pages with Puppeteer’s `page.pdf()`. This guide covers setup, page readiness, print styling, PDF options, troubleshooting, and a no-browser API option.
Learn how to choose a PDF renderer, control layout and assets, preserve semantics, validate output, and automate reliable document generation.
Learn three reliable ways to generate multi-page PDFs with APIs, control pagination, merge pages, handle assets, and validate output.
Learn how to create PDFs through an API, choose between HTML conversion and data-driven templates, and build a reliable workflow with runnable examples.
Save clean, searchable article PDFs with reliable filenames, metadata, OCR, and full-text indexing across browsers, phones, Zotero, and Acrobat.
Learn how inline, embedded, linked, and API-supplied CSS behaves in Puppeteer and WeasyPrint, with runnable code and fixes for missing styles.
Build reliable inspection PDFs from structured field data, evidence, approvals and corrective actions, with code, templates and troubleshooting.
Embed a Python string as a PDF JavaScript action with ReportLab and pypdf, and learn where viewer support and security policies affect execution.