Convert HTML Documents to PDF Using Ruby
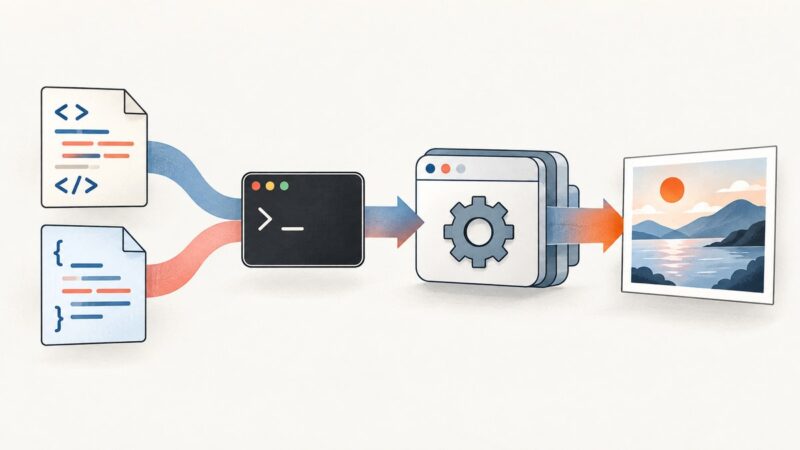
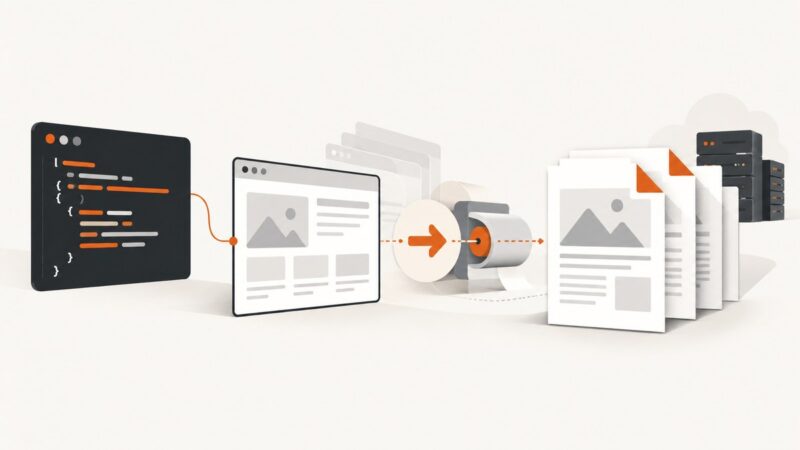
Generate reliable PDFs from Ruby HTML with Grover, Wicked PDF, or PDFKit, including assets, print CSS, security, troubleshooting, and a hosted option.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Generate reliable PDFs from Ruby HTML with Grover, Wicked PDF, or PDFKit, including assets, print CSS, security, troubleshooting, and a hosted option.
MechanicalSoup is excellent for stateful HTML scraping, but it cannot run JavaScript. Learn when to use it, how to submit forms, and when to choose a browser or API.
Learn what Instagram scraping allows, how to collect authorized data safely, process exports with Python, and avoid account, privacy, and copyright risks.
Fix Selenium’s Chromedriver path error with Selenium Manager, PATH setup, explicit Service paths, compatibility checks, and CI troubleshooting.
Avoid image scraper blocks by checking permission, identifying your client, limiting requests, and stopping when a site denies access.
Create reliable webpage PDFs with print CSS, browser print, and Puppeteer. Fix margins, page breaks, fonts, assets, and pagination problems.
Copy any Chrome network request as a reusable cURL command, understand its headers and tokens, and troubleshoot replay failures safely.
Learn how to find data loaded by JavaScript, inspect the request behind a page, and extract it responsibly with Playwright, Python, or Node.js.
Learn how to measure one file, total folders, symlinks, sparse files, errors, and disk capacity with practical Python examples.
Convert supplied HTML and CSS to JPEG with cURL, or render a public webpage. Get runnable requests, output handling, options, and fixes for common errors.
Compare Podman and Docker by architecture, rootless workflows, Compose support, desktop setup, and licensing to choose the right fit for your team.
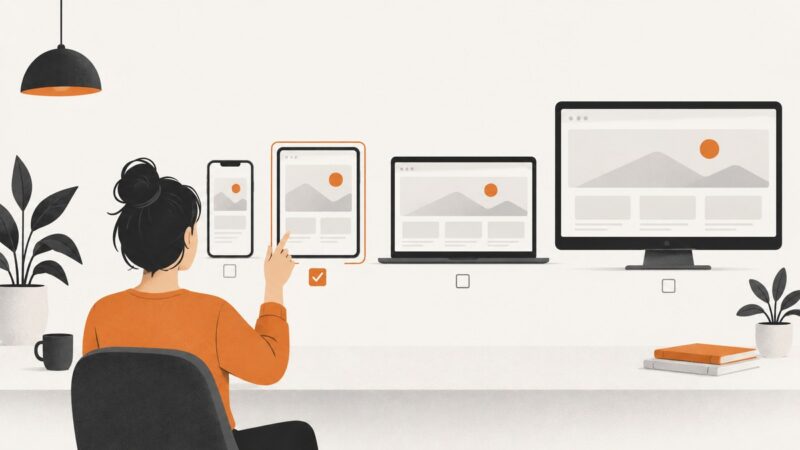
Choose screenshot viewports from real breakpoints, then control scale, page length, and device emulation for repeatable results.
Learn when to wait, fix a locator, or fail a browser test when no clickable element exists, with Playwright and Selenium examples.
Capture repeatable traffic-map frames with Playwright, record browser video, assemble a time-lapse, and understand attribution, permissions, and failure modes.
Convert a cURL request to JavaScript fetch, Node.js, or Axios. Learn the DevTools workflow, review generated code, and handle runtime differences safely.
Learn how to select adjacent, preceding, following, and bounded sibling elements with Cheerio in Node.js, with runnable examples and troubleshooting.
Learn how to check HTTP security response headers with curl, Python, Node.js, browser tools, and a practical interpretation workflow.
Move hosting or DNS without breaking your site or email. Use this staged checklist to prepare, cut over, monitor, and retire the old setup safely.