How to Find and Fix Orphaned Content in WordPress: 7 Tools
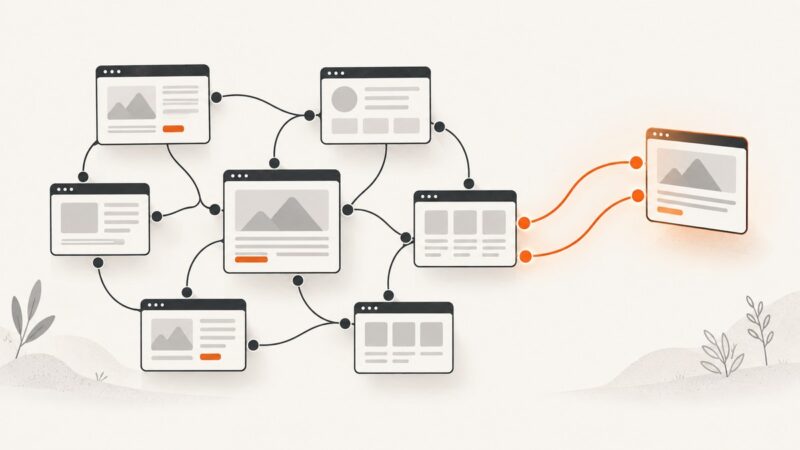
Find WordPress pages with no internal links, confirm why they are not indexed, and choose the right fix with seven practical tools.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Find WordPress pages with no internal links, confirm why they are not indexed, and choose the right fix with seven practical tools.
Design uptime alerts that catch real customer impact, filter flaky checks, and help you diagnose both failed checks and missing notifications.
Give a coding agent a clear data contract, safe access boundaries, and staged checks to build a scraping workflow you can review and maintain.
Build a reliable web-data aggregator with source selection, crawling rules, normalization, provenance, APIs, monitoring, and runnable code.
Learn how to budget SERP API credits, pace requests, paginate Google and Bing, and parse new result families without breaking production.
Build a secure aiohttp webhook endpoint with JSON parsing, GitHub signature verification, idempotency, retries, testing, and production deployment guidance.
Convert any URL or HTML into a reliable PDF with Puppeteer, Playwright, or a managed API. Control layout, assets, authentication, and print CSS.
Use customElements.whenDefined() plus a component-ready assertion to capture reliable PHP Playwright screenshots without racing hydration.
Choose a phone number extractor by its input: copied text, PDFs, local files, business websites, or job posts. Compare six tools, limits, privacy claims, and review steps.
Find a website's XML sitemap through robots.txt or common paths, then check its XML, URLs, size, and search-engine accessibility.
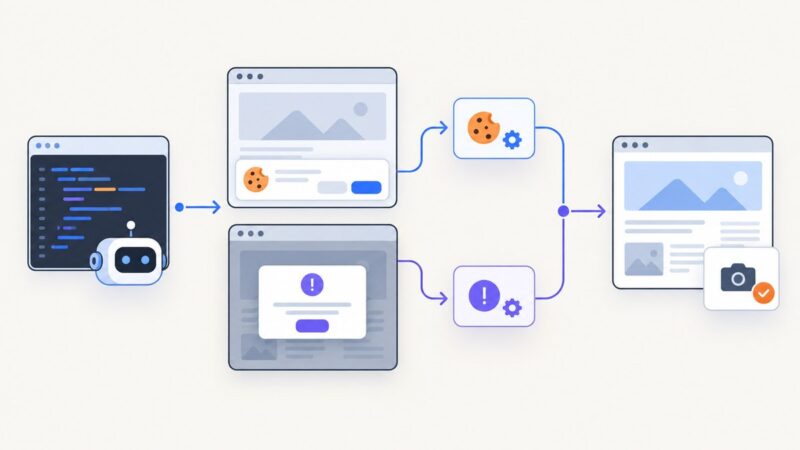
Learn when to click a DOM cookie banner, when to handle a native JavaScript dialog, and how to keep Playwright tests reliable.
Learn when AI projects need a scraper API, crawler API, official API, or hybrid workflow, with decision rules, code, costs, and troubleshooting.
Learn what Devin Desktop is, how its agent workflow works, what it costs, and how to evaluate it safely in a real software team.
Beautiful Soup parses HTML and XML; Scrapy manages crawls and extraction. Compare their roles, runnable examples, and when to combine them.
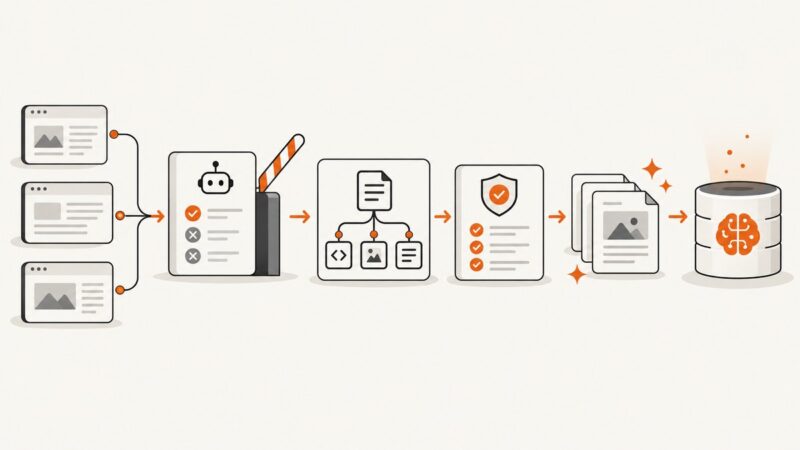
Build a permission-aware Scrapy crawler that produces clean, provenance-rich records for search, RAG, and LLM workflows.
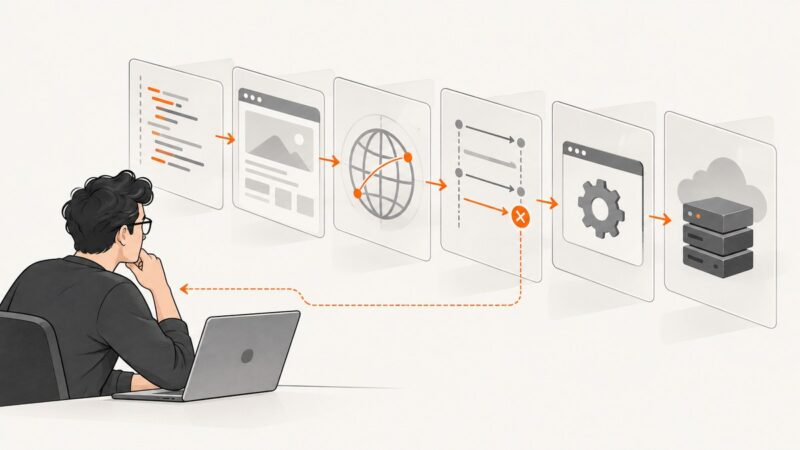
Trace Puppeteer failures across your code, page, network, DevTools protocol, browser process, and host environment—with practical debugging steps and fixes.
Learn why CSS dimensions change in DOCX, how Word calculates usable width, and how to prevent table overflow, wrapping, and pagination surprises.
A practical guide to automating healthcare workflows with web scraping while mapping ePHI, BAAs, safeguards, APIs, and operational risk.