Automatically Generate Financial Chart Images With an API
Build reliable financial chart images by validating market data, rendering Chart.js with an API, and automating PNG, WebP, SVG, or PDF output.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Build reliable financial chart images by validating market data, rendering Chart.js with an API, and automating PNG, WebP, SVG, or PDF output.
Google’s current Merchant API provides retailer pricing benchmarks and reports, but it is not a public product-search API. Learn the supported options and setup.
Learn how to build reliable Python Requests scrapers, parse HTML, handle JavaScript, timeouts, 403s and 429s, and operate responsibly.
Build and deploy a Firebase API with HTTPS Cloud Functions, callable functions, or direct REST. Includes runnable code, authentication, emulator testing, and troubleshooting.
Generate PDFs from rendered web pages with Playwright or a hosted API. Learn how to control print layout, handle failures, and choose the right workflow.
Learn the safe, repeatable way to collect Tokopedia data with seller APIs, structured data services, or crawling APIs.
Automate seven recurring sysadmin tasks with idempotent Ansible playbooks, handlers, check mode, reporting, and safe scheduling.
Learn how to extract data from metadata, embedded JavaScript state, and XHR or fetch calls with reliable browser and HTTP workflows.
Learn what scraper headers actually do, how to diagnose blocks, and how to build authorized requests safely across Python, Node.js, and cURL.
Google prohibits automated scraping of its search results. Learn what it discloses, how site owners can manage crawlers, and what robots.txt can and cannot do.
Learn when to call an AJAX endpoint directly, when to use Playwright, and how to wait for and validate JavaScript-loaded data in Python.
Learn what scraping proxies change, when to use rotating or sticky sessions, and how to crawl responsibly without treating a proxy as permission.
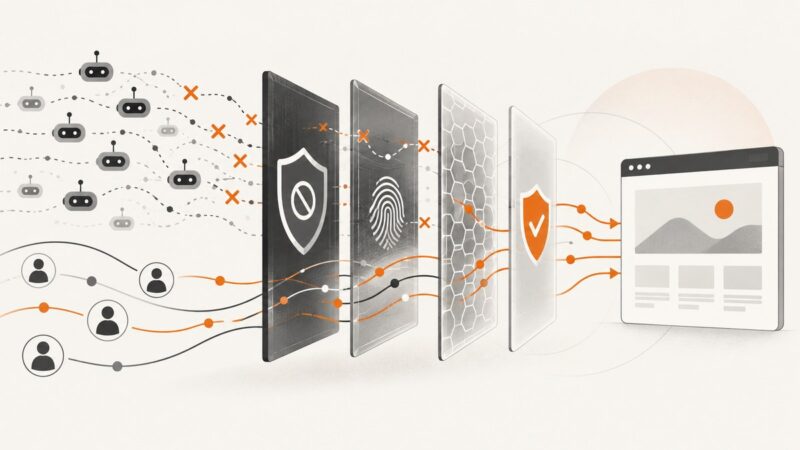
Anti-scraping combines network, browser, and behavior signals. Learn how the layers work, where they fail, and how to build defenses without blocking legitimate users.
Learn a careful Python workflow for extracting Bike24 product details, inspecting markup, handling robots.txt, and avoiding brittle or abusive crawlers.
Find and fetch a site’s real favicon, including icons declared in HTML, CDN-hosted files, and the /favicon.ico fallback—with runnable code and CORS guidance.
Anti-bot systems combine request and browser signals, classify automation, then apply a policy. Here’s what the available Cloudflare and Akamai documentation shows—and what remains unverified about DataDome.
Seven practical B2B SEO strategies to reach high-intent buyers, build authority, and connect organic rankings to qualified pipeline.
Learn how Selenium and Beautiful Soup fit together to inspect rendered flight pages, extract fields carefully, and handle access, markup, and data-quality limits.