How to Turn Reddit Upvotes into AI Training Data
Reddit upvotes can be noisy preference signals, but training on Reddit content requires permission. Learn an auditable, deletion-aware workflow.
Step-by-step guides to capturing the web: screenshots, full pages, elements, devices and more.
Reddit upvotes can be noisy preference signals, but training on Reddit content requires permission. Learn an auditable, deletion-aware workflow.
A practical REST API reference to HTTP methods, status codes, authentication, idempotency, and OpenAPI—plus runnable request examples.
An imported template can preserve content while changing the design. Find the cause, compare pages fairly, and diagnose fonts, styles, and responsive layout.
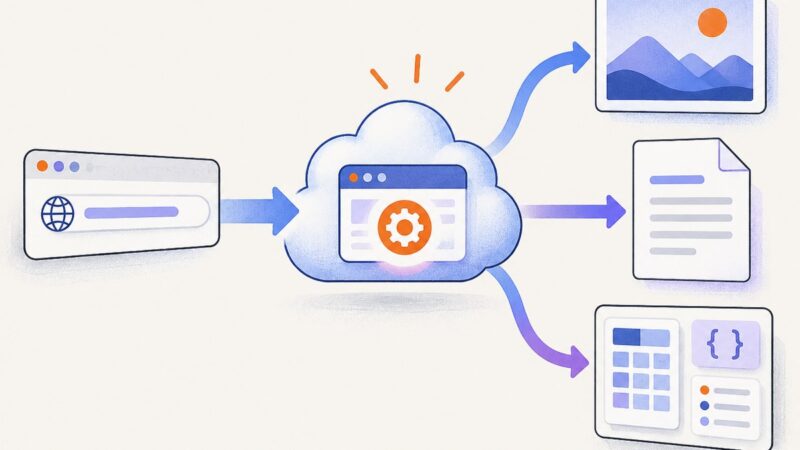
Turn any URL into an image, selectable PDF, or rendered data with browser APIs, code examples, troubleshooting, and a no-browser option.
Screenshots do not create GA4 events by themselves. Learn how to track interactions, protect Core Web Vitals, and measure screenshot impact correctly.
AI hardware is a system of processors, memory, software, and power. Learn how CPUs, GPUs, NPUs, FPGAs, and TPUs differ—and how to choose where AI runs.
AI training data comes from web crawls, licensed collections, human-created examples, public-domain works, and synthetic data. Here’s how those sources are assembled and how to check their provenance.
Learn how Scrapling keeps selectors working as websites change, when to use HTTP or browser fetchers, and how to scale resilient crawls.
Learn how browser fingerprints identify devices without cookies, what browsers expose, and practical ways to reduce tracking without breaking every site.
Control CSS page breaks with break-before, break-after, break-inside, orphans, and widows. Learn how they interact and how to troubleshoot print layouts.
Learn what Cheerio can scrape, how to load HTML, fix empty selectors, handle JavaScript pages, choose parsers, and crawl responsibly.
Find the right route to business data: SEC filings, Census statistics, federal datasets, or company registries, with practical checks for coverage, cost, and reuse.
AI data extraction turns PDFs, scans, and other documents into structured fields. Learn how the pipeline works, where OCR fits, and how to handle accuracy.
Browser automation platforms control browsers through code or recording interfaces. Learn how they work, what they can automate, how major tools differ, and where screenshots fit.
Practice scraping safely with nine purpose-built sandboxes, runnable examples, a learning path, troubleshooting advice, and production notes.
About:blank is an empty browser document, not a website. Learn why it appears, what it means for popups and iframes, and how to troubleshoot it safely.
Learn how crawling, fetching, parsing, and extraction fit together, how to choose Python tools, handle robots.txt, and troubleshoot common scraping problems.
Compare eight Python scraping tools by workload, from static HTML and large crawls to JavaScript-rendered pages, and find the right starting stack.