7 Web Scraping Tips for Reliable Scraping
Make web scraping more reliable with seven practical habits for crawler rules, request pacing, batching, monitoring, and handling robots.txt.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Make web scraping more reliable with seven practical habits for crawler rules, request pacing, batching, monitoring, and handling robots.txt.
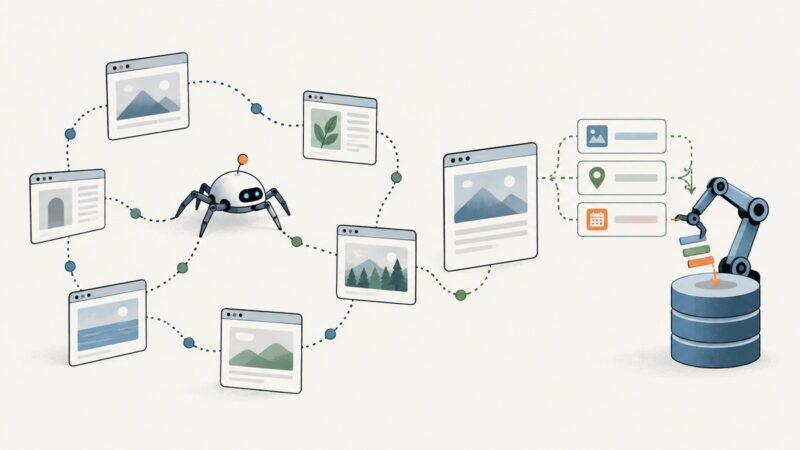
Learn the difference between crawling and scraping, how robots.txt works, legal boundaries, responsible workflows, tools, code, and reliable production practices.
Protect a PDF or Word file with an opening password, or restrict editing and printing. Follow the current Acrobat and Word desktop steps and learn the recovery risks.
Build screenshot evidence that connects your marketplace listing, policy version, and appeal record without losing context or authenticity.
Add a visible, translucent image watermark to every PDF page in C# with iText, handle page boxes and rotation, and fix common placement errors.
A practical workflow to improve a news site's Core Web Vitals, document changes with screenshots, and connect visual evidence to real user data.
Compare 12 LangChain alternatives for RAG, agents, typed Python, Azure, GCP, TypeScript, and production workflows. Choose the right fit by workload.
Upload a licensed font to Adobe Express or Canva, apply it to template text, and check file support, plan access, and team permissions before sharing.
Learn how to grant browser agents narrow, revocable access to protected data with the right OAuth flow, token controls, and practical safeguards.
Use CSS attribute selectors with :not() to find elements missing an attribute, then inspect every match with JavaScript.
Learn how to fetch pages and parse them with Beautiful Soup, choose a parser, write reliable selectors, fix encoding and missing-element issues, and scrape responsibly.
Build Airtable automations that email images, create PDFs, generate durable links, and process attachment fields with scripts.
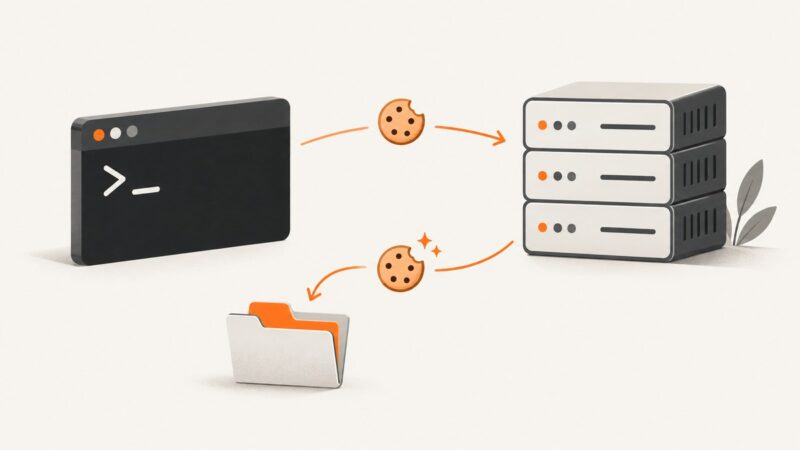
Learn how curl sends cookies, saves a cookie jar, and reuses it safely across requests, with runnable examples and fixes for common problems.
Learn when AI agents should use search, APIs, Markdown extraction, or browser automation—and how to combine them reliably.
Compare eight ER diagram makers by workflow: visual design, code-first modeling, SQL import, reverse engineering, and sharing database documentation.
Compare eight real-time HTML editors by preview speed, project scope, collaboration, sharing, packages, and persistence so you can choose the right workspace.
A repeatable workflow for capturing, labeling, comparing, automating, and safely sharing website screenshots for design inspiration.
BRAVO.de requires express permission for automated collection. Learn the compliant workflow, extraction code, troubleshooting, and a browser-free screenshot option.