Web Scraping Templates for Checking Website Resources
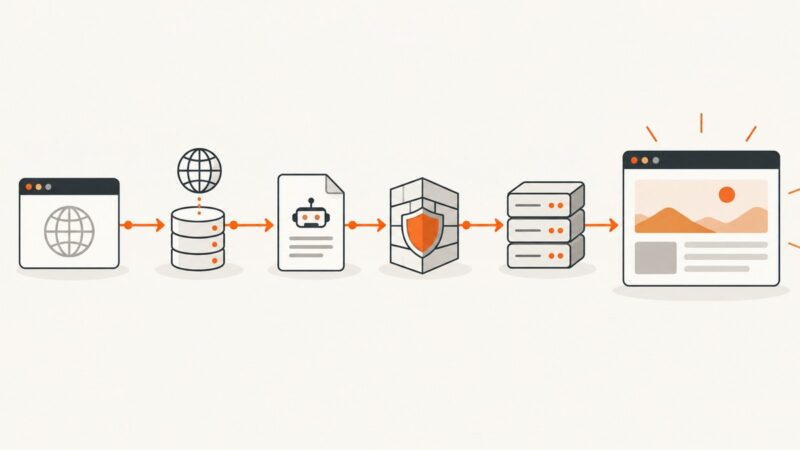
Use Python and Scrapy templates to discover site URLs, check HTTP responses, and report useful results without confusing crawl guidance with access control.
Use Python and Scrapy templates to discover site URLs, check HTTP responses, and report useful results without confusing crawl guidance with access control.
Diagnose blocked capture URLs systematically—from DNS and robots.txt to 403s, rate limits, WAFs, and rendering failures—with fixes and runnable checks.
Use Puppeteer’s page.evaluate for a direct jump, or wheel input when the site depends on user-like scrolling. Handle nested panels and infinite scroll with targeted, observable waits.
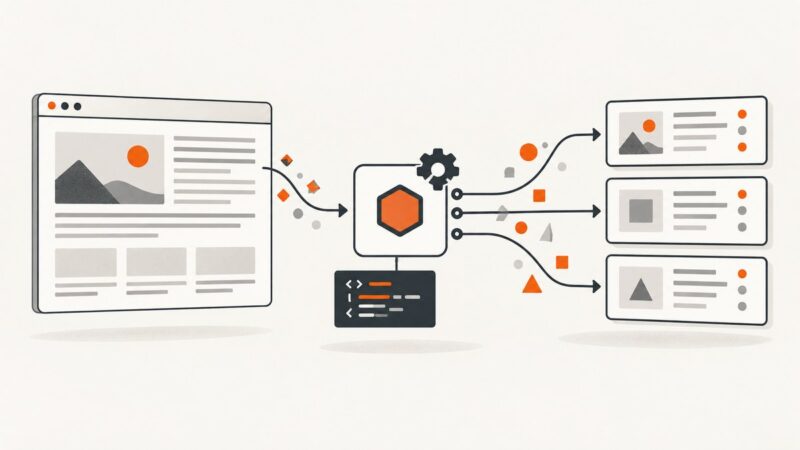
Learn Cheerio’s selectors, loaders, structured extraction, parser options, JavaScript-page limits, and production patterns for reliable Node.js scraping.
Learn a policy-aware way to collect Google results in Python, reduce blocks, handle errors, and choose an authorized API for production.
Learn how to turn bot checks, JavaScript shells and incomplete pages into accurate Markdown without bypassing access controls.
Use Thumbtack’s authorized Businesses Search API to find pros. Learn the OAuth flow, search-context approach, code structure, and the limits of automated page scraping.
Select several HTML tag types in one Cheerio query with a comma-separated CSS selector. See runnable examples, scoped searches, security tips, and fixes for common mistakes.
Java HttpClient retrieves HTTP responses but cannot render screenshots. Use Playwright Java or Selenium with authorized browser authentication to capture secured pages.
Google Sheets can insert screenshot images, but Apps Script does not render webpages. Learn the complete workflow, code, limits, and a faster API option.
Learn how URL redirection checkers trace every HTTP hop, explain 3xx responses, find loops, and reveal SEO, security, and privacy issues.
Choose proxy browser fingerprints that stay consistent across user agent, locale, graphics, WebRTC, TLS, and session state.
Check the PowerShell engine and edition running on Windows Server, then choose a supported update path for PowerShell 7 without disrupting Windows PowerShell 5.1.
Learn to scrape Betta category pages responsibly with Python, BeautifulSoup, or Scrapy. Handle pagination, JavaScript, deduplication, and validation.
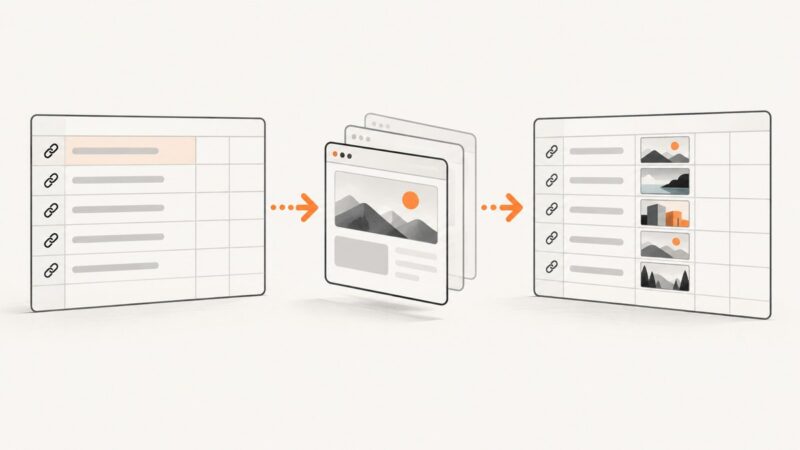
Use Apps Script and a browser screenshot API to turn a Google Sheets URL list into organized website previews, with batching and error handling.
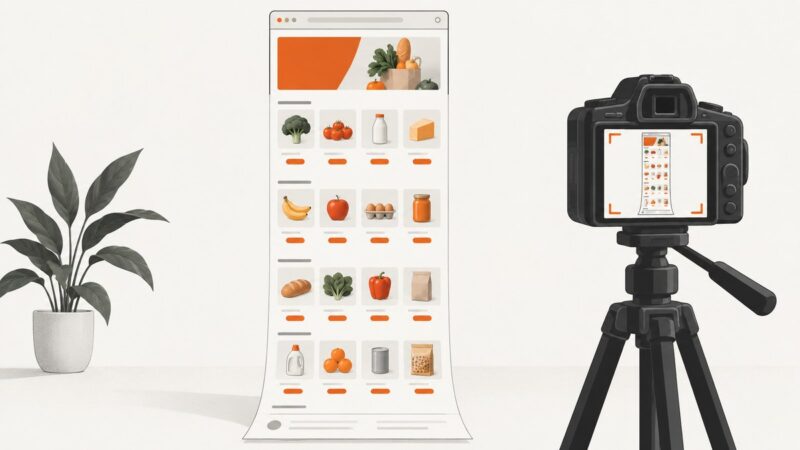
Capture a whole Tesco, Sainsbury’s, Asda, Morrisons or Waitrose page, including content below the fold, and keep the store and delivery context with it.
Learn how to test Strict-Transport-Security over HTTPS, validate max-age and subdomains, and roll out preload safely with cURL, Python, and Node.js.
Learn how to crawl responsibly without triggering blocks: permission, robots.txt, APIs, honest identity, pacing, backoff, retries, and safer alternatives.