Web Scraping Data Protection and Privacy Best Practices
Publicly visible information can still be personal data. Use this practical workflow to assess a scraping project, limit collection, and protect data.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Publicly visible information can still be personal data. Use this practical workflow to assess a scraping project, limit collection, and protect data.
Capture private intranet and localhost pages with a browser that can reach them. Choose manual screenshots, Playwright, Puppeteer, or Android port forwarding.
Choose the right Python pattern for converting parallel lists, key-value pairs, or a single list to a dictionary—and handle duplicates safely.
Learn how to ground an LLM with web search, citations, retrieval pipelines, code, failure handling, and ScreenshotNeo page capture.
Convert any webpage to a reliable PDF with browser steps, APIs, JavaScript handling, page controls, troubleshooting, and automation examples.
Use Scroll Capture in Adobe Express Photos on Windows to save a long webpage as one image, or automate clean captures with ScreenshotNeo.
Set Puppeteer PDF, navigation, browser startup, and job timeouts correctly with runnable Node.js examples, troubleshooting, and production guidance.
Build a FastAPI endpoint that captures complete webpages with Playwright, returns image bytes, handles browser lifecycle, and avoids common production failures.
Convert a whole website to PDFs with Acrobat, or crawl it with HTTrack first. Learn scope, JavaScript limits, redirects, authentication, and automation.
Get a clean, high-resolution Google Maps image with the Static Maps API, or hide controls on a custom interactive map. Here are the code, limits, and fixes.
Save a webpage as a PDF with browser printing or Acrobat, then use desktop Word when you need editable DOCX content.
Diagnose web capture SDK failures by vendor, lifecycle stage, browser policy, and exact error code—and choose a recovery that fits the cause.
Render a Rails view as a PDF with Grover, Wicked PDF or PDFKit. Compare setup, resolve assets, handle print styles and troubleshoot common failures.
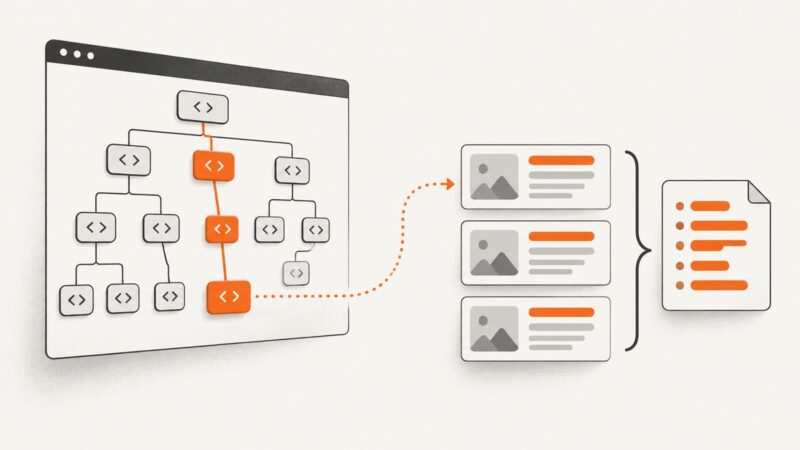
Learn how CSS selectors find elements in HTML, then extract text, links, and attributes with Scrapy and Beautiful Soup.
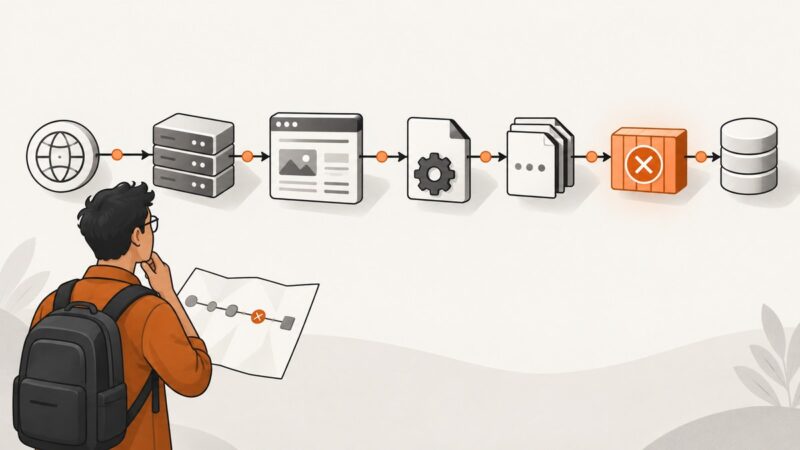
Diagnose missing records, empty fields, 429s, parsing errors, and stuck queues by finding the earliest failed stage and fixing it with evidence.
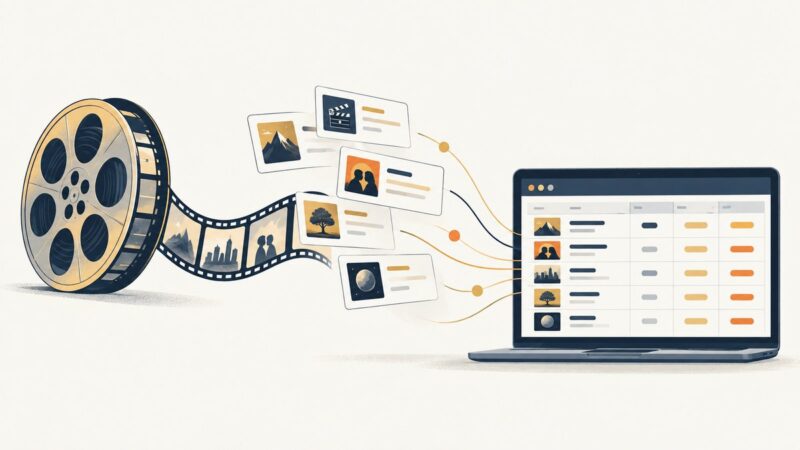
Learn the permitted ways to work with IMDb data: its non-commercial datasets, official GraphQL API, and licensing route, with runnable local parsing examples.
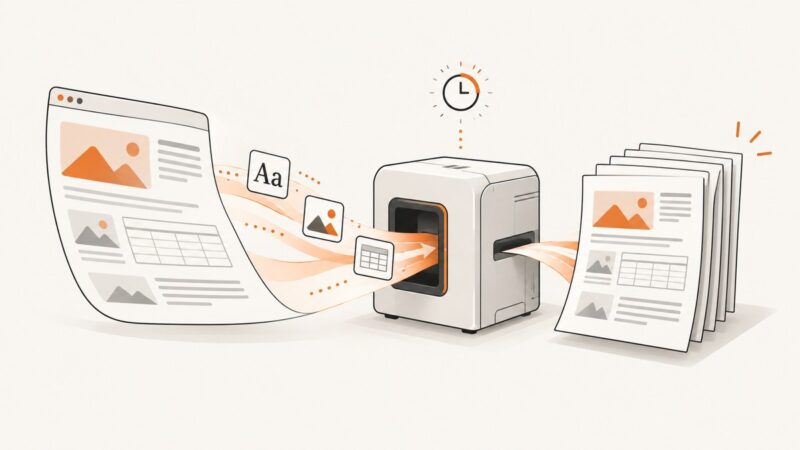
Find the slow stage in HTML-to-PDF generation, then tune waits, layout, assets, and caching without sacrificing document fidelity.
Learn how to export scraped records to JSON, JSON Lines, CSV, or XML with Scrapy, Python, and Node.js, including append-safe workflows.