How to Run Website Capture Software on Your Own Servers
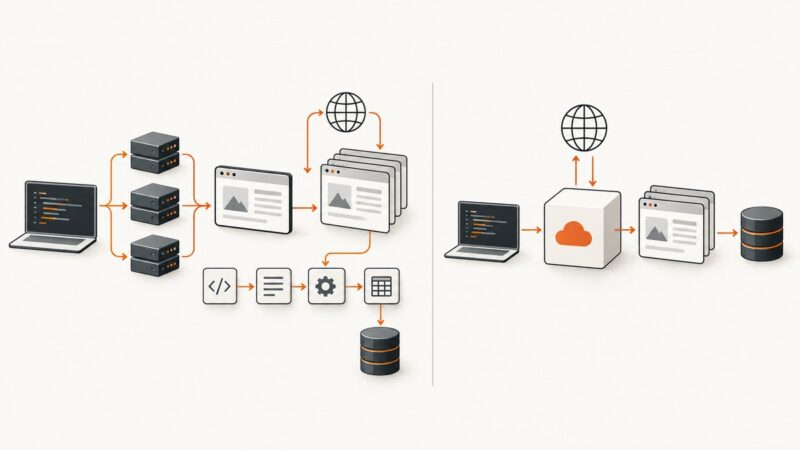
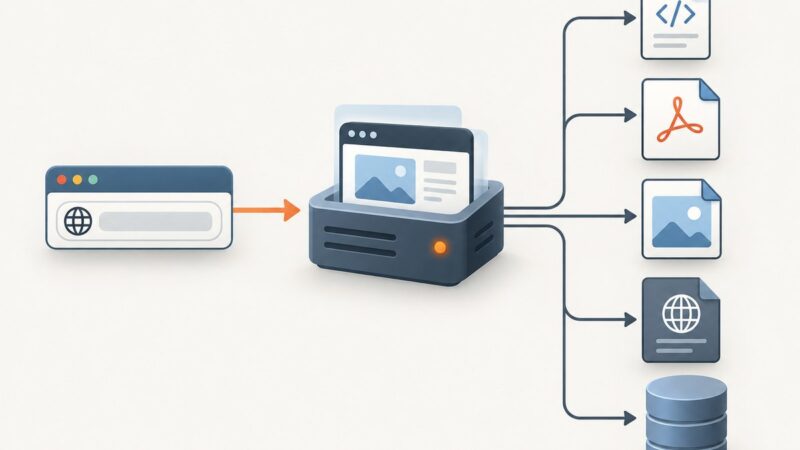
Deploy website capture software on infrastructure you control, from ArchiveBox on one Docker host to Browsertrix on Kubernetes, with storage and security guidance.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Deploy website capture software on infrastructure you control, from ArchiveBox on one Docker host to Browsertrix on Kubernetes, with storage and security guidance.
Compare raw proxies and scraping APIs by control, JavaScript support, reliability, cost, and maintenance, then choose the right architecture.
Build crash-resistant Playwright automation with Temporal Workflows, Activities, retries, versioning, and practical recovery patterns.
Install a provider’s Go SDK, authenticate safely, make a context-aware scrape request, and handle API and network errors in production.
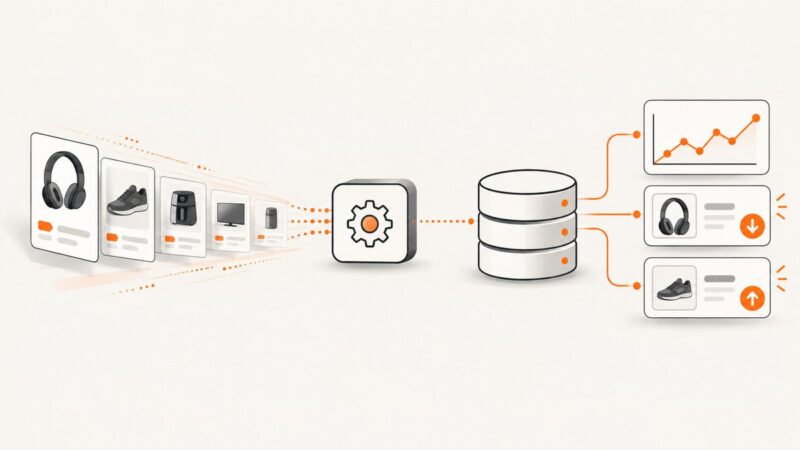
Use Walmart’s authorized APIs to identify products, collect prices, store dated observations, and detect changes without losing history.
Run Lighthouse audits across CI workers without confusing job parallelism with repeated measurements. Configure LHCI, shard URLs, handle reports, and reduce noisy results.
Learn browser printing, print CSS, Chart.js resizing, and Puppeteer automation for reliable PDFs from JavaScript-rendered pages.
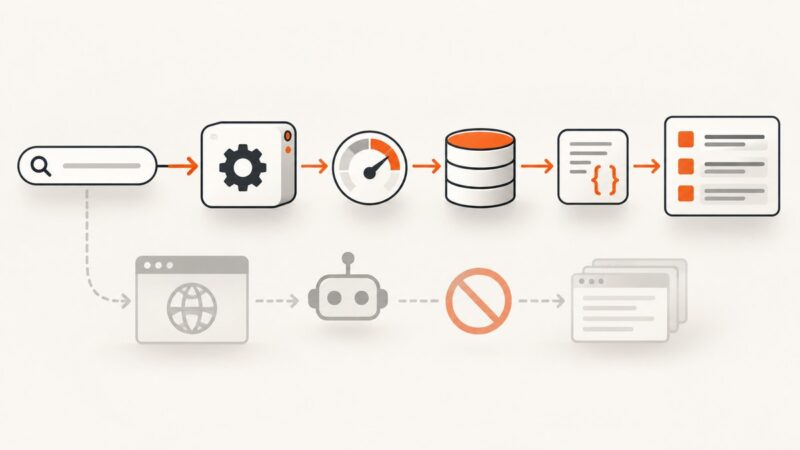
Learn how crawlers discover, fetch, render and index pages, why crawling fails, and how to diagnose robots.txt, JavaScript and server issues.
Learn to send authentication, Accept, Content-Type, cookies and custom headers with PHP cURL when calling screenshot or PDF APIs.
Capture the browser window, the visible page, or a full scrolling webpage on Windows, Mac, or Firefox—and learn where the image goes.
Learn how to inspect any webpage element, read its DOM and CSS, debug layouts, and make temporary changes in Chrome, Safari, Firefox, Edge, and other browsers.
Run JavaScript inside a headless browser with Playwright or Puppeteer. Learn how to pass data, handle async results, run code before page scripts, and call back to Node.js.
Design screenshot API errors that identify invalid inputs, explain how to fix them, and give clients a stable format they can handle.
Generate and serve page-specific Open Graph images for Google Chat. Learn the metadata workflow, build it yourself, and troubleshoot stale or missing previews.
Use @media print, @page, and Chrome 131 margin boxes to control PDF layout, page numbers, headers, footers, and troubleshooting.
Learn why Google blocks automated search scraping, the compliant API path, quota planning, reliability patterns, and safer alternatives.
Redirect IP and alternate host requests to one canonical HTTPS domain. Configure the redirect, preserve paths and queries, and verify the result.
Guzzle is not built into PHP. Learn how Composer installs it, how native streams differ, and how to fix common setup errors.