Stealth Scraping With Puppeteer and Playwright at Scale
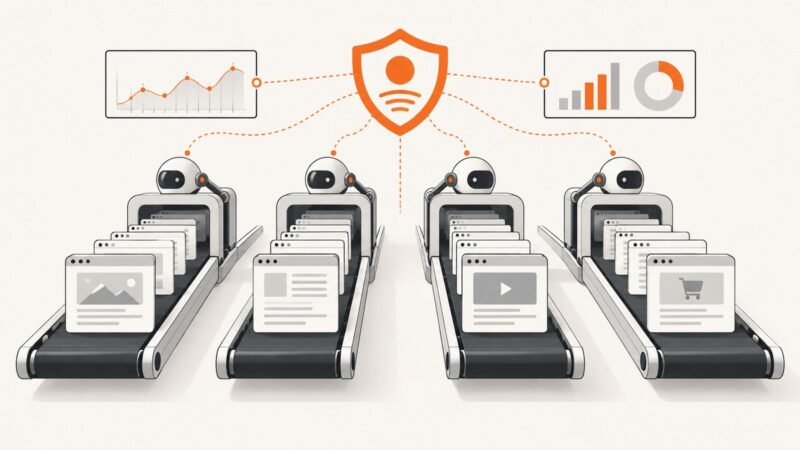
Scale Puppeteer and Playwright scraping with compatible browsers, isolated contexts, bounded concurrency, honest stealth limits, and failure handling.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Scale Puppeteer and Playwright scraping with compatible browsers, isolated contexts, bounded concurrency, honest stealth limits, and failure handling.
Get checkable answers from webpages with AI. Learn a repeatable workflow, prompts, verification steps, privacy checks, and a way to capture pages by API.
Compare Urlbox and CaptureKit by capture needs, integrations, and cost. See what the docs confirm, what to verify, and a third option: ScreenshotNeo.
Learn how to send an authenticated image-generation request, handle base64 image data, and save the result—without mistaking an API endpoint for a prompt-in-a-URL interface.
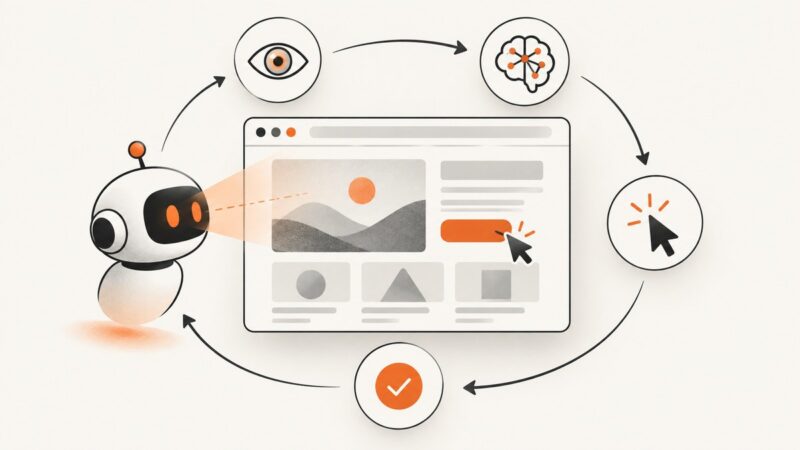
AI browser agents can navigate and act, but reliability depends on the execution loop, task, and safeguards. Here’s how the layers work and how to evaluate them.
Construction camera footage helps teams review progress, document changes, and revisit selected events. Here’s how to plan a useful, responsible capture setup.
A practical guide to connecting web agents safely, fixing production failures, and scaling browser automation with MCP, tracing, and human approval.
Compare eight MCP servers for Claude Code by task fit, permissions, data access, and security. Start small and review every write-capable tool.
Understand browser-agent loops, automation choices, reliability limits, security safeguards, and practical deployment patterns for real web tasks.
Learn how structured data can make pages eligible for Google's rich results, with implementation examples, validation steps, and realistic SEO expectations.
Use website screenshots to make scope clear, prove visual changes, improve QA, and give clients useful evidence they can act on.
Build a reliable sitemap crawler that extracts, renders, audits, and exports every page title and meta description across your site.
HTTP 520 means Cloudflare received an empty, unknown, or malformed origin response. Learn how to diagnose it without mistaking the status for a scraper ban.
Embed cover art in an MP4 with FFmpeg’s attached_pic stream, preserve video and audio, verify the result, and troubleshoot compatibility.
Learn how headless browsers work for AI agents, choose Playwright, Puppeteer, CI, or managed browsers, and scale reliable automation.
Compare Ansible, Puppet, Chef, Salt, CFEngine, and Rudder by architecture, governance, testing, and operational overhead—and learn when Terraform belongs alongside them.
Build an AI web scraper with Browser MCP or Browserless BQL. Learn architecture, setup, extraction, validation, retries, and production troubleshooting.
Compare four Urlbox alternatives by input, output, browser controls, resilience, and price. Find the right screenshot API for your workload.