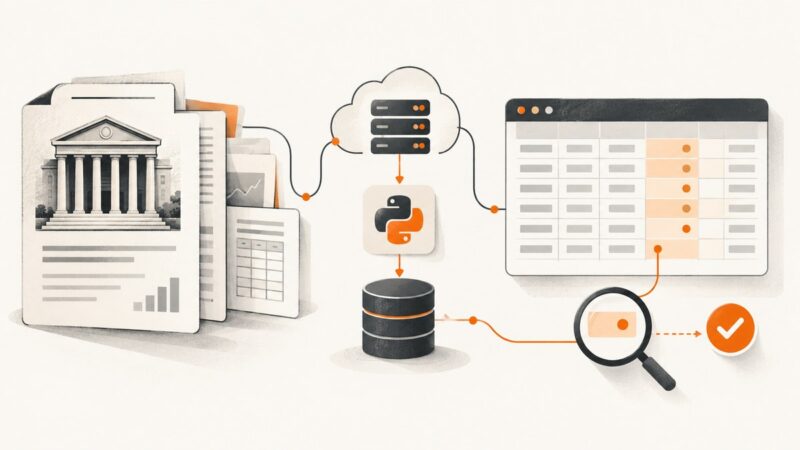
How to Scrape Financial Statements with Python: A Practical Guide for Beginners
Use SEC EDGAR’s free APIs and pandas to collect financial statement data, choose the right filing facts, and keep every number traceable.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Use SEC EDGAR’s free APIs and pandas to collect financial statement data, choose the right filing facts, and keep every number traceable.
Compare Oxylabs and Bright Data by proxy type, scraping workflow, pricing, compliance, and total cost before choosing a provider.
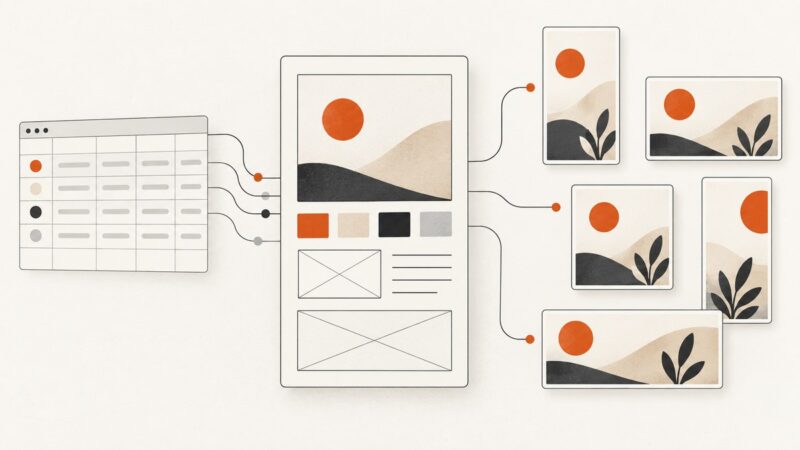
Learn how to design reusable marketing templates, connect campaign data, automate image generation, and choose the right workflow for your team.
Build reusable design templates and turn spreadsheet rows into consistent visual variations. Compare Canva and Adobe Express workflows, limits, and practical setup.
Learn how hosted browser services work—and why Zomato scraping requires written authorization or an approved API relationship first.
Learn Node.js web scraping with fetch and Cheerio, know when to use Playwright, handle errors responsibly, and save reliable records.
Build a real estate data pipeline around permission, licensed sources, reliable extraction, and careful validation. Includes a runnable Python example for authorized HTML.
Inject JavaScript before or after a page loads, wait for async content, then capture a reliable screenshot or PDF with Playwright, Puppeteer, or a hosted API.
Build repeatable creative workflows in n8n by connecting triggers, APIs, AI services, review steps and publishing tools.
PDFs and web pages use different units, zoom controls, and display scaling. Learn why the same text looks different and how to compare it fairly.
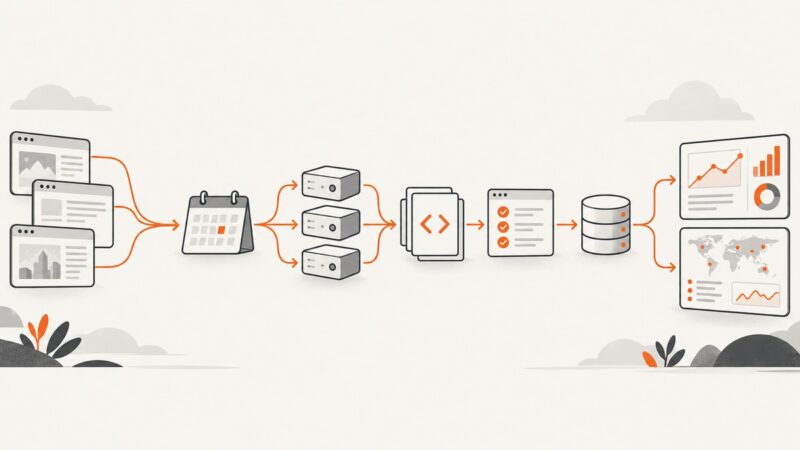
Design a reliable scraping pipeline with scheduling, parsing, storage, retries, browser rendering, observability, and practical Scrapy code.
Federated GraphQL combines independently owned GraphQL services into one API. Learn how subgraphs, entities, composition, and query planning fit together.
Learn how Python supports defensive security work, where automation helps, how to write safer scripts, and why automated checks need human review.
Learn BeautifulSoup find_all class, find, and CSS selectors with runnable Python examples, edge cases, debugging tips, and production guidance.
Data parsing turns raw text into structured values your software can validate, transform, query, and store. Learn formats, code, ETL, errors, and best practices.
Understand BrainpoolP256r1 support in TLS 1.2 and 1.3, what its security status means, and how to check your exact TLS implementation.
Wait for the element or page state that makes a screenshot useful—not just for navigation to finish. Runnable Puppeteer, Playwright, Selenium, cURL, Python, and Node.js examples included.
Choose a browser automation framework, build a reliable first workflow, and avoid brittle tests with practical Selenium, Playwright, and Puppeteer guidance.