How to Scrape Facebook Without Getting Blocked
Learn the permission-first way to collect Facebook data, handle rate limits, and avoid violations instead of chasing unreliable evasion tricks.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Learn the permission-first way to collect Facebook data, handle rate limits, and avoid violations instead of chasing unreliable evasion tricks.
Configure VS Code as a project workbench: workspaces, extensions, tasks, debugging, tests, source control, remote development, and trust.
Learn where creative automation helps, how to build a reviewable workflow, and how to keep brand, rights, and quality checks in the loop.
Choose the right reuse pattern for flowing layouts, static artwork, fillable forms, and data-driven PDFs, then build and validate it with practical examples.
Learn a reliable Beautiful Soup workflow: fetch HTML, choose a parser, extract data, handle failures, and capture JavaScript pages when needed.
For video details, Bilibili’s documented route is its authorized Open Platform API—not an unrestricted public-page scraper. Learn the access requirements, signing workflow, runnable examples, and safe alternatives.
Realtor.com prohibits scraping without written permission. Learn the compliant API path, technical workflow, failure handling, and screenshot options.
Learn the lawful ways to collect Zillow data at scale, from approved APIs and metrics downloads to reliable ingestion architecture.
Extract webpage data with plain-language instructions, then make results dependable with schemas, validation, and provenance. Includes runnable code and workflow guidance.
Build a Python MCP server with typed tools, resources, prompts, local tests, and a secure Streamable HTTP deployment using the official SDK.
Use Playwright routes to block images, fonts, scripts, or other requests in Python. Choose page or context scope and handle service workers and caching deliberately.
BBC Sport discourages scraping. Learn the permitted alternatives: RSS, permission-based access, and safe page capture for authorized use.
Learn how to collect structured web data with Python, clean it, and analyze it—with practical code, crawl controls, and troubleshooting.
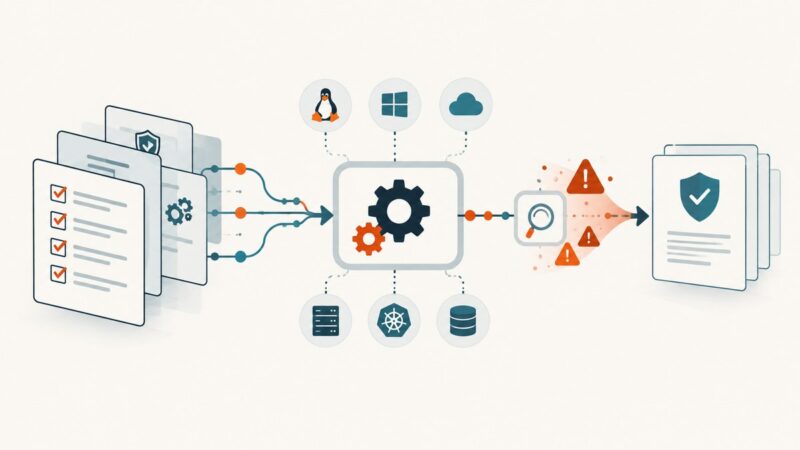
SCAP is a framework of standards for exchanging and assessing security configuration and vulnerability information. Learn its components, current version, validation limits and practical use.
Learn what Cloudflare Workers can run, how bindings connect data and services, deployment patterns, limits, pricing, and automation options.
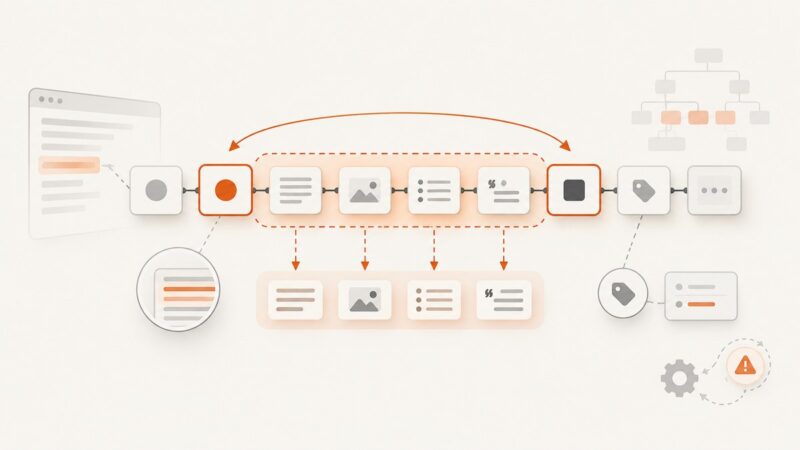
Use Cheerio’s nextUntil() to collect sibling values between two nodes, with examples for text, attributes, reverse ranges, parsing, and troubleshooting.
Template elements that can change dynamically include text, images, reusable blocks, styles and conditional sections. The exact options depend on the platform and how it renders data.
Bath & Body Works’ U.S. terms prohibit scraping. Learn what is allowed, how to request authorization, and safer ways to handle product-page research.