The Best Financial Data Providers in the World: How to Build Your Own Datasets
Compare financial data providers by coverage, latency, history and licensing, then build a reproducible dataset with revisions, lineage and quality checks.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Compare financial data providers by coverage, latency, history and licensing, then build a reproducible dataset with revisions, lineage and quality checks.
Build reusable image templates with fixed HTML/CSS layouts, variable content, and reliable browser rendering. Includes runnable code, validation, and troubleshooting.
Learn how to batch-render URL lists as images, PDFs, or scrolling videos with browser automation, APIs, retries, and reliable file handling.
Collect Stack Exchange questions reliably with the official API. Learn search, tags, pagination, throttling, attribution, and when HTML scraping makes sense.
Style generated PDFs by page, content, and position with CSS paged media. A practical WeasyPrint guide to page rules, headers, breaks, and debugging.
Build reusable financial report visuals that refresh with your data, from Excel and PowerPoint layouts to generated images and connected charts.
Compare Node.js, Deno, and Bun on compatibility, TypeScript, security, tooling, and performance, then choose with a workload-specific test plan.
Gate PDF.js conversion on a successful document load, preserve the original error, and diagnose bytes, workers, versions, CORS, and memory safely.
Generate or source images in batches, then populate Webflow CMS image fields reliably with CSV imports or the CMS API.
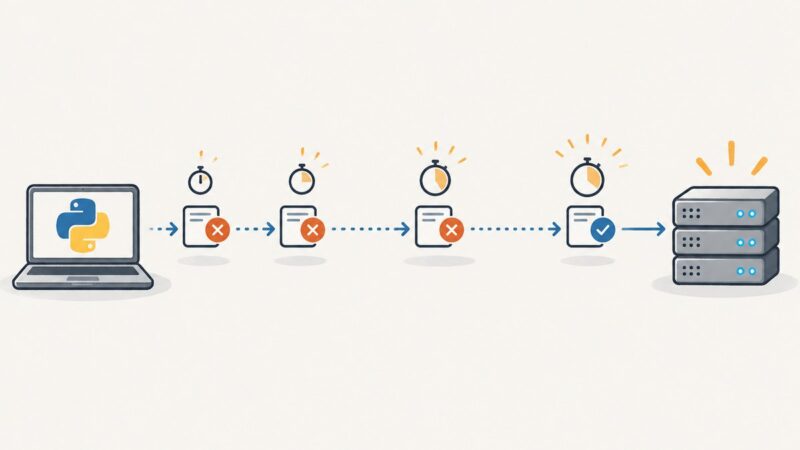
Add bounded retries to Python requests with urllib3 Retry, exponential backoff, jitter, timeouts, and safe handling for HTTP 429 and 5xx responses.
What Marriott’s 2026 terms allow, how to check rates responsibly, why results change, and how to capture authorized pages without browser setup.
Learn a reliable PHP scraping pipeline: fetch HTML, parse it with DOMXPath or DomCrawler, handle failures, and know when JavaScript needs a browser.
Use ChatGPT to design a scraper, run network code safely outside Data Analysis, validate results, and automate clean screenshots when needed.
Configure Chrome downloads, wait for completion, verify files, and troubleshoot PDFs, authentication, timeouts, and browser-version differences in Puppeteer.
Design reliable automations that keep people involved at the decisions that matter, without making every task wait for approval.
Change DNS servers safely on Windows, macOS, and Linux, benchmark locally, use encrypted DNS, and know when a resolver change will not help.
Build a production MCP server in Python or TypeScript, choose the right transport, secure it, and deploy stateless Streamable HTTP.
Compare managed stealth browsers, self-managed automation and scraping APIs by workload. Learn what vendor claims mean and how to choose for your authorized use case.