Defining a Time Limit in C# with HttpClient
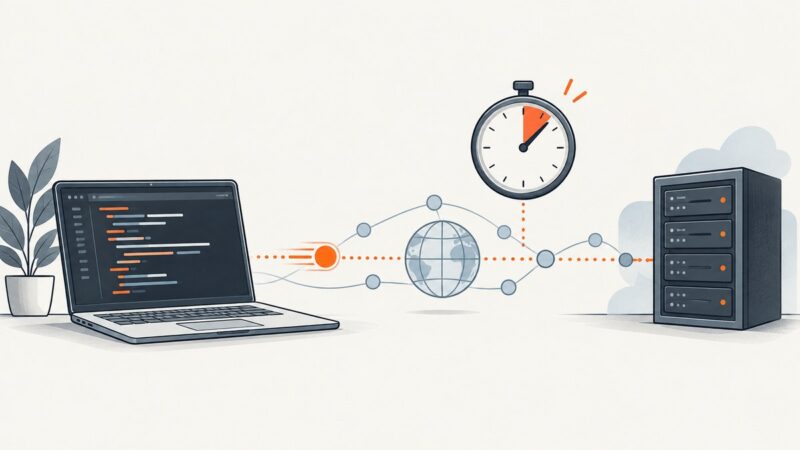
Set an overall HttpClient timeout or a deadline for one request, distinguish timeout from caller cancellation, and account for DNS and connection limits.
Set an overall HttpClient timeout or a deadline for one request, distinguish timeout from caller cancellation, and account for DNS and connection limits.
Use Temu’s authorized Partner Platform API for product, inventory, order and logistics data, with regional endpoints, signed requests and compliance guidance.
Build a configurable scraper API with HTTP and browser workers, schema-based extraction, domain-aware scheduling, and reliable job results.
Diagnose blank images, missing CSS, redirects, and other screenshot differences after a site move with a repeatable browser and command-line workflow.
Use Walmart’s authorized Marketplace APIs for catalog search, pagination, and reliable result handling—and understand the limits of consumer-page scraping.
Learn how to switch a website to dark or light mode, capture the visible area or full page, and automate clean screenshots with ScreenshotNeo.
Keep Scrapy’s spider and parsing workflow while routing downloads through a web scraping API. Configure Zyte API, handle binary responses, and troubleshoot common integration issues.
Download an image with HttpClient, add a text or image watermark in memory, and save the result with platform and large-file guidance.
Find the timeout layer, fix readiness and navigation issues, retry safely, and choose synchronous or webhook captures without guesswork.
Build and deploy a Firebase API with HTTPS Cloud Functions, callable functions, or direct REST. Includes runnable code, authentication, emulator testing, and troubleshooting.
Learn the safe, repeatable way to collect Tokopedia data with seller APIs, structured data services, or crawling APIs.
Learn when to call an AJAX endpoint directly, when to use Playwright, and how to wait for and validate JavaScript-loaded data in Python.
Learn a careful Python workflow for extracting Bike24 product details, inspecting markup, handling robots.txt, and avoiding brittle or abusive crawlers.
Find and fetch a site’s real favicon, including icons declared in HTML, CDN-hosted files, and the /favicon.ico fallback—with runnable code and CORS guidance.
Learn how Selenium and Beautiful Soup fit together to inspect rendered flight pages, extract fields carefully, and handle access, markup, and data-quality limits.
Find WordPress pages with no internal links, confirm why they are not indexed, and choose the right fix with seven practical tools.
Build a reliable web-data aggregator with source selection, crawling rules, normalization, provenance, APIs, monitoring, and runnable code.
Build a secure aiohttp webhook endpoint with JSON parsing, GitHub signature verification, idempotency, retries, testing, and production deployment guidance.