How to Generate Open Graph Images in Deno
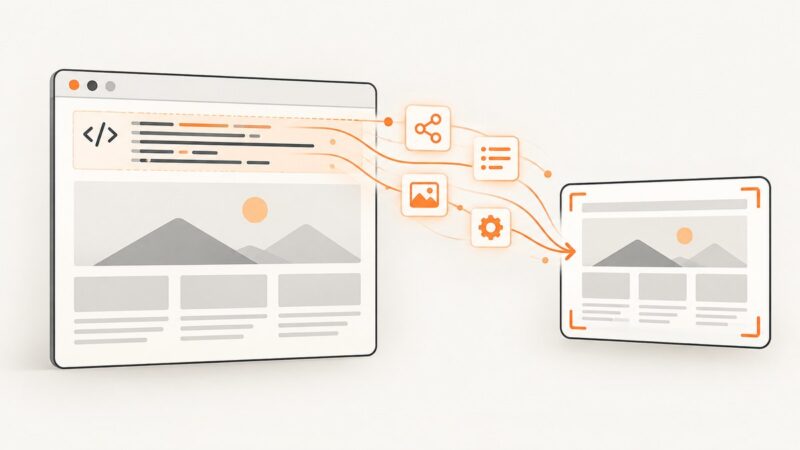
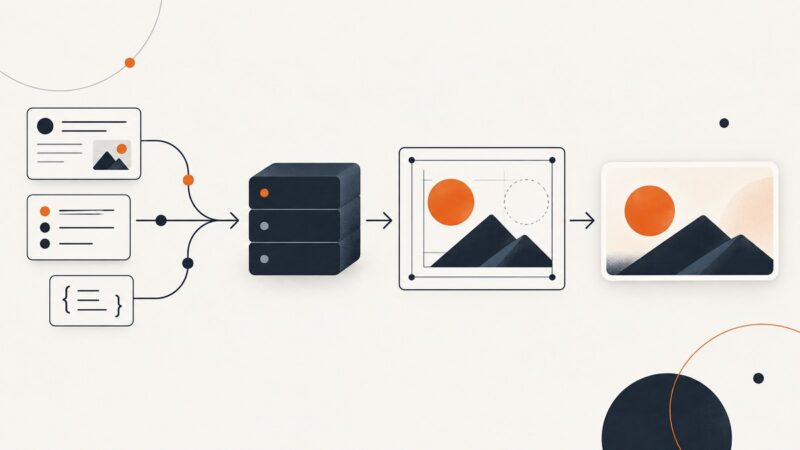
Generate dynamic Open Graph images in Deno with Satori and Resvg, including fonts, caching, deployment, troubleshooting, and complete code.
Puppeteer, Playwright, Selenium and headless Chrome, and what they take to run well.
Generate dynamic Open Graph images in Deno with Satori and Resvg, including fonts, caching, deployment, troubleshooting, and complete code.
Learn what IP, TCP, UDP, HTTP, HTTPS, DNS, SMTP, IMAP, FTP and SSH do, how they work together, and when to use each.
Generate a PDF in Go, encrypt it with AES-256 using pdfcpu, set permissions safely, and stream the protected file without exposing plaintext.
Learn why screenshots use fallback fonts, how WOFF and WOFF2 differ, and how to wait for web fonts before capturing pages.
Build a reliable SEC filings scraper with clean, traceable JSON using public SEC APIs, filing archives, and practical parsing patterns.
Neither IPv4 nor IPv6 is always faster. Compare both paths to the same destination and weigh latency, reliability, setup time, throughput, and jitter.
Build bounded, cancelable retries in Go without duplicating writes, losing request bodies, or amplifying an outage.
Learn how TLS cipher suites are negotiated, how they affect scraper compatibility and fingerprints, and how to diagnose HTTPS failures safely.
Choose between Guzzle, Symfony HttpClient and PSR-18 by matching the client to your app, workload and integration needs. Then keep its dependencies secure and testable.
Web scraping is shifting toward managed pipelines, AI-assisted extraction, and purpose-based access rules. Here’s how to plan for reliability, cost, and governance.
Use Playwright to render pages, extract ordered Open Graph metadata, and save viewport, full-page, or element screenshots reliably.
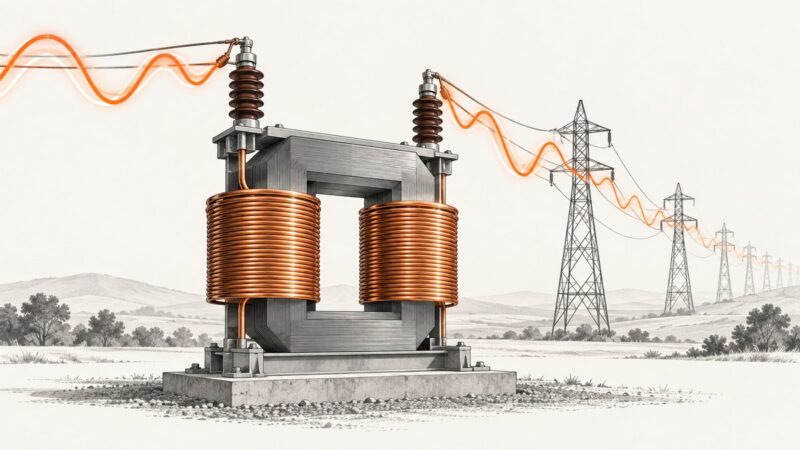
Learn what an electrical transformer does, how magnetic induction transfers AC energy, and why grids step voltage up and down.
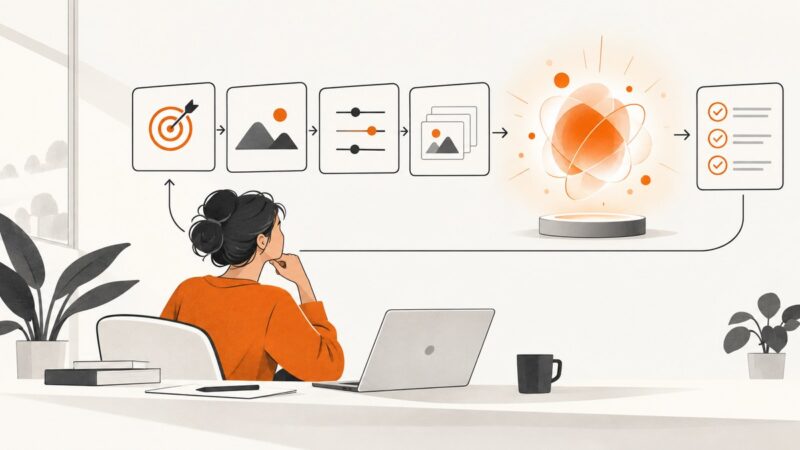
Learn prompt engineering with practical examples, an iteration workflow, evaluation methods, model-specific guidance, and production checklists.
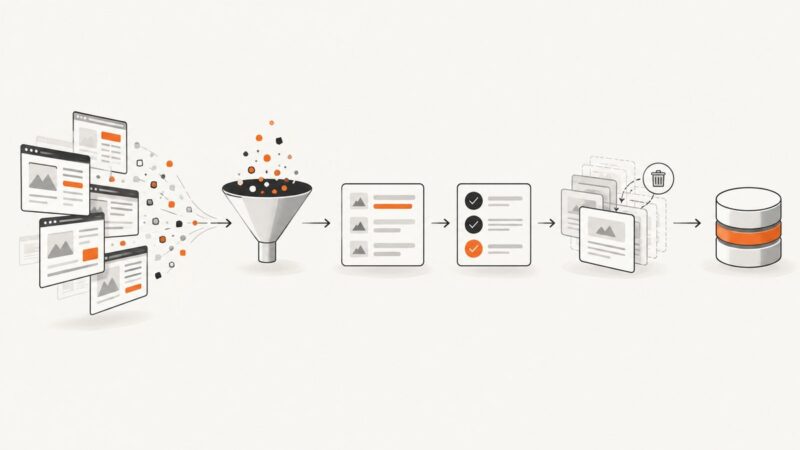
Build a reliable scraping pipeline that normalizes, validates, deduplicates, stores, and monitors records without losing source context.
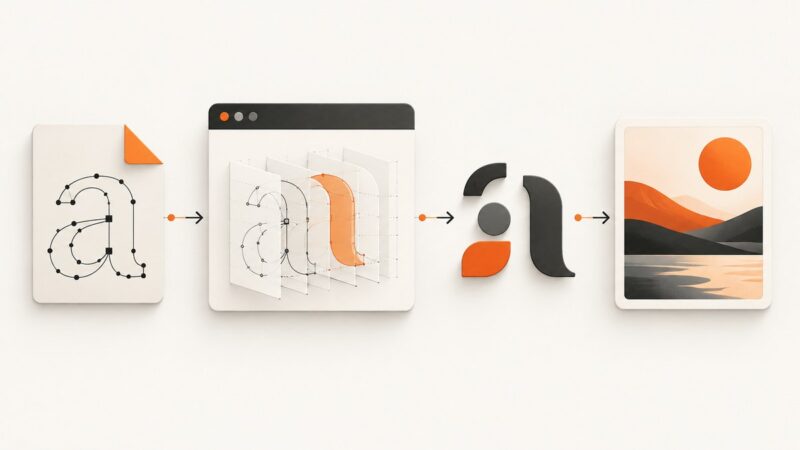
Learn how fonts load, shape, and rasterize in screenshots and canvas—and how to make custom typography deterministic.
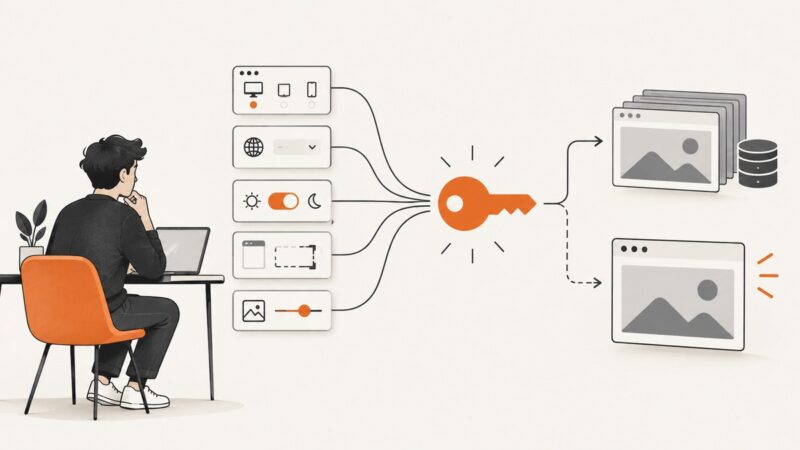
Build screenshot cache keys from every input that can change the rendered output. Learn how to version, refresh, and troubleshoot screenshot caches across providers.
Measure TTFB in your browser, terminal, Python, or Node.js, understand every timing phase, and interpret results without mistaking TTFB for full page speed.
Crawl4AI’s recent releases show why PDF downloads need their own security controls—and how to operate a self-hosted crawler more safely.