How to Receive PDF Generation Webhooks in Go
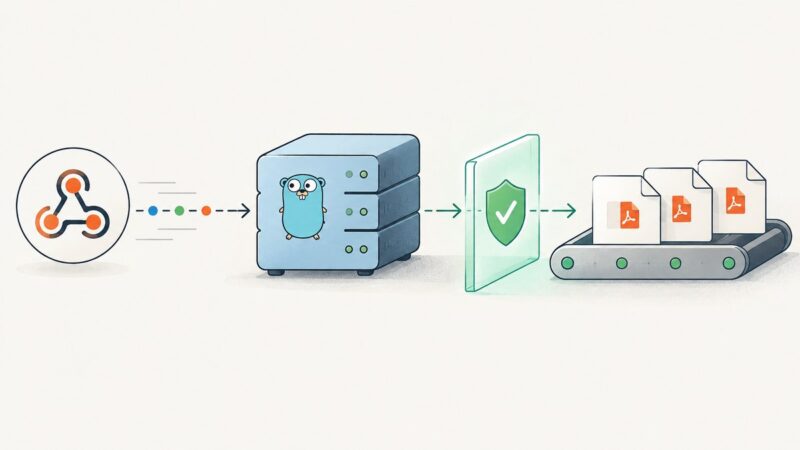
Build a Go webhook endpoint that verifies signatures, deduplicates retries, and queues PDF work before acknowledging delivery.
Build a Go webhook endpoint that verifies signatures, deduplicates retries, and queues PDF work before acknowledging delivery.
Configure a proxy in Screaming Frog SEO Spider, fix certificate and crawl errors, understand routing limits, and choose the right workflow.
Gumtree prohibits automated collection without express written permission. Here’s how to plan an authorized listings dataset and handle prices, locations, and personal data responsibly.
Find favicon links in HTML and web app manifests, resolve their URLs correctly, and return candidates with the metadata and fetch status developers need.
Learn to fill inputs, select options, handle checkboxes, submit forms, wait for results, and troubleshoot Puppeteer automation.
Capture a long webpage as one image for free. Use built-in Firefox and Edge tools, Firefox DevTools, or a carefully chosen extension.
Learn what Facebook permits, how to research group posts safely, and how to process authorized exports without brittle scraping.
Learn how to fetch a page, test CSS and XPath extractors, and diagnose missing or changing data with Scrapy, browser tools, and repeatable checks.
KAYAK prohibits automated scraping without written permission. Here are the authorized ways to track fares and build a flight-price project.
Facebook still shows an old WordPress image? Trace the live og:image, fix the winning setting, clear the right caches, and scrape the exact URL again.
Change curl’s User-Agent for a browser-like HTTP request, or use curl-impersonate when you need browser-style headers and TLS behavior.
Learn how to extract text from photos, screenshots, scans, and image-only PDFs with desktop tools, OCR APIs, automation, and reliable workflows.
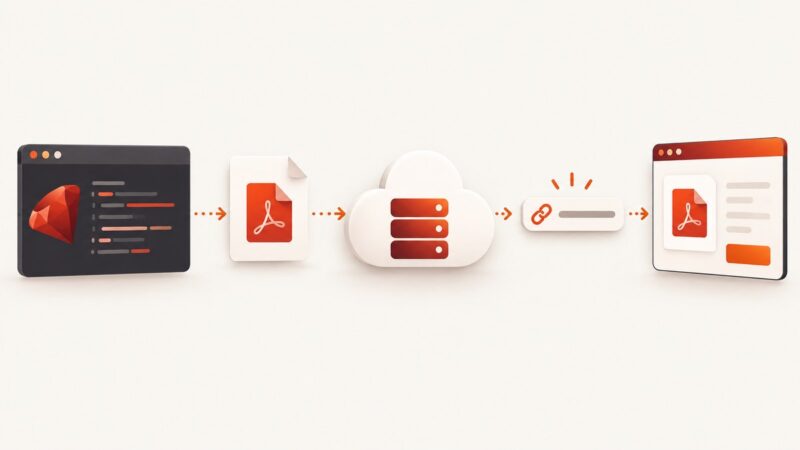
Generate a PDF in Ruby, store it safely, and return a usable URL with Prawn, PDFKit, Wicked PDF, or Rails Active Storage.
Extract every sitemap URL from robots.txt, recursively crawl sitemap indexes, and export a complete, auditable URL inventory.
Fix missing og:image tags with a reliable fallback order, server-rendered metadata, runnable examples, and a checklist for validating link previews.
Upload your generated PDF, set the right access permissions, and test the share link. Includes Google Drive and Dropbox workflows, plus an API pattern for automation.
Learn how to find next and previous sibling elements in PHP with DOMDocument, safe node filtering, XPath, PHP 8.4 notes, and fixes for whitespace surprises.
Learn when to use canvas, html2canvas, or headless Chromium to export HTML as accurate images and PDFs, with runnable code and troubleshooting.