Where Java Saves Screenshots and How to Find Them
Java does not choose a screenshot folder. Learn how Robot captures pixels, how ImageIO writes them, and how to locate every output reliably.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Java does not choose a screenshot folder. Learn how Robot captures pixels, how ImageIO writes them, and how to locate every output reliably.
Most websites cannot detect your OS screenshot. Learn what browsers, Android apps, DRM, and capture APIs can actually see.
Save one webpage as a PDF with your browser, capture linked pages in Acrobat, or automate URL-to-PDF conversion with code.
Find archived webpage captures, save a page with the Wayback Machine, understand replay gaps, and make a current screenshot when you need one.
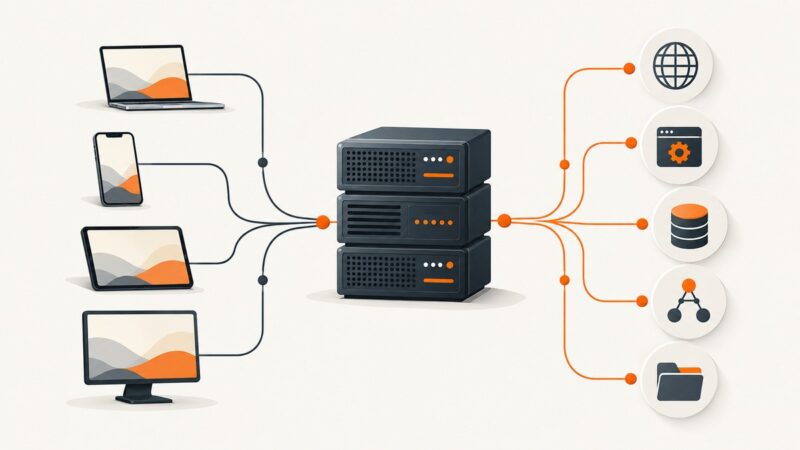
A server is a system that provides resources or services to clients. Learn how servers handle requests, how their roles differ, and what keeps them reliable.
Fix PDFInfoNotInstalledError by installing Poppler, correcting PATH visibility, and checking the runtime that actually runs your PDF code.
Save a Selenium screenshot as a PNG, capture one element, or return image bytes and base64. Includes runnable examples and fixes for common errors.
Learn when to capture the visible viewport, a page element, or the full page, with Firefox, Playwright, and Chrome DevTools examples.
Use macOS screencapture from Bash to capture screens, windows, regions, delayed shots, and repeatable images with reliable shell scripts.
Connect Claude Code to Playwright MCP, automate browsers, run headless, troubleshoot setup, and capture clean screenshots with ScreenshotNeo.
Learn how BrowserStack Percy visual regression testing works, how to integrate it with CI, choose coverage, review diffs, and avoid noisy failures.
Capture a visible screen rectangle in C# with Graphics.CopyFromScreen, save it to an image, and handle coordinates, errors, and platform limits.
Compare browser extensions that save webpages as PDFs, understand local versus hosted conversion, and choose the right export method for your workflow.
Set up browser tools for web automation with VS Code, Chrome DevTools MCP, or Playwright MCP, then verify workflows and handle browser access safely.
Extract the archive, preserve its assets, and convert the entry HTML file with a browser, Chrome Headless, Playwright, or ScreenshotNeo.
A .html download usually means the server returned a web page, not PDF data. Learn how to verify the response and fix browser and server causes.
Capture the visible screen or an entire webpage in Chrome, Firefox, Edge, or Safari on iPhone. Choose an image or PDF, and troubleshoot common capture issues.
Scrapy is the strongest default for repeatable crawls, but the best Python scraping framework depends on page type, scale, and JavaScript needs.