How to Convert Every Page on a Website to Markdown
Learn how to crawl an entire website, extract clean content, and save every page as reliable Markdown for search, LLMs, and knowledge bases.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
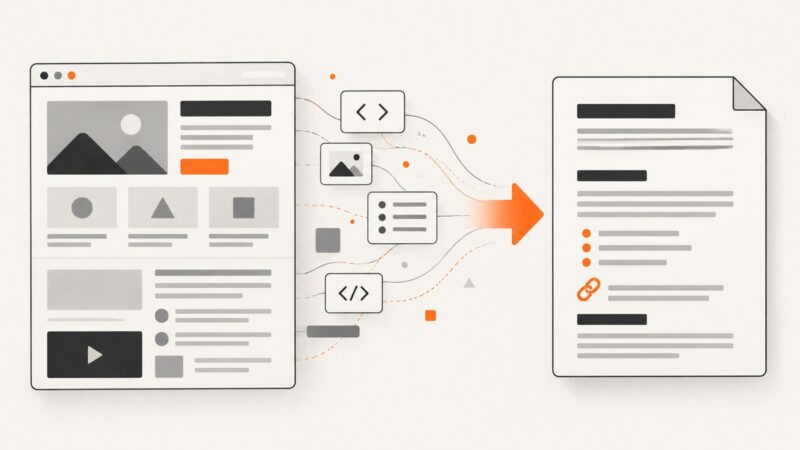
Learn how to crawl an entire website, extract clean content, and save every page as reliable Markdown for search, LLMs, and knowledge bases.
Generate image bytes, store them privately, and issue short-lived signed URLs for secure display or uploads.
Package Playwright and its matching Chromium in a Lambda container, configure resources, and troubleshoot deployment issues.
Convert an HTML file with Pandoc, or turn an HTML string into Markdown with JavaScript or Python. Choose options for your Markdown flavor and inspect structures that do not map cleanly.
A practical Black Friday 2026 checklist for retailers and marketplace sellers: plan credible offers, protect stock and margins, prepare your store, and measure results.
Find the nearest Wayback Machine capture to a target date with the Availability API or CDX, then verify the replay and its assets.
Design a safe LangChain web-crawling pipeline from URL discovery to clean, traceable chunks, embeddings, refreshes, and retrieval.
Connect LangChain to Playwright or computer-use workflows, choose the right control model, and secure browser agents before exposing them to users.
Collect image URLs from a rendered page with Puppeteer, then download and validate the original files in Node.js. Learn how to handle lazy loading, failures, and screenshots.
Learn what an MCP server does, how tools, resources and prompts work, and how to build, secure and connect one to AI clients.
Compare Playwright, Selenium, Cypress, Puppeteer and hosted browser services. Choose the right tool by browser coverage, language, debugging and scale.
Control emoji artwork in Puppeteer by pinning fonts, browsers, CSS, and runtime environments for repeatable local and CI screenshots.
Control print CSS, page geometry, breaks, and PDF rendering so HTML documents paginate predictably in browsers and automation.
Learn how to preview Google Search layouts, capture reproducible website screenshots, and automate clean previews with Playwright or ScreenshotNeo.
Build a reliable AI scraper without code: choose a tool, extract fields, handle dynamic pages, validate results, and automate exports.
Measure browser TTFB and page load time, then run repeatable synthetic tests from a chosen country. Compare the two methods with clear metrics and runnable code.
Create a readable event banner for each social destination, and choose whether its countdown should be fixed, animated, or truly time-updating.
Learn how Cline plans and executes coding tasks across your editor, terminal and browser, with model choices, approvals, costs and privacy explained.