How to Configure Nginx to Serve Static Files for Node.js
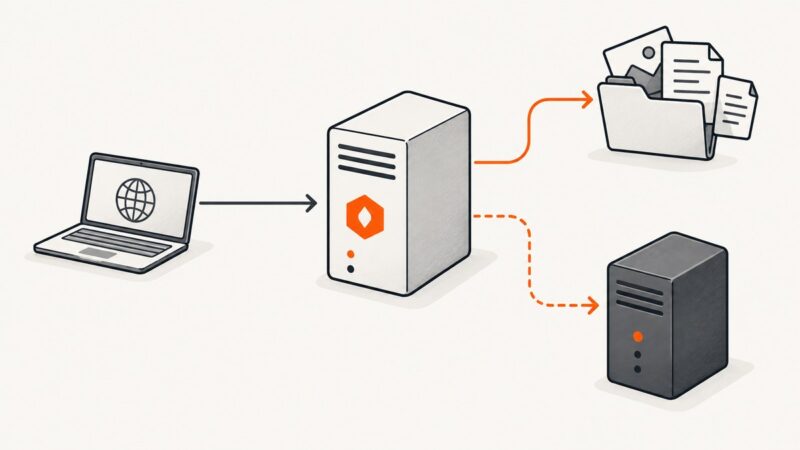
Configure Nginx to serve Node.js static files directly, proxy dynamic routes correctly, and troubleshoot root, alias, try_files, and proxy_pass.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Configure Nginx to serve Node.js static files directly, proxy dynamic routes correctly, and troubleshoot root, alias, try_files, and proxy_pass.
Track federal opportunities and awards with permitted APIs, scheduled refreshes, normalization, deduplication, alerts, and audit trails.
Learn how fonts load, shape, and rasterize in screenshots and canvas—and how to make custom typography deterministic.
Send scraped data to Google Sheets with Apps Script, the Sheets API, or CSV imports. Learn how to authenticate, append rows, prevent duplicates, and handle errors.
Learn authorized ways to extract data from login-protected pages with APIs, Playwright authentication, dynamic-content discovery, security, and troubleshooting.
Use Ferrum, Cuprite, or a hosted API to capture websites and render HTML as PNG, JPEG, WebP, or PDF from Ruby.
Capture a rendered website in Deno with Astral, scoped permissions, full-page options, troubleshooting, and a managed ScreenshotNeo alternative.
A practical workflow for using website screenshots in marketing: check permissions, preserve context, clear third-party content, and publish accessibly.
Learn the exact SQL pattern for foreign keys, safe migrations, cascading actions, indexing, and differences between PostgreSQL, MySQL, SQL Server, and SQLite.
A practical guide to discovering, politely crawling, and extracting corporate blogs, news, and resource pages with Python—while respecting site rules and privacy.
Extract Camping Wagner product data reliably with JSON-LD parsing, browser automation, retries, caching, and a production-ready Python scraper.
Learn how Docker Swarm works, deploy services safely, design manager quorum, configure networking and secrets, and choose Swarm, Compose or Kubernetes.
Capture everything below the fold with Firefox or Playwright. Learn which method fits, how to automate it, and how to troubleshoot long or dynamic pages.
Choose the right web view for your app, load a page safely, handle navigation, and know when an iframe or in-app browser is a better fit.
Capterra’s terms prohibit automated extraction without prior written consent. Learn what that means and which official access and reuse options are available.
Capture website screenshots in Kotlin with Selenium or Playwright, including full pages, elements, PNG output, troubleshooting, and an API alternative.
Convert modern, JavaScript-heavy web pages to PDF in Rust with headless Chrome, html2pdf, wkhtmltopdf, and a hosted API.
Render a consistent 1200×630 Open Graph image in Ruby with Grover, Ferrum, or a hosted API, then publish it through og:image.