Browserless Scraping and API Skills for AI Agents
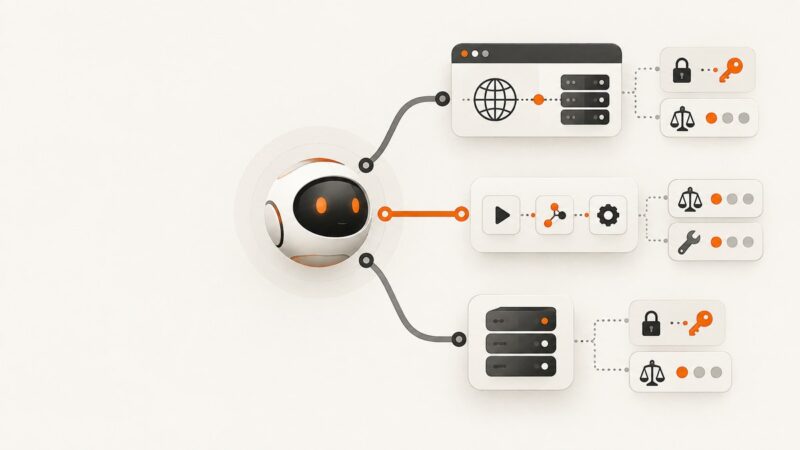
Choose Browserless MCP, Agent Run, or direct APIs for your AI agent. Learn the setup, authentication, tradeoffs, and failure fixes.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Choose Browserless MCP, Agent Run, or direct APIs for your AI agent. Learn the setup, authentication, tradeoffs, and failure fixes.
Learn how browser agents plan and act, where they work today, and how to build safer workflows with human approval and reliable observations.
Capture Cypress screenshots on demand or on failure, record videos in headless runs, and keep local or Cypress Cloud artifacts organized.
Learn how screenshot APIs turn a URL into an image, handle dynamic pages, and compare options for reliable production capture.
Create, edit, extract, OCR, and automate PDFs in Python with a practical stack using ReportLab, pypdf, PyMuPDF, pdfplumber, and Tesseract.
Capture a screen on Windows, Mac, iPhone, or Android, then save it as a PDF with the right quality and layout.
Choose a visual builder for managed editing and publishing, or a code template for file-level control. Compare portability, skills, licensing, maintenance, and cost before you commit.
Learn when to call a hidden data endpoint, when to parse embedded state, and when a headless browser is justified for JavaScript-heavy sites.
A permission-first guide to collecting Imovelweb data responsibly, handling blocks, and choosing an authorized screenshot workflow.
Compare binary Protobuf, ProtoJSON, and JSON by performance, compatibility, evolution, tooling, and practical API trade-offs.
Find a JA4 fingerprint in the official database, understand every field, and use matches safely in detection workflows.
Learn viewport, element, and full-page screenshots with Playwright MCP, including filenames, formats, scale, snapshots, and reliable automation patterns.
Learn how to retrieve YouTube video and channel metadata with the official Data API, estimate quota, handle captions, and stay within YouTube’s policies.
Learn when to capture a full page versus change viewport height, with steps for Chrome, Firefox, iPhone, and a screenshot API.
Lowe’s terms restrict automated scraping. Learn the authorized catalog and API workflow for product, price, inventory, and location-aware data.
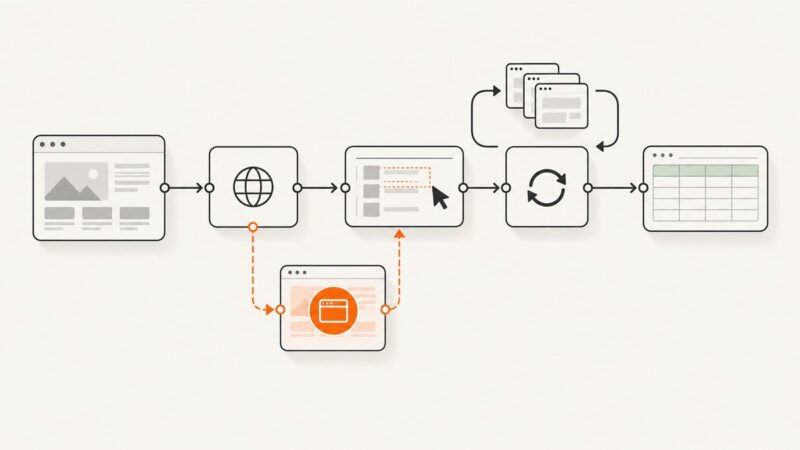
Build an inspectable n8n scraper with HTTP Request, CSS selectors, pagination, Google Sheets, and a browser-rendering fallback for JavaScript pages.
Compare instant data scrapers by setup, dynamic pages, pagination, integrations, output quality, and cost, then choose the right workflow.
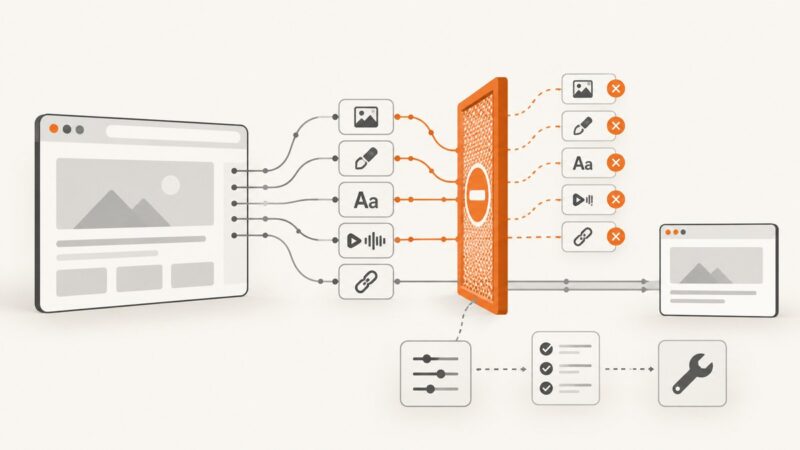
Block images, stylesheets, fonts, media, or specific URLs in Selenium with Python using Chrome’s DevTools Protocol. Learn how to configure, verify, and troubleshoot request blocking.