Proxy vs VPN Explained: Differences, Proxy Types, and Automation Use Cases
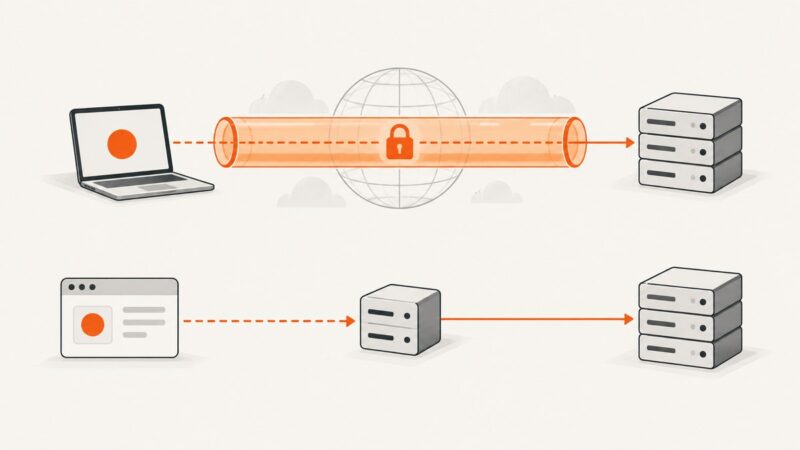
A proxy routes selected traffic; a VPN encrypts a broader device or network connection. Compare proxy types and choose safely for authorized automation.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
A proxy routes selected traffic; a VPN encrypts a broader device or network connection. Compare proxy types and choose safely for authorized automation.
Build reliable InvoiceBerry Zaps: choose triggers, map fields, prevent duplicates, troubleshoot failures, and capture clean screenshots.
Learn how to automate browser downloads reliably: capture Playwright download events, save files explicitly, validate results, and handle failures.
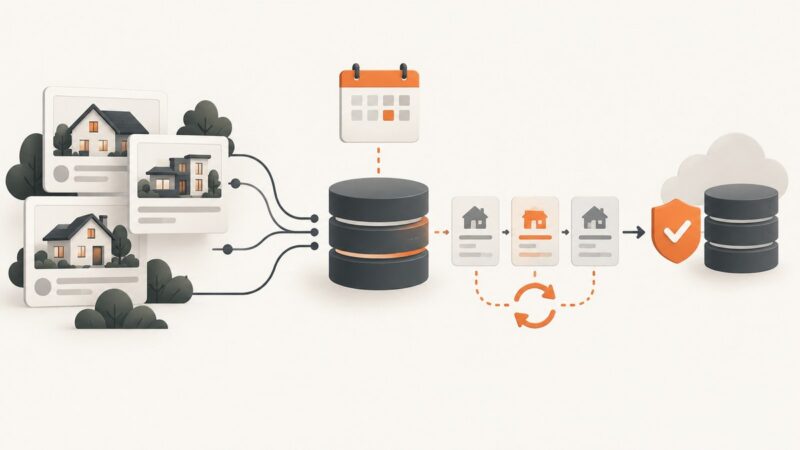
Build a reliable scheduled property-listing sync with authorized RESO Web API access, incremental updates, retries, and clear licensing checks.
Build a reliable Zapier workflow that turns prompts into images, stores them safely, applies brand rules, and sends finished assets where they belong.
Learn how to turn one branded design into hundreds of consistent web graphics using structured data, templates, APIs, and reliable rendering workflows.
Build a Workato recipe that creates documents from business data. Choose between a native Google Doc, rendered template output, document automation, and signature delivery.
Capture webpages on a schedule, HTTP request, or app event with Pipedream’s Playwright action, then save each image somewhere durable.
Learn reliable native HTML select automation with Selenium, Playwright, and Cypress, including multi-selects, verification, failures, and custom dropdowns.
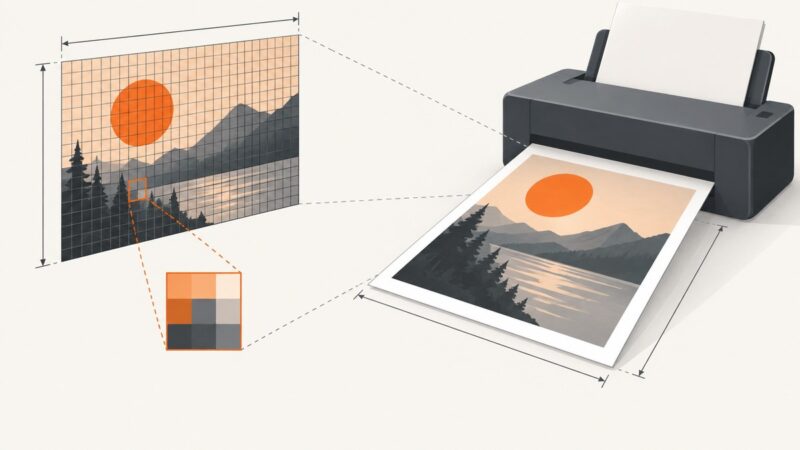
Image APIs set resolution in pixels, not DPI. Calculate the pixel dimensions your print needs, check provider limits, and set print density downstream.
Generate reliable invoice PDFs from login-protected URLs with Playwright, Puppeteer, direct HTTP, and ScreenshotNeo.
Learn when browser filing automation is allowed, how to build a reliable Playwright workflow, and how to verify receipts without risking an incomplete submission.
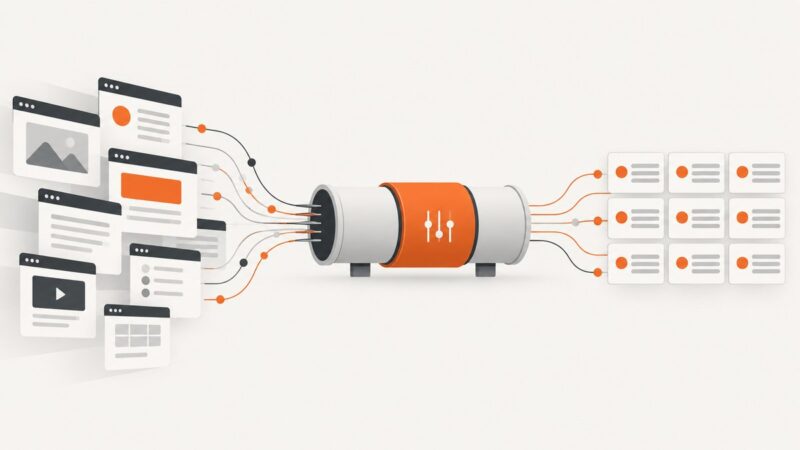
Learn how scraping APIs turn web pages into validated JSON, compare extraction methods and providers, and build a reliable collection pipeline.
Learn how to capture, stream, and embed browser automation replays, with runnable Browserless examples and guidance on formats, privacy, and troubleshooting.
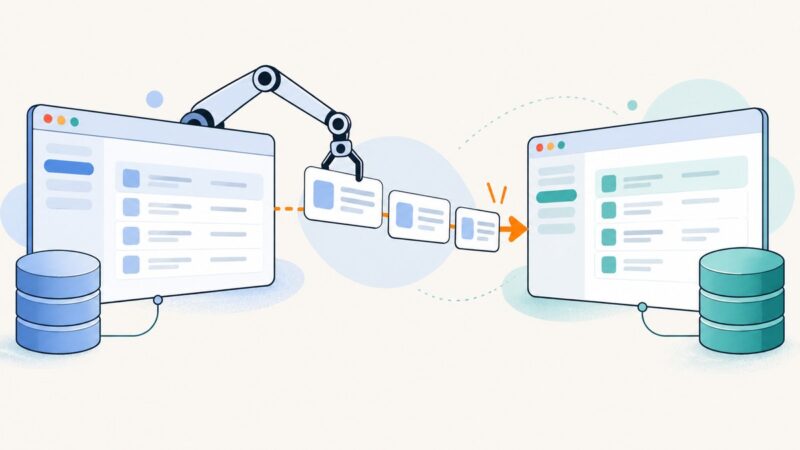
A practical guide to moving records through web interfaces with Selenium, Playwright, Puppeteer and Chrome automation—plus validation, security and retries.
Choose a bounded business task, select the right Python integration, and plan for permissions, errors, and safe retries before automating.
Build a repeatable market research pipeline with web scraping: choose sources, collect and validate data, handle risks, and keep results auditable.
Install Playwright, automate browsers with resilient locators, debug failures with traces, and decide when a screenshot API is simpler.