Convert HTML to WebP in C#
Render HTML in Playwright for faithful WebP screenshots, or encode existing pixels with SkiaSharp, ImageMagick, or libwebp.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Render HTML in Playwright for faithful WebP screenshots, or encode existing pixels with SkiaSharp, ImageMagick, or libwebp.
A careful, runnable guide to collecting Baidu results with validation, restrained requests, troubleshooting, and a screenshot workflow.
Learn a permission-aware Python workflow for collecting local business data from permitted pages and authorized APIs, with parsing, validation, and troubleshooting.
Configure Axios with an HTTP proxy, environment variables, or a custom agent. Learn how authentication, HTTPS tunneling, bypass rules, and Node versions affect the setup.
Learn three reliable CSS techniques for gradient borders, including rounded corners, fallbacks, debugging tips, and browser compatibility.
Build a recurring invoice collection workflow with browser RPA, direct downloads, file checks, and human review for portal changes and sign-in challenges.
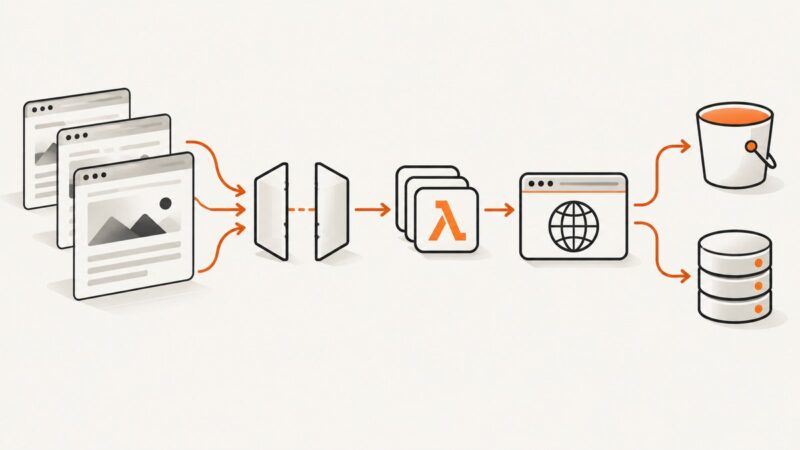
Build a reliable TypeScript scraper on AWS with Lambda, S3, DynamoDB, queues, and Playwright—plus a managed screenshot shortcut.
Build a repeatable workflow for podcast graphics and audiograms, from episode trigger to captions, branding, review, and publishing.
Scale compliant crawls across workers and proxies while keeping request rates, sessions, retries, and costs under control.
Detect headless browsers and scraping bots with layered signals, staged enforcement, and practical browser, request, TLS, and behavior checks.
Learn when to use a company-data API or bulk file, how to authenticate and normalize records, and how to keep extraction reliable and compliant.
Reduce proxy bandwidth by resizing, converting, compressing, and caching images. Learn when CSS stubbing helps, how to measure savings, and how to avoid broken pages.
Zillow prohibits automated scraping and CAPTCHA bypass. Learn the compliant API, licensing, and alternative-source workflow for property data.
Compare bulk screenshot tools, batch APIs, local automation, limits, costs, and a complete Playwright workflow for capturing URL lists reliably.
Build a reliable Node.js scraper with Axios and Cheerio, add browser rendering only when JavaScript requires it, and operate it safely at scale.
Build bounded, retry-safe web scrapers on AWS Lambda with Python or Java. Covers runtimes, packaging, limits, costs, retries, and browser alternatives.
Learn how to collect Best Buy prices, specifications, and store availability with the official API, reliable refreshes, and compliant fallbacks.
Goodreads restricts automated collection of its listings and reviews. Learn what its policies mean, how to seek authorized data, and how to handle ratings responsibly.