How to Run Bash Scripts from Python
Run Bash scripts safely from Python with subprocess, arguments, environment control, timeouts, output capture, troubleshooting, and production patterns.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Run Bash scripts safely from Python with subprocess, arguments, environment control, timeouts, output capture, troubleshooting, and production patterns.
Monitor storefront journeys and product-page changes with browser screenshots, semantic checks, and useful evidence for alerts.
Use webhooks when event-driven updates beat repeated API checks. Learn how to choose, secure, process, and troubleshoot them in reliable automation workflows.
Build a reliable Carrefour price and availability scraper that preserves store context, fulfillment mode, seller, promotions, and timestamps.
Compare the best proxy scrapers for browser automation in 2026, including proxy types, rotation, pricing, APIs, Playwright setup, and selection criteria.
Render structured invoice data into branded PNGs or PDFs with templates, browser automation, APIs, validation, and production-ready workflows.
Use Playwright or Puppeteer to hide volatile elements, adjust page styles, and capture a more consistent website screenshot.
Build a consent-aware pipeline that turns customer reviews into branded images with moderation, templates, APIs, and automatic publishing.
Automate website screenshots with Playwright or Puppeteer, choose full-page or element capture, and save PNG, JPEG, or WebP reliably.
Build recurring website screenshot Zaps with schedules, capture actions, storage, troubleshooting, and a browser-free ScreenshotNeo option.
Use Google’s documented reviews API first, then collect public Play pages carefully with pagination, policy checks, and reproducible exports.
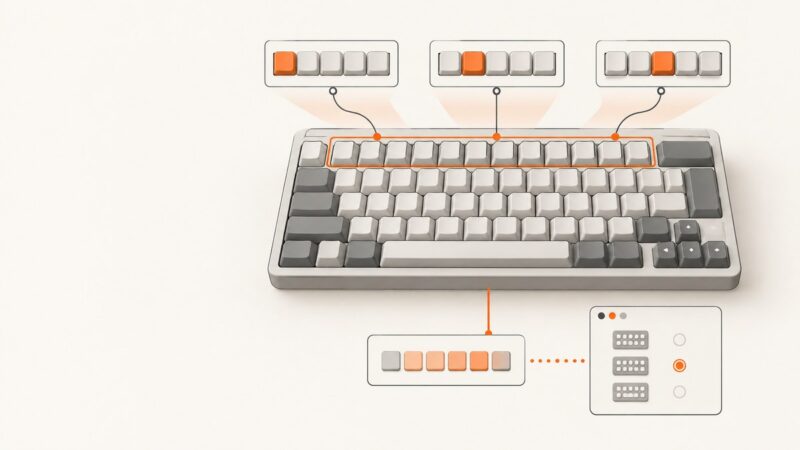
Identify QWERTY, AZERTY, or QWERTZ from the top letter row, then check what your computer actually types and which layout its settings have selected.
Choose between Crawlbase and AWS Lambda for scraping by matching retrieval, rendering, orchestration, runtime, cost, and maintenance needs.
Scrape SPA content reliably with Playwright: wait for the page state you need, extract from the rendered DOM, and handle dynamic lists and route changes.
Choose between a browser extension, a PAC script, or a provider-managed endpoint. Learn how to configure each, verify routing, and troubleshoot common failures.
Design extraction pipelines that recover from transient errors, corrupt workers, lost regions, duplicate writes, and CDC interruptions without losing data.
Build a repeatable video workflow from a spreadsheet row to a reviewed, rendered, and published video, with retries and status tracking.
Map URLs and dynamic screenshot settings in Zapier, handle API parameters correctly, and automate reliable captures with practical examples.