HTTP 422 Unprocessable Content: What It Means
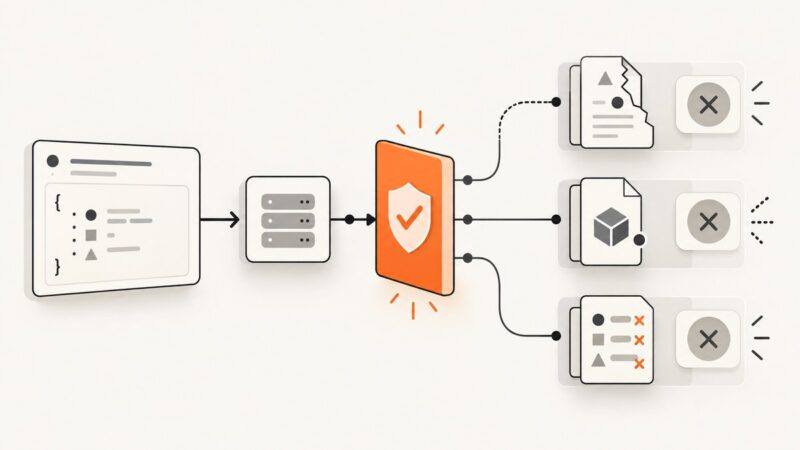
Understand HTTP 422, how it differs from 400 and 415, and how to diagnose validation failures in any API.
Puppeteer, Playwright, Selenium and headless Chrome, and what they take to run well.
Understand HTTP 422, how it differs from 400 and 415, and how to diagnose validation failures in any API.
HTTP 423 means a WebDAV resource is locked. Learn how to find the lock, submit its token, refresh or release it, and troubleshoot failed writes.
Trace every 301 and 302 hop, detect loops, inspect headers and timing, and automate redirect audits with a reliable API workflow.
Compare Python HTTP/2 libraries, learn when to use HTTPX, h2, python-hyper or curl_cffi, and verify which protocol your server negotiated.
Add reliable custom fields to metadata pipelines with clear schemas, scoped rules, rendered-page extraction, validation, and troubleshooting.
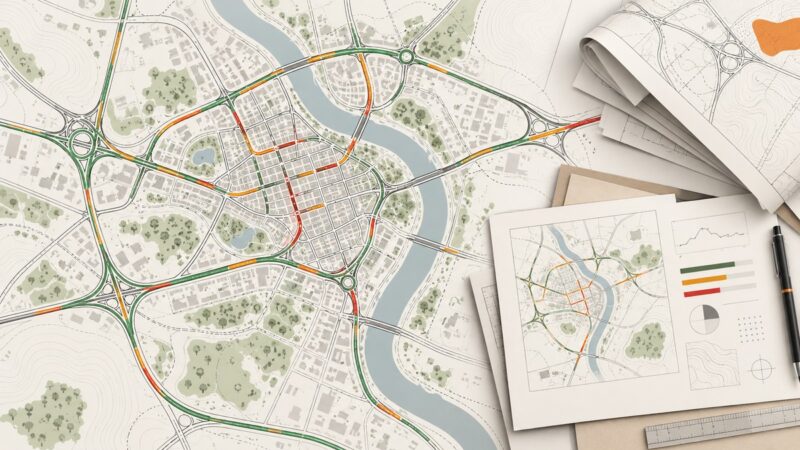
Learn what Google Maps traffic screenshots show, how to capture and document them, and when engineering decisions require structured traffic data.
Make Puppeteer screenshots faster by measuring each pipeline stage, reducing capture work, and tuning Chrome DevTools Protocol encoding.
Capture reliable browser screenshots with Puppeteer or Chrome DevTools Protocol, including surface, full-page, clipping, encoding, and troubleshooting.
Design and ship a reliable SaaS screenshot export: capture scope, formats, rendering consistency, Playwright code, operations, and API options.
A practical guide to running Headless Chrome safely in production: sandboxing, queues, capacity planning, failure isolation, and hosted alternatives.
Learn which screenshot settings affect output size, how to make Playwright captures repeatable, and what caching can—and cannot—prove about performance.
Build a repeatable Docker image for browser screenshots with Playwright, pinned dependencies, multi-stage builds, security controls, and production tips.
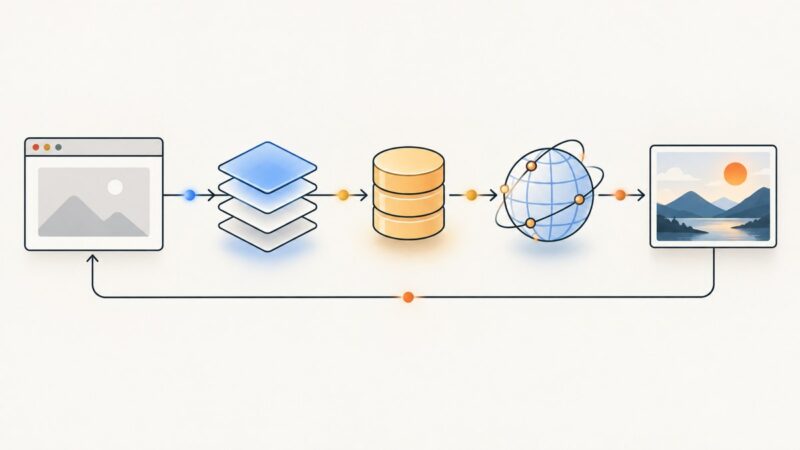
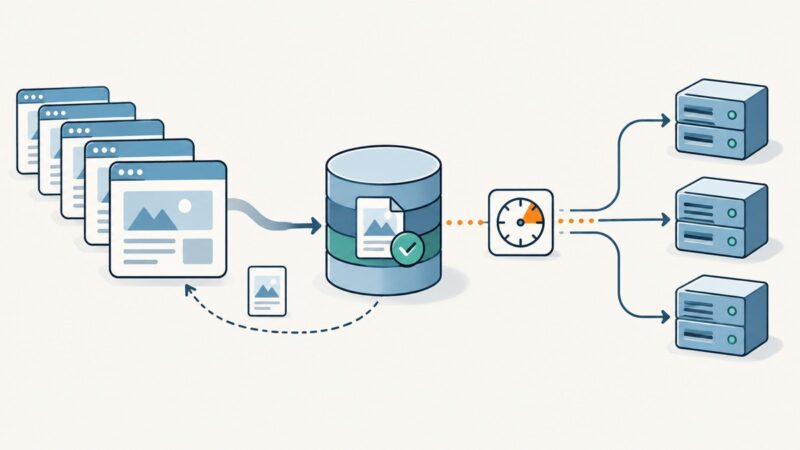
Design reliable screenshot API caches with complete keys, freshness controls, durable storage, HTTP delivery, billing, and troubleshooting.
Find slow browser tests with traces, stable waits, isolation, and measured concurrency. Includes Playwright workflows and a hosted screenshot path.
Build a reliable competitor tracker with scheduled snapshots, normalized data, field-level diffs, alerts, guardrails, and screenshots.
Use HTTP freshness rules, validators, and careful request pacing to cut repeated work while keeping extracted data current and crawls reliable.
Headless browsers rely on binaries, libraries, permissions, memory and lifecycle settings that differ between laptops and production. Here’s how to make those environments reproducible.
Chrome extension isolated worlds separate JavaScript environments, but share the page DOM. Learn what that changes, what remains visible, and how to test it.