Web Scraping and Browser Automation with Crawlee
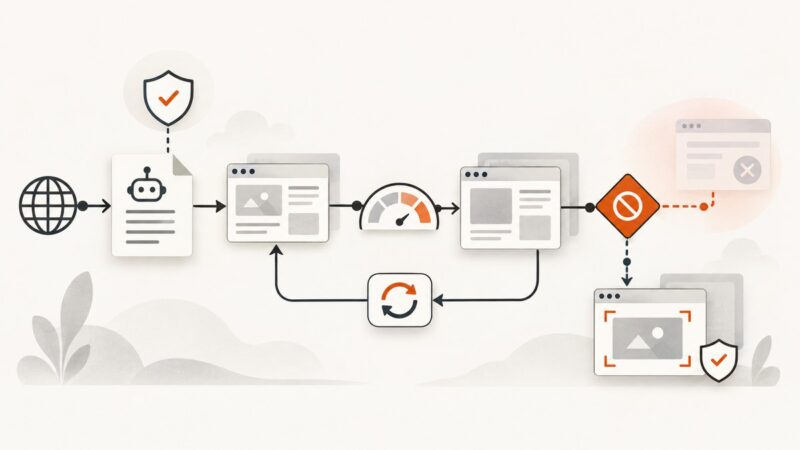
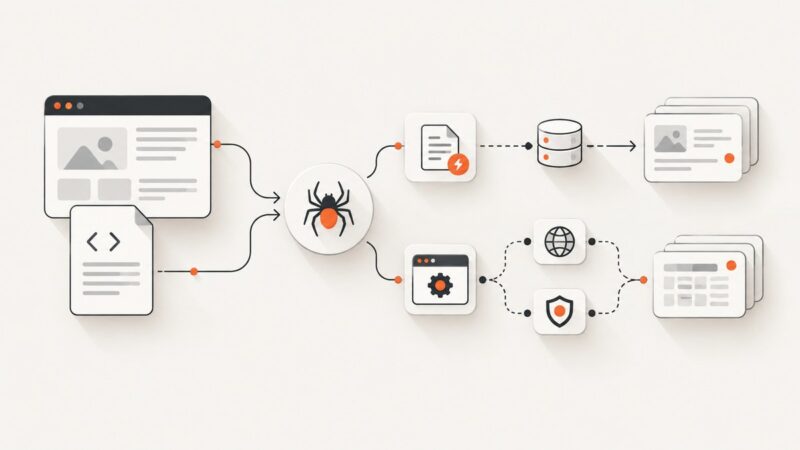
Learn when to use CheerioCrawler or PlaywrightCrawler, install Crawlee correctly, handle sessions and proxies, and build reliable scraping workflows.
Blog
How to take clean screenshots, turn HTML into images and PDFs, run headless browsers, and give AI agents eyes. Written by the team that builds ScreenshotNeo.
Learn when to use CheerioCrawler or PlaywrightCrawler, install Crawlee correctly, handle sessions and proxies, and build reliable scraping workflows.
Connect webhook events to browser automation reliably. Learn the trigger patterns, runnable examples, security, retries, and ways to handle long-running browser tasks.
Run browser automation for financial workflows on infrastructure you control. Set up Playwright, isolate credentials and sessions, and plan for operational and policy limits.
Link every screenshot to an account or pseudonymous ID in your app while keeping attribution, analytics, and privacy boundaries clear.
Learn when residential proxies help browser automation, how to configure them in Playwright, and how to handle routing, sessions, security, cost, and compliance.
Learn a reliable, permission-first scraping workflow: robots.txt, rate limits, retries, refusal handling, and safer screenshot automation.
Use BRAIN’s partner API for authorized product data. When you need public page fields, extract Product JSON-LD first and render JavaScript when required.
Configure Chrome domain allowlists for Playwright and other automation, verify policy scope, troubleshoot failures, and use a managed screenshot API.
Learn how to automate fintech browser workflows safely with Playwright, isolated accounts, protected session state, and auditable actions.
There is no reliable block-proof Instagram scraper. Learn the authorized API route, enforcement limits, compliant workflows, and safer screenshot options.
Deploy Playwright MCP locally or over HTTP, choose the right browser connection, protect session state, and troubleshoot reliable automation servers.
Learn what Cloudflare 1006, 1020 and 1015 mean, how to unblock access safely, and what to send the site owner.
Use BeautifulSoup’s sibling methods for values beside a label, or document-order traversal when the target is elsewhere. Includes runnable examples and fixes for common parsing surprises.
Use Playwright in TypeScript to capture webpages as JPEG, control quality and scale, save files or buffers, and handle full-page and element screenshots.
Configure Tor SOCKS5 for Python and browser scraping, prevent DNS leaks, and understand Tor’s limits, safe request rates, and alternatives.
Configure Playwright or Selenium sessions with the right browser, profile state, proxy, credentials and timeouts. Includes runnable examples and fixes for common failures.
Learn how to fetch HTML, parse it with Beautiful Soup, extract text, links and structured fields, and handle JavaScript, malformed markup and crawl limits.
Use Beautiful Soup sibling navigation to find the next or previous HTML node, skip whitespace, and select matching tags reliably.