How LLMs Read and Interpret Images
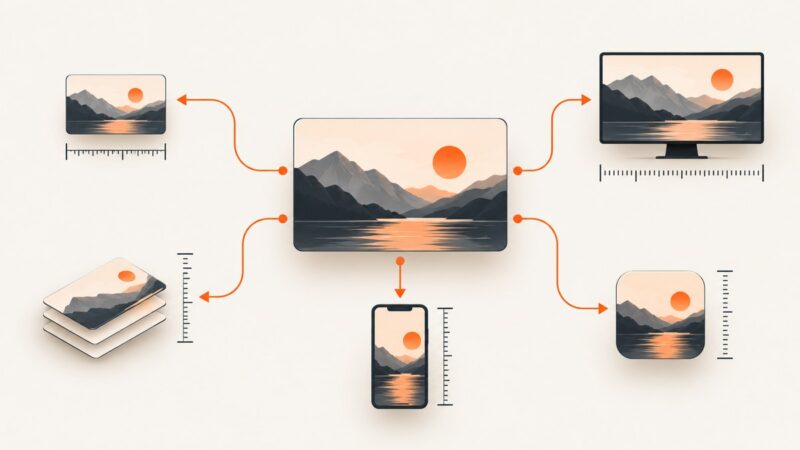
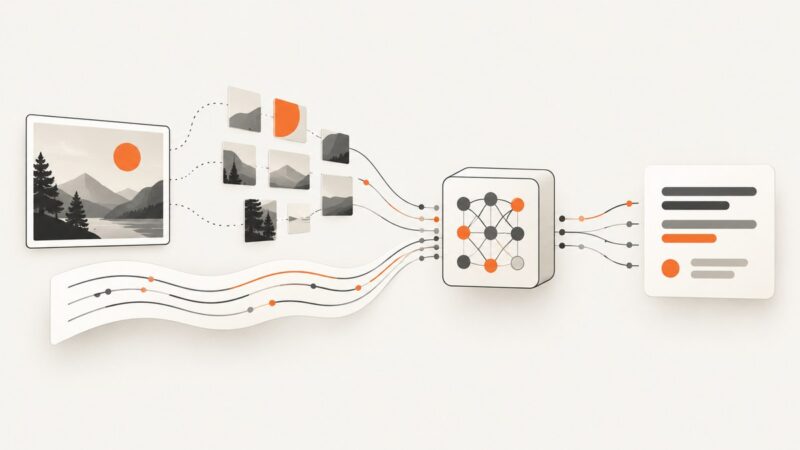
Image-capable LLMs combine visual representations with text prompts. Learn how image processing works, why resolution matters, and how to improve results.
Step-by-step guides to capturing the web: screenshots, full pages, elements, devices and more.
Image-capable LLMs combine visual representations with text prompts. Learn how image processing works, why resolution matters, and how to improve results.
Learn what og:image does, which dimensions to use, how to add it correctly, and how to fix wrong link-preview images.
Learn how to request website screenshots as WebP, handle binary or URL responses, configure captures, troubleshoot failures, and automate conversion.
Learn what Python Requests does, how to send reliable HTTP calls, handle JSON, auth, timeouts and errors, and capture pages with ScreenshotNeo.
Some crawlers follow robots.txt, but it is a voluntary protocol, not a security control. Learn what it can and cannot do, and how to protect private pages.
A request payload is the data sent in an HTTP request body. Learn how it differs from headers and form data, how to send JSON and other body types, and how to debug common mistakes.
Learn to fetch HTML and extract clean, structured data with Parsel using CSS, XPath, and JMESPath, with runnable examples and fixes for common pitfalls.
OAuth scopes are defined by each authorization server, so there is no universal list. Learn how to find the right scopes, check what was granted, and handle provider-specific behavior.
Learn Selenium’s Page Object Model with maintainable Java examples, stable locators, explicit waits, components, troubleshooting, and CI practices.
A practical framework for measuring social posts: choose the right goal, formulas, platform analytics, attribution, comparisons, and reporting.
Install Puppeteer with a compatible Chrome, fix common launch errors, and deploy headless automation in Linux and containers.
There is no universal screenshot maximum. Learn how pixel dimensions, file size, device class, and upload rules determine the limit.
Learn how to verify a professional license using official state databases, Nursys, or NIPR—and how to document results correctly.
Web scraping is worth learning when it supports a real, permitted project. Learn the skills, tools, limits and a practical path from one page to reliable crawls.
There is no universal best language for web scraping. Choose based on how pages render, your workload, your team’s tools, and the cost of operating a browser.
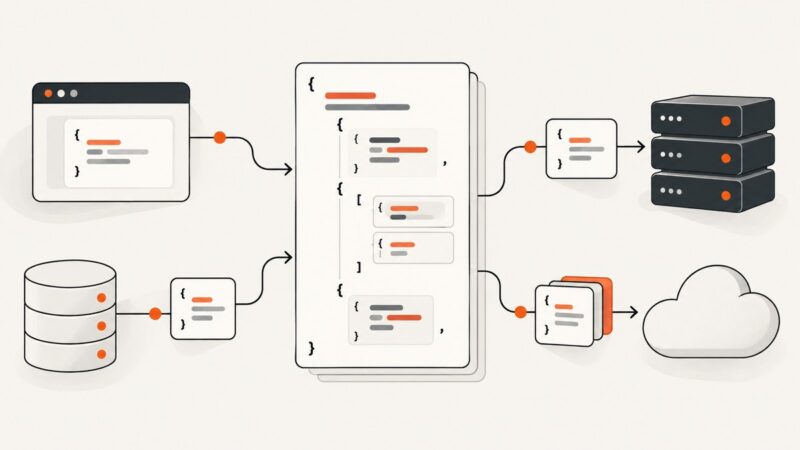
JSON is a text format for exchanging structured data. Learn its six value types, syntax rules, JavaScript differences, parsing, validation, and safe API use.
Public sources show Bet365 restricts certain automated access and report one historical Selenium detection, but do not reveal how its current checks work.
Learn how to run Ollama locally, choose hardware and context sizes, verify GPU use, fix common errors, and connect local models to your tools.